A 2016 notebook portfolio at version 2.0.0, with gensim dropped for a missing 3.14 wheel
Portfolio of data science projects completed by me for academic, self learning, and hobby purposes.
At a glance
- What is it?
- A collection of student-era notebooks declared not to be a package, yet carrying version 2.0.0 and a hard Python 3.14 floor. The modernization is documented in the dependency comments rather than in a changelog: gensim was dropped for an absent wheel and its word2vec step rewritten in numpy, yfinance replaced a dead Yahoo backend, and the digit notebook moved to PyTorch.
- Who is it for?
- The most transferable thing here is the habit the dependency comments show: every removal names its reason and its date, so a reader six months from now can tell whether a gap was deliberate or an oversight. gensim is gone because there was no 3.14 wheel as of 2026-07 and the source build failed, and rather than lose the word2vec step the author reimplemented it in numpy. That is the standard worth copying.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 131 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
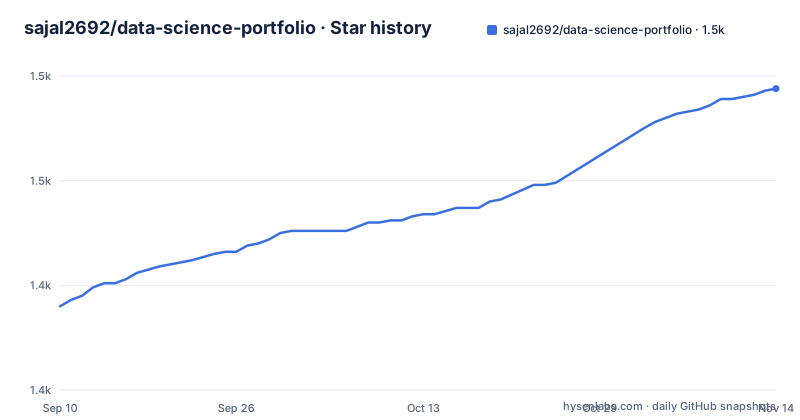
- sajal2692/data-science-portfolio1,494 ★ · +104
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| sajal2692/data-science-portfolio | 1.4k | 1.5k |
104 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Version 2.0.0 on a project that says it is not a package
The project metadata carries a name, a version of 2.0.0 and a description reading that this is a portfolio of data science projects, modernized to run on a current Python stack. Two lines below the dependencies, a tool section sets package to false and comments that this repo is a collection of notebooks, not an installable package. So the version number is a label for the modernization effort rather than a distribution version, and there are no GitHub releases behind it either. The README frames the same idea in prose, saying the projects were built early in the author's career around 2016 and that the repository has been refreshed so every notebook runs top to bottom, with the author's current AI engineering work pointed at a separate personal site. The last push is dated 2026-07-07, so the refresh described as done in 2026 is a few months old.
Three dead dependencies were replaced, each with its reason in a comment
The dependency list is where the modernization is actually documented, because each substitution carries an inline comment stating the reason. First, gensim is intentionally omitted, with the note that there was no cp314 wheel as of 2026-07 and that its source build fails on Python 3.14, and that the sentiment notebook's word2vec use has been reimplemented in numpy. So a library was not quietly forgotten, it was worked around. Second, yfinance at 0.2.50 or newer is annotated as replacing the dead pandas-datareader Yahoo backend, which is a data source outage rather than an upgrade. Third, torch and torchvision are labelled as the deep learning pair for a digit recognition notebook that was rewritten in PyTorch, meaning the original implementation was in a different framework. Three separate dead ends, three different remedies, one comment each. The rest of the list is plain lower bound ranges with no commentary at all: numpy and pandas at 2.2, scipy at 1.14, scikit-learn at 1.5, matplotlib at 3.9, seaborn at 0.13 and nltk at 3.9, then pillow, tqdm, requests, lxml and the Jupyter tools. The MIT licence is written in the table form with a text key rather than as an SPDX string, and the readme field points at a lower case readme.md, which matches the filename in the tree rather than the capitalised README.md most tooling expects.
requirements.txt is a generated export, not a second dependency list
The pip path is not hand maintained. The file opens with a header naming the command that produced it, an export with the no hashes and no emit project flags, and every entry below is pinned with an exact version and followed by a comment tracing which package required it. So the file is a snapshot, and anything written into it is lost the next time the export runs. That matters because the README offers it as an alternative to the uv path: uv sync resolves the declared ranges fresh, while pip install from this file installs exactly the frozen set that was current when the export was made. The trace comments also show the dependency weight that the project metadata hides, with yfinance pulling curl-cffi and beautifulsoup4, torch pulling filelock, matplotlib pulling fonttools, and platform markers narrowing appnope and colorama to macOS and Windows and the cuda packages to Linux.
Three different stories for where the data comes from
The README separates data provenance into three cases, which is unusual care for a portfolio. Most notebooks read small datasets committed under the data directory, and those are marked as being for demonstration purposes only. Two notebooks fetch on first run and cache: the digit recognition notebook downloads MNIST through torchvision, and the stock market notebook pulls technology stock prices through yfinance, with a vendored snapshot named as a fallback so it still runs offline. The third case sits in individual entries rather than in the running instructions: the 2016 United States general election poll data was recovered from the Internet Archive, and the 911 calls dataset is identified as coming from Kaggle. So a notebook's reproducibility depends on which of the three categories it falls into, and only the first is guaranteed by the repository itself.
Three projects in the contents list live in other repositories
The contents section reads as one flat list, but the entries resolve to three different places. Most point at notebook paths inside this repository, including the Boston housing, CharityML donor, customer segment and digit recognition projects under their own directories, plus the Titanic, stock market, election poll, 911 calls, tweet sentiment, cross language retrieval, Yelp and SMS notebooks at the top level. Three do not: the reinforcement learning Smartcab project, the disaster message classifier and the Melbourne walkability analysis each link to a separate repository under the same account. Four more are R analyses published on RPubs rather than stored here at all, covering a behavioural risk factor survey, an inferential statistics exercise, a corruption and development visualisation and a Moneyball exploration. Nothing in the list marks which entries you can open in this checkout. The tree itself does carry a directory for the short exercises and one for the data, alongside the notebooks at the top level and the two project files, so the shape of what is local is discoverable from the checkout even though the contents list does not say so.
One notebook explains a dataset the library no longer ships
The Boston housing entry is described as building and tuning a decision tree regressor to predict home values and then evaluating how reliable those predictions are, and it is the one entry that carries an editorial note: a note on the dataset's history and why it was retired from scikit-learn. That note does real work, because the project pins scikit-learn 1.5 or newer and the dataset is no longer part of that library, so a reader who tries to load it the way the original notebook did will not find it. The opposite approach appears in the cross language retrieval project, which aligns a German query against English documents using IBM Model 1 and scores with a BM25 and language model scorer built from scratch, needing no retrieval library at all. The digit recognition notebook takes a third route, reading one to five digits from a single image with five classification heads on a shared convolutional trunk and synthetic data built from MNIST. The listing for that notebook also names Pygame alongside the usual scientific stack, which points at the reinforcement learning project it was built next to rather than at the convolutional work itself. The rest of the machine learning group is conventional coursework: a decision tree regressor on the Boston data, a supervised comparison whose target is whether an individual earns more than fifty thousand dollars a year so a fictional charity can identify likely donors, and an unsupervised project using principal component analysis with a Gaussian mixture model to find structure in wholesale customer annual spending. The analysis group adds a Monte Carlo value at risk simulation to the tech stock notebook, and lists Pandas, Seaborn and Matplotlib as its tools.
The sentiment notebook carries both the 2016 model and a transformer
One notebook documents its own obsolescence, which is the clearest sign of how the refresh was done. The tweet sentiment project is described as three-way polarity classification into positive, negative and neutral, built from hand-built features and a logistic regression classifier, and the entry then notes a modern zero-shot transformer baseline using a roberta model for tweets sitting alongside it for comparison. The project metadata confirms the intent, annotating the transformers dependency as the baseline for that sentiment notebook rather than as the main model. The word2vec stage sits in the same notebook, and is the step that had to be reimplemented once gensim became uninstallable. So a reader sees the original feature engineering and a current model measured against it, in one file, which is more informative than either alone.
A hard 3.14 floor on a teaching artifact
The floor is stated three times and enforced rather than suggested. The project metadata sets requires-python to 3.14 or newer, the README describes the environment as Python 3.14 managed with uv, and a .python-version file sits in the tree. The notebook toolchain underneath is a current Jupyter stack with JupyterLab, nbconvert, ipykernel and ipywidgets, so working through the collection means running a lab rather than executing scripts. The two documented entry points are:
uv sync
uv run jupyter labpip install -r requirements.txtThat combination makes the portfolio easy to start and hard to share: on a machine without 3.14 nothing in it runs, and on a machine with it the dependency floors are recent enough that the export in requirements.txt may not match what a fresh resolve produces. The low floor on nothing else, with a high floor on the interpreter itself, is an unusual shape for a notebook collection.
Editorial conclusion
The most transferable thing here is the habit the dependency comments show: every removal names its reason and its date, so a reader six months from now can tell whether a gap was deliberate or an oversight. gensim is gone because there was no 3.14 wheel as of 2026-07 and the source build failed, and rather than lose the word2vec step the author reimplemented it in numpy. That is the standard worth copying. Two cautions before you point a learner at it. The Python 3.14 floor is real and enforced in the project metadata, so on an older interpreter nothing runs, which makes this an awkward teaching artifact for a machine you do not control. And the portfolio is explicitly historical: the notebooks are from around 2016, the author points elsewhere for current AI engineering work, and the Boston housing project exists partly to explain a dataset scikit-learn no longer ships. Treat it as a record of how the problems were framed then, with two modern baselines grafted on, rather than as a current reference. If you want the projects rather than the pedagogy, the dependency set is small and every pin is visible in one file.
Frequently asked questions
What should go in a data science portfolio?
This repository is an example rather than advice. It groups its work as machine learning, natural language processing, data analysis and visualisation, and micro projects, plus four R analyses published on RPubs. Each entry states the technique used and the tools, and the Boston housing entry adds a note on why the dataset was retired from scikit-learn.
How do I run the notebooks in this data science portfolio?
With uv, uv sync followed by uv run jupyter lab, on Python 3.14. Or with pip install -r requirements.txt, which installs a frozen export generated by uv with the no hashes and no emit project flags. The project sets requires-python to 3.14 or newer and declares package = false, because the repository is a notebook collection rather than an installable package.
Where does the data in this data science portfolio come from?
From three different places. Most notebooks read small datasets under data/, marked as for demonstration purposes only. The digit recognition notebook downloads MNIST through torchvision on first run, and the stock market notebook pulls tech stock prices through yfinance with a vendored snapshot as a fallback. The 2016 election poll data was recovered from the Internet Archive.
Are all the projects in this portfolio in the same repository?
No. Most are notebooks here, but the Smartcab reinforcement learning project, the disaster message classifier and the Melbourne walkability analysis each link to their own repository under the same account. The four R analyses are published on RPubs. The contents section does not mark which entries are stored locally.
Why does this data science portfolio require Python 3.14?
The project metadata sets requires-python to 3.14 or newer, the README describes a Python 3.14 environment managed with uv, and a .python-version file is in the tree. The modernization pushed the floor up rather than down, and one dependency was dropped over it: gensim has no cp314 wheel as of 2026-07 and its source build fails on 3.14.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sajal2692-data-science-portfolio)Star history chart for your README
[](https://hysenlabs.com/projects/sajal2692-data-science-portfolio)Was this useful?