Knowhere's Python workspace is a publication workspace at version 0.1.0
Knowhere extracts, parses, and outputs structured chunks ready for AI Agents and RAG.
At a glance
- What is it?
- Knowhere parses documents into navigable memory for AI agents, through two parsing tracks that converge on one schema. The repository behind it went open source in May 2026, ships no runtime dependencies of its own, and points its readers at a managed API in the first box of its README.
- Who is it for?
- Knowhere is worth looking at if you are building retrieval over documents that OCR handles badly, because the case it makes is that perfect element-by-element extraction is not a prerequisite for recall, and the Vision Track is the concrete answer to that. Three things to weigh.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
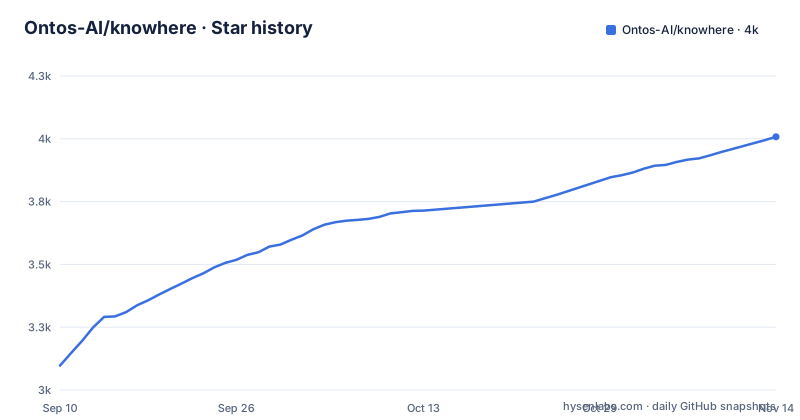
- Ontos-AI/knowhere4,008 ★ · +911
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| Ontos-AI/knowhere | 3.1k | 4k |
911 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The workspace is a publication workspace at version 0.1.0
The packaging metadata at the root is not the product. Its name ends in api, its version is one point zero point zero, and its description calls it a publication workspace. The tool configuration also says the root is not a package, which is why the metadata has no runtime dependencies at all: not an empty decision, but the correct statement for a workspace that exists to hold three members. Those members are an API application, a worker application, and a shared Python package, and they are where the real dependency lists live. So a reader who installs this repository gets nothing, and a reader who wants the service has to work out which member application they need. The release tags, meanwhile, are in the 1.2 line, which is the product's version rather than this file's.
The project was closed source until May 2026
The news section dates the open-sourcing: on May 7, 2026 the maintainers say they open-sourced the entire stack for document ingestion, parsing and agentic retrieval, and point at a separate self-hosting repository. Three months later came support for very long documents, with the pipeline handling PDFs of hundreds of pages and routing technical atlases or drawing collections through a dedicated layout-aware parser. In September came the two-track parsing release and then an agent-native retrieval release. That is four substantive changes in four months on a codebase that was closed until May, which is fast enough that the release history reads as a series of launches rather than an evolution. The most recent releases visible are two patch versions published on the same day, hours apart.
The first box in the README points at a paid managed API
Before the overview there is a note box, and it is not documentation. It says to get started in seconds with the hosted version, to avoid the complexity of self-deployment, to use the managed service, and that registration comes with five dollars in credits. So the readme of an Apache-licensed repository opens by steering readers to a commercial endpoint, and the self-hosting path it points at is a different repository. That is a legitimate arrangement for a company that open-sourced its stack, and it is also the first thing a reader encounters, which shapes the impression of what the project is. The rest of the header links out to four places: the website, the documentation site, the self-hosting repository and a dashboard repository.
The first version depends on an external extractor, the second replaces it
The readme's own question-and-answer section is the most informative paragraph about the architecture, and it is cut off mid-sentence. The question asks about the relationship with a separate PDF extraction project, and the answer says that project remains the default raw extractor for the first generation chunk-based pipeline, while PDF and PowerPoint uploads through the second generation API use the vision page path instead, rendering source pages and combining their visual interpretation with document profiling and the table of contents structure. So the migration is visible in the product's own history: version one shells out to an extractor, version two reads pages with a vision model. The answer then stops mid-clause, and no further relationship is described anywhere else on the page.
The Makefile has no full test target
The build file declares five targets, and four of them are checks: lint, a fix variant of lint, a type check, and a combined check that runs both. The fifth is a single test target, and it is scoped to one directory of one application: it changes into the worker application and runs pytest on its document agent tests. There is no target that runs the full suite, so the difference between a passing check and a passing test suite is the difference between running one command and knowing which paths to pass yourself. The type check is more thorough than that: it runs the checker against the project configuration and then an explicit list of five source paths.
A deprecated directory is excluded from both checkers
The repository root contains a directory named for deprecated work, and it appears in the exclusion list of both the linter configuration and the type checker configuration, alongside build output directories, caches, virtual environments and two test directories. Keeping it is a choice with a cost: the tree stays larger, the two checkers have to carry the exclusion forever, and anyone searching the repository for how something used to work will find it. It is also the only entry in the listing that tells you the project has a past rather than a clean start. The rest of the root is conventional governance and configuration: a citation file, a notice, a security policy, a code of conduct, a context file and an agent instructions file.
The linter is told 88 columns and then told to ignore the check
The linter configuration sets a line length of 88 and then selects two rule families, one for style errors and one for correctness, while adding a single entry to the ignore list: the line-length rule itself. So the formatter will reformat lines to 88 columns and the checker will not complain if a line exceeds them. That is a common and reasonable combination, since a formatter and a linter disagreeing about the same rule wastes a reviewer's time. What is worth knowing is that the value is still there and still doing work for the formatter. Two per-path exemptions follow the same logic: unused-import warnings are silenced in package initialisers, and import-order warnings are silenced in the two test directories.
One product, three repositories and a cache probe
The packaging of this project is spread across more places than the readme suggests. There is the core repository you are looking at, a self-hosting repository for running the platform, and a dashboard repository, plus a container registry that the header badges point at. The build file adds one more piece of machinery that is worth understanding before you run anything: before any target executes, it probes whether the user cache directory is writable, walking up from the tool's own cache directory to the general cache directory to the home directory, and falls back to a repository-local cache if none of them is writable. That is a fix for shared or read-only cache directories on build machines, implemented as a shell expression inside the makefile.
Editorial conclusion
Knowhere is worth looking at if you are building retrieval over documents that OCR handles badly, because the case it makes is that perfect element-by-element extraction is not a prerequisite for recall, and the Vision Track is the concrete answer to that. Three things to weigh. It was open sourced five months ago with version numbers already in the 1.2 range and several releases a day, so the release history is short and fast. The self-hosting story lives in separate repositories, so you are adopting a stack rather than a library. And the Python workspace in this repository is a publication workspace with no runtime dependencies, which means the dependencies you actually need are one level down in the member applications.
Frequently asked questions
What does Knowhere do?
It turns documents into persistent, navigable memory for AI agents: parsing, hierarchy reconstruction, multi-modal structuring and graph construction in one pipeline, with every chunk kept connected to its document, section, source pages and related assets.
What are the Vision and Text tracks in Knowhere?
Two parsing paths that converge on one chunk and metadata schema. The Text Track preserves native text structure where it is reliable, while the Vision Track sends a page or slide to a frontier vision model as a whole. PDF and PowerPoint uploads through the V2 Jobs API use the Vision Track.
Is Knowhere open source?
The news timeline says the whole stack was open sourced on May 7, 2026, with a separate repository for self-hosting the platform. Documentation, a dashboard repository and a container registry sit alongside the core repository.
What is MapNav in Knowhere?
It appears once, in the September 2026 news entry, which says MapNav evolved from a fixed navigation workflow into a corpus-native foundation for agents, with the agent deciding how to search, traverse, read and cite.
How do you run the Knowhere checks?
Through the Makefile: a lint target and a fix variant, a type check that runs the checker against the project configuration and an explicit path list, a combined check target, and one test target that runs only the document agent tests in the worker application.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 0 in the last 30 days; newest first.
- Show HN: Knowhere-Rebuilds the document structure that chunking throws awayHacker News · Sep 17, 2026 · 1 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ontos-ai-knowhere)Star history chart for your README
[](https://hysenlabs.com/projects/ontos-ai-knowhere)Was this useful?