opentelemetry-js ships stable at 2.11.0 and experimental at 0.222.0, and teaches CommonJS
OpenTelemetry JavaScript Client
At a glance
- What is it?
- The JavaScript client for OpenTelemetry, Apache-2.0 licensed, published as a large set of packages across an API, a stable SDK and an experimental track. Three things are worth knowing before you adopt it. The quick start is written for CommonJS in an ESM-first era and says so in its own first bold sentence. Browser instrumentation is declared experimental and mostly unspecified. And the TypeScript floor belongs to another organisation's support window, with drops landing in minor releases.
- Who is it for?
- opentelemetry-js suits a Node.js service that wants vendor-neutral tracing and metrics and is prepared to depend on the API rather than on a particular SDK, because that boundary is the whole point of the split and the readme states the failure mode of violating it. Five things to check first.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
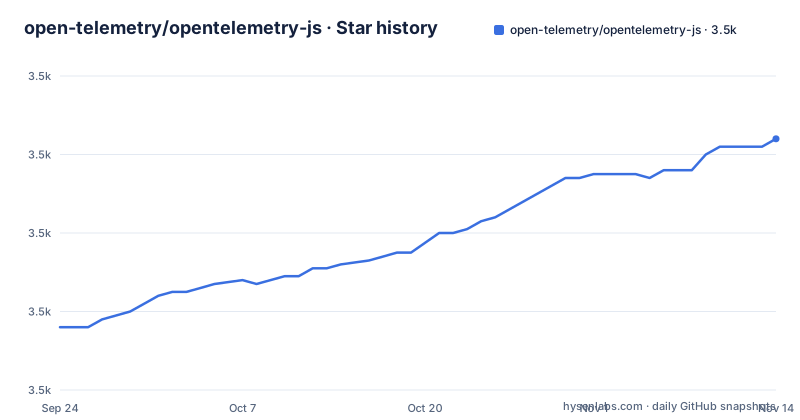
- open-telemetry/opentelemetry-js3,524 ★ · +48
| Repository | 2026-09-24 | 2026-11-14 |
|---|---|---|
| open-telemetry/opentelemetry-js | 3.5k | 3.5k |
48 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The quick start teaches CommonJS
The first bold sentence in the quick start is a warning about the module system, and it is the most useful line in the file.
It says that much of the documentation is written assuming the compiled application runs as CommonJS, and points to a separate document on module support for the details.
The example that follows is unambiguously CommonJS. It opens with a strict-mode directive, uses the `require` form for every import including the SDK, the auto-instrumentation bundle, the trace SDK, the resources package and the semantic conventions, and the run command loads the file through a preload flag:
node -r ./tracing.js app.jsThat is a preloading approach, and it is the right shape for a library that has to install instrumentation before your application code runs. It is also a shape that a pure ESM application cannot use directly, because ESM has no equivalent of preloading a module before the entry point.
So the practical situation for a modern service is that the documented path is not the one you would choose, and the readme tells you so in its first bold line rather than leaving you to discover it. That candour is worth crediting. It also means the friction lands at the start of your integration rather than after you have written code.
The examples directory reflects the same skew: six example directories, of which exactly one is an ESM TypeScript example.
Stable is 2.11.0 and experimental is 0.222.0
This is the versioning fact that confuses people installing their first package, and it is visible in the tags alone.
The recent releases include a stable tag at 2.11.0 and an experimental tag at 0.222.0, published sixteen seconds apart. The stable line is therefore past two, and the experimental line is past two hundred while still being below one.
That is not a mistake, it is the design. The project releases a set of distinct packages in three categories: the API, the stable SDK, and experimental packages. The API lives in one directory, the stable SDK in another, and experimental packages in a third, with the note that there may also be API packages for experimental signals inside the experimental directory.
The rule that explains the numbers is that all stable packages are released with the same version, while experimental packages move independently. So the stable set moves in lockstep, and the experimental set moves at its own much faster cadence, which is why it has reached a three-digit pre-1.0 number while stable is still at two.
Practically, this means you cannot reason about versions across the boundary. A dependency on an experimental package pulls a different version number from one on the stable SDK, and the two will not tell you anything about each other by comparing numbers.
On installation, the guidance is deliberately loose: dependencies carrying the latest tag are stated to be compatible with each other, with a pointer to a version compatibility matrix for more detail. That matrix is the section the readme leads you to, and the visible text stops before completing it.
Browser support is called unspecified and then carries three Karma configs
There is a real tension in this repository between what the documentation says about browsers and what the repository does for them.
The documentation is unusually blunt. An important callout states that client instrumentation for the browser is experimental and mostly unspecified, and invites readers who are interested to get in touch with a special interest group.
The policy underneath it is coherent. Rather than define supported versions of specific browsers or runtimes, the project sets the minimum based on the underlying language features used. That minimum is currently the ECMAScript edition named in the file, and the reasoning is given: those features are available in all modern browsers and runtimes. Below that line, you are told to transpile and polyfill, and then told plainly that any support issue arising from an older runtime will be closed as won't fix. That minimum is also stated to be subject to change as the project and the language evolve.
Now the repository side. There are three Karma configuration files at the top level, a base, a webpack one and a worker one. There are three separate test directories for bundler, end-to-end and integration testing. And the root scripts define distinct targets for testing in a browser and for testing in a web worker, in addition to the node, bundle and two benchmark targets.
So browser instrumentation is unspecified as an interface while carrying a substantial test apparatus. That is not a contradiction, since testing what exists prevents regressions without committing to the surface. But a reader looking for a compatibility guarantee will not find one, and a reader counting test targets may reasonably assume more stability than the callout promises.
The TypeScript floor belongs to another organisation
The TypeScript support policy in this repository is a pointer to somebody else's policy, and the consequence is worth understanding.
The project says it is built with a named TypeScript version and recommends that a consuming project use the same or a higher version to compile. So there is a floor, and it is a specific number rather than a range.
The window, though, is not the project's. It says it will follow the support policy that the DefinitelyTyped project publishes for TypeScript, and that this policy sets a window of two years. Support for TypeScript versions older than two years will be dropped in minor releases of this project.
That last clause is the important one. A language-toolchain support drop arrives in a minor version bump of the SDK, not in a major one. So if you pin to a minor version to avoid a breaking change, you can still lose TypeScript compiler support, because the drop is classified as minor.
For most consumers that is fine, since TypeScript support windows are generous relative to upgrade cadence. For a library author publishing types, it matters more, because your consumers' compilers are your problem. And the readme's own guidance to library authors is about API surface rather than toolchain, so this constraint sits in a different section from the one aimed at people who publish packages.
The practical read is that you should track this project's minor releases even if you are cautious about major ones, and check the stated compiler version against your own before upgrading.
Building requires a git submodule and a protobuf step
The root build is a task graph runner, and two of its first steps are about source that is not in this repository.
The compile script has a pre-step. It runs a submodule target and then a protobuf generation target across the workspace. The submodule target synchronises submodules recursively and updates them recursively, and there is a submodule configuration file at the top level.
So the protocol buffer definitions this project compiles against live in a submodule, and the generated code is produced as part of building. You cannot compile this repository from a plain clone without initialising submodules, and the proto sources are not vendored into the tree.
Everything else in the build follows the same pattern. Compile, watch, clean, test, lint and version updates are each a single call that fans out across all workspace projects for one target name. Documentation is not part of that graph: it runs TypeDoc with the readme suppressed, then touches a no-Jekyll marker file so the output is not processed when published.
Two scripts are worth singling out because they are the kind of thing mature repositories add after an incident. One verifies what actually ended up inside the published package, by running a dedicated script. The other link-checks the generated documentation and the hand-written documents together, with retries, directory-listing checks, and an explicit skip list of domains whose pages it should not treat as its responsibility.
That skip list includes a local development port, a second port, and three public sites. A link checker that needs to be told which links not to check is a link checker that has already been burned.
Nx runs the tasks and Lerna does the versioning
Two orchestration tools sit side by side in the root, and dividing the work between them explains the shape of the scripts.
One of them is the task runner. Every build, watch, clean, test, benchmark and lint script in the root manifest is a single call that runs one named target across all projects. That is the whole of the build system as far as a contributor is concerned, and it is why there are only about twenty root scripts despite the repository containing an API, a stable SDK, an experimental set and several test suites.
The other one is a workspace and release tool, configured in its own file at the top level, and the version-update script is the one that fans out for it. So task execution and version management are two separate concerns handled by two separate tools.
The package manager is npm, evidenced by a lockfile and a project configuration file, and there is a workspace file for the package-manager workspaces alongside the task-runner configuration.
Also present at the top level are two quality configurations for coverage: one for the local coverage tool and one for the hosted coverage service, which is also badged in the readme. A markdown lint configuration, a Prettier configuration, and a flat ESLint configuration.
Two automation configurations are more unusual. One file configures a commit message format checker, which means commit messages are validated. Another configures the dependency update bot, which means dependency bumps arrive as automated commits. Those two together are what make the generated changelog readable, since the changelog is produced from those same commit messages.
Telemetry arriving nowhere is silent until you enable diagnostics
The debugging section is short and it addresses the single most common way this kind of library fails.
It starts by saying an application instrumented as described may not behave as expected. The example given is the canonical one: the application is meant to be sending data to a collector, and the collector is not receiving anything.
Note what is not there. No error, no warning, no non-zero exit. The telemetry pipeline failing to deliver produces silence, because the instrumentation is wrapping code that runs correctly and the exporter is failing quietly at the edge.
The fix is to enable an internal diagnostics logger through the API package, passing a console logger implementation and a debug level. The file shows it as additional configuration to the tracing setup file you already have.
Two details make this easier than it could be. The diagnostics logger comes from the API package rather than the SDK, so it is available even if your SDK wiring is what is broken. And it is set on a global diagnostic object rather than passed through the SDK constructor, so you can turn it on without restructuring your configuration.
The general lesson is worth carrying to any instrumentation library: absence of data is not a signal. If you are deploying telemetry, confirm the pipeline delivers something before you trust a dashboard built on it, and keep the diagnostic switch in your debugging notes rather than in your memory.
The example code block stops mid-identifier
Small completeness problems are worth noting in a project this large, because they are the kind of thing that tells you about the review process.
The tracing example in the quick start is cut off. It declares the exporter variable and begins constructing a console span exporter, and then the block ends partway through the identifier. The line reads as a partial constructor call with nothing following it.
So the code that a reader will reach for when copying verbatim does not run as printed. Everything before that line is complete and correct: the strict-mode directive, the requires, the comment explaining that the SDK is being configured to export to the console, and the comment noting that all auto-instrumentations from the meta package are enabled.
Two other boundaries are worth naming in the same way, because they are all places where the readme points onward.
The installation section says that dependencies with the latest tag should be compatible with each other and refers the reader to a version compatibility matrix for more information. That matrix section begins and does not complete within the visible text.
And the package version compatibility section itself ends mid-sentence, after stating that all stable packages share one version and that all experimental packages do something else.
None of this makes the documentation unusable, and the surrounding prose consistently points at a getting-started guide and a website for detail. But the three places where a reader would most want a complete answer are the three that stop early.
Editorial conclusion
opentelemetry-js suits a Node.js service that wants vendor-neutral tracing and metrics and is prepared to depend on the API rather than on a particular SDK, because that boundary is the whole point of the split and the readme states the failure mode of violating it. Five things to check first. Which version line you are on, since stable and experimental move on different numbering and the experimental number is numerically far larger while being pre-1.0. Whether your build is ESM or CommonJS, since the documented quick start is CommonJS with a preload hook and the module-system caveat is stated up front. Which Node.js versions you support, because only Active and Maintenance LTS lines are tested. Whether you need browser support at all, since it is declared experimental and mostly unspecified with a will-not-fix policy below the language-feature floor. And which TypeScript version you compile against, because the floor is set by an external support window rather than by this project.
Frequently asked questions
What is OpenTelemetry used for?
It is a framework for collecting traces, metrics and logs from applications, and this repository is its JavaScript version. The root package description calls it a distributed tracing and stats collection framework. The JavaScript client publishes an API, a stable SDK and a set of experimental packages.
Is OpenTelemetry free or paid?
The license recorded for this repository is Apache-2.0, and it is installed from npm as a set of packages. No paid tier, subscription or hosted component is described in this repository; the getting-started material and the API reference are both linked as free documentation.
What Node.js versions does opentelemetry-js support?
The support table marks Node.js v26, v24 and v22 as supported, and the policy text says only Active or Maintenance LTS versions are supported. Previous versions may work but are stated to be neither tested nor guaranteed to work. Browser support is handled separately and is described as experimental and mostly unspecified.
Is OpenTelemetry difficult to learn?
This repository makes no usability claim and offers no learning path. What it does state is where the detail lives: a getting-started guide, an API and SDK reference site, an examples directory containing six examples of which one is ESM TypeScript, and a separate document on module-system support because much of the documentation assumes CommonJS.
What is the difference between telemetry and OpenTelemetry?
The repository defines only its own scope, describing itself as a framework for collecting traces, metrics and logs and as a distributed tracing and stats collection framework. It does not define telemetry itself, and the linked documentation is where that would be covered.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/open-telemetry-opentelemetry-js)Star history chart for your README
[](https://hysenlabs.com/projects/open-telemetry-opentelemetry-js)Was this useful?