BMInf, a CUDA kernels layer that turns an ordinary model into a 10-billion-parameter one on a 6GB card
Efficient Inference for Big Models
At a glance
- What is it?
- BMInf 2.0.1 wraps a transformer in a block list and a quantized linear layer, with the CUDA kernels in a submodule. Here is the wrapper contract, the reported speeds, and how the version number is resolved.
- Who is it for?
- BMInf is worth reading if you are stuck: the model is larger than the card, the framework does not fit, and buying hardware is not on the table this quarter. The wrapper contract is small enough to understand in a minute, the escape hatch to manual replacement is documented, and the benchmark scripts are in the repository so you can measure on your own GPU instead of trusting a table.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 131 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
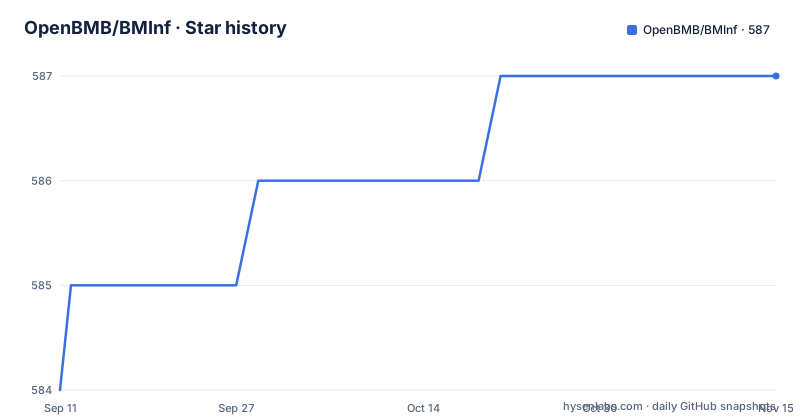
- OpenBMB/BMInf587 ★ · +3
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| OpenBMB/BMInf | 584 | 587 |
3 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
10 billion parameters on a 6GB card, with compute capability 6.1 as the floor
The claim the package is built around is narrow and specific: models of more than ten billion parameters, on a single GTX 1060, at the minimum configuration. The hardware table gives 16GB of system memory, a 6GB GTX 1060, and PCI-E 3.0 x16 as the floor, rising to 24GB and a 16GB Tesla V100 as the recommended setup. Any GPU with compute capability 6.1 or higher is supported, with a link to the CUDA support table to check yours. The mechanism underneath is a `.gitmodules` entry and a `cuda/` directory, so the fast path is custom kernels rather than something PyTorch does for you. Above the floor the project also claims an improvement over stock PyTorch on V100 and A100 hardware.
`bminf.wrapper` converts a model in four lines
The entire quick start is: build the model on CPU, load its state dict, then wrap it inside a device context.
import bminf

# initialize your model on CPU
model = MyModel()

# load state_dict before using wrapper
model.load_state_dict(model_checkpoint)

# apply wrapper
with torch.cuda.device(CUDA_DEVICE_INDEX):
    model = bminf.wrapper(model)
Three things in that snippet carry the design. The model is constructed on CPU, so nothing has to be allocated on the small card before the memory-saving representation exists. The state dict is loaded before wrapping rather than after, which means the wrapper is dealing with weights you already have rather than reloading them. And the device index is supplied as a list to the wrapper, because a 10-billion-parameter model does not fit on one device and the placement is the point.
When the wrapper does not fit, two replacements are offered
Automatic conversion covers most models, and the manual path is two substitutions rather than a rewrite. Any `torch.nn.ModuleList` becomes `bminf.TransformerBlockList`, taking the block list and the list of CUDA device indices:
module_list = bminf.TransformerBlockList([
	# ...
], [CUDA_DEVICE_INDEX])
And any `torch.nn.Linear` becomes `bminf.QuantizedLinear`:
linear = bminf.QuantizedLinear(torch.nn.Linear(...))That is the whole extension surface. If your model is an ordinary stack of transformer blocks and linear layers, which is what 2.0.0 generalised the package to cover, these two calls are enough to get the memory behaviour without the wrapper guessing anything about your architecture. The block list constructor takes the device indices as its second argument, which is how a model gets spread across more than one card, and the quantized linear takes the layer it replaces rather than a shape or a count, so it composes with whatever you already built.
The reported decoder speed is 26 against 7 tokens per second on an A100
The performance section is the project's own measurement of CPM2 encoder and decoder throughput across five GPUs, and it invites you to check it rather than take it. The decoder column is the interesting one: 4.4 tokens per second on a GTX 1060, 12 on a 1080Ti, 19 on a 2080Ti, 20 on a V100, and 26 on an A100, with the stock PyTorch rows showing 3 on a V100 and 7 on an A100. So the decoder gain is several times on both server cards. The encoder column runs from 718 to 4365 tokens per second and has no PyTorch baseline beside it, which tells you the comparison is about decode-bound generation rather than about forward passes in general. You can run the two benchmark scripts named in the README to get your own numbers.
Building from source writes a version file into the package
The version number is resolved by a cascade in `setup.py` rather than being written down, and the cascade ends somewhere you would not expect. It checks a hardcoded value first, then the `BM_VERSION` environment variable, then `CI_COMMIT_TAG`, then `CI_COMMIT_SHA`, then a `bminf/version.py` file if one exists, and if none of those produce anything it returns the literal string `test`. Worse for reproducibility, `setup.py` then writes `__version__` into `bminf/version.py` as part of running. So an ordinary source build mutates a file inside the package directory. Combined with a CI tag environment variable in the chain, a build from a branch with no tag can end up reporting itself as `test`.
requirements.txt pins torch not at all and still expects cpm_kernels
Installation is one line, `pip install bminf`, or a source build with `python setup.py install`. The software requirements are CUDA 10.1 or newer, Python 3.6 or newer, torch 1.7.1 or newer, and cpm_kernels 1.0.9 or newer, with the claim that the installation process handles the dependencies. What the actual requirements file contains is thinner than that list: `torch` with no version at all, `cpm_kernels>=1.0.9`, and `typing_extensions`. So there is no ceiling on torch and no pin on typing_extensions, which means the resolver can hand you a torch far newer than the kernels were built against. If that combination breaks, the versions in the README's prose table are the constraint to check first, not the file.
The Dockerfile installs from a Tsinghua mirror and expects `examples` and `benchmark`
The container image starts from `nvidia/cuda:10.1-runtime`, installs python3 with pip and wheel plus `libgomp1`, puts setuptools in place, and then takes the version as a build argument:
ARG version
RUN pip3 install bminf==$version -i https://pypi.tuna.tsinghua.edu.cn/simple --no-cache-dir
The index is a Tsinghua mirror rather than PyPI, which is a deliberate choice for anyone inside that network and a reason the build may behave differently elsewhere. The image then copies an `examples` directory and a `benchmark` directory into itself, while the repository tree exposes `example/` with two subdirectories and no top-level benchmark folder. The README separately tells you to run `benchmark/cpm2/encoder.py`. Check those paths in your own checkout before you build the image or go looking for the benchmark scripts.
The newest tag is January 2023 and the news list stops in 2022
The version history and the documentation have both gone quiet. The three releases are 1.0.2 on 2022-01-25, 2.0.0 on 2022-07-31, and 2.0.1 on 2023-01-24, and the branch was last pushed on 2026-07-07. The What's New list ends at 2022/07/31, when 2.0.0 made the package applicable to any transformer-based model, and before that 1.0.0 dropped the `cupy` dependency and added PyTorch backpropagation. Documentation for the 1.x line sits in an `old_docs` directory. One 2021 note promised CPM-1/2 and EVA examples, and what arrived instead is `example/glm-130B/` and `example/huggingface/`, so the examples that exist are about a different model family from the one the benchmarks measure. The default branch is `master` rather than `main`, which is a small trap for anyone scripting a clone. If you cite the work, the ACL 2022 demonstration paper is the reference to use, and the README for 1.x is deliberately kept out of the main file rather than merged.
Editorial conclusion
BMInf is worth reading if you are stuck: the model is larger than the card, the framework does not fit, and buying hardware is not on the table this quarter. The wrapper contract is small enough to understand in a minute, the escape hatch to manual replacement is documented, and the benchmark scripts are in the repository so you can measure on your own GPU instead of trusting a table. It is a poor fit if you are on a current CUDA stack, since the documented floor is version 10.1 and the newest tag is from January 2023, or if you need pip to resolve your dependencies, since requirements.txt pins almost nothing.
Frequently asked questions
What hardware does BMInf need to run a large model?
The stated minimum is 16GB of memory, an NVIDIA GeForce GTX 1060 6GB, and PCI-E 3.0 x16, with 24GB and a Tesla V100 16GB recommended. GPUs with compute capability 6.1 or higher are supported, and CUDA 10.1 or newer is required.
How do I apply BMInf to my own model?
Build the model on CPU, load its state dict, then call bminf.wrapper inside a torch.cuda.device context with the device index. If the wrapper does not fit your architecture, replace torch.nn.ModuleList with bminf.TransformerBlockList and torch.nn.Linear with bminf.QuantizedLinear.
Is BMInf still being released?
The newest tag is 2.0.1 from 2023-01-24, after 2.0.0 in July 2022 and 1.0.2 in January 2022. The branch was last pushed on 2026-07-07 and the What's New list ends at the 2.0.0 entry, so the code has moved without a release.
What speed does BMInf report compared to PyTorch?
On the project's own CPM2 measurements, the BMInf decoder runs at 20 tokens per second on a Tesla V100 and 26 on an A100, against PyTorch rows of 3 and 7 on the same cards. The encoder column ranges from 718 to 4365 tokens per second and has no PyTorch baseline. Benchmark scripts are included so you can measure on your own GPU.
What license is BMInf released under?
Apache 2.0. The package also asks that you cite the ACL 2022 demonstration paper describing the toolkit, and points to a Chinese-language README alongside the English one.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openbmb-bminf)Star history chart for your README
[](https://hysenlabs.com/projects/openbmb-bminf)Was this useful?