VoxCPM2 skips the speech tokenizer entirely, and the language comes from your text, not a setting
VoxCPM2: Tokenizer-Free TTS for Multilingual Speech Generation, Creative Voice Design, and True-to-Life Cloning
At a glance
- What is it?
- VoxCPM2 is a 2B parameter, Apache-2.0 licensed text-to-speech model from OpenBMB that generates continuous speech representations directly instead of quantising audio into discrete tokens, with 30 languages, 48kHz output, and two distinct cloning modes. It is a credible open alternative for anyone who needs commercial-safe weights, and its rough edges are the Python version mismatch between its docs and its metadata and its alpha classification.
- Who is it for?
- VoxCPM2 is worth trying if you need a self-hosted multilingual voice model whose licence permits commercial use, if you want voice design from a text description rather than a recording, or if a 16kHz reference clip is all you have and you still want 48kHz output.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
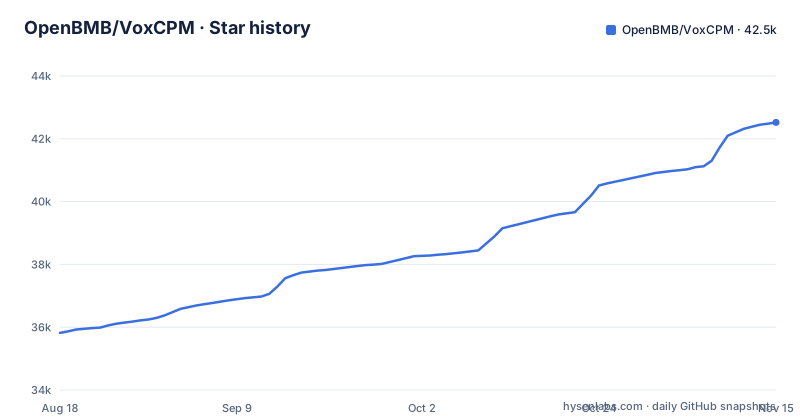
- OpenBMB/VoxCPM42,522 ★ · +6,705
| Repository | 2026-08-18 | 2026-11-15 |
|---|---|---|
| OpenBMB/VoxCPM | 35.8k | 42.5k |
6,705 Stars in the last 89 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
No discrete tokens sit between the text and the waveform
The architectural claim is the one to understand before anything else. VoxCPM is described as a tokenizer-free text-to-speech system that generates continuous speech representations directly through an end-to-end diffusion autoregressive architecture, bypassing discrete tokenization. The model itself is small enough to be approachable: VoxCPM2 is 2B parameters, trained on more than 2 million hours of multilingual speech, and built on a MiniCPM-4 backbone. The earlier line of releases is still available, with VoxCPM-0.5B and then VoxCPM1.5, the latter adding SFT and LoRA fine-tuning support.
Voice Design is a prefix inside the text, not a separate mode
Creating a voice with no reference audio is done by writing a description into the same string you are synthesising. The format is a parenthetical at the very start of the text argument, followed immediately by the words to speak, with no space or separator between the closing parenthesis and the sentence:
wav = model.generate(
    text="(A young woman, gentle and sweet voice)Hello, welcome to VoxCPM2!",
    cfg_value=2.0,
    inference_timesteps=10,
    seed=42,
)
sf.write("voice_design.wav", wav, model.tts_model.sample_rate)
The description can carry gender, age, tone, emotion, and pace. The practical consequence is that voice design is a prompt engineering surface rather than a parameter, so the same call produces a different voice when you change the words in the parentheses.
Ultimate Cloning needs the reference transcript, not just the audio
There are two cloning modes and they are not interchangeable, which is the detail most summaries flatten. Controllable cloning needs a short reference clip and nothing else, and it accepts optional style guidance so you can steer emotion, pace, and expression while keeping the original timbre. Ultimate cloning asks for more: both the reference audio and its transcript. With the transcript supplied, the model continues seamlessly from the reference and preserves the vocal detail, including timbre, rhythm, emotion, and style. The project notes this behaviour is the same as it was in VoxCPM1.5, so it is a carried-over capability rather than something new in version 2. The cost of the more faithful mode is preparation, since someone has to produce an accurate transcript of the reference clip before the call.
16kHz reference audio in, 48kHz output, super-resolution inside AudioVAE V2
The sample rate story is handled inside the model rather than by a separate tool. VoxCPM2 accepts 16kHz reference audio and outputs 48kHz, and it does this through the asymmetric encode and decode design of AudioVAE V2, with super-resolution built in, so no external upsampler is required. That is a practical difference when your source material is a phone recording or an old voice memo. The repository also ships concrete reference files, an example.wav, a reference_speaker.wav, and a train_data_example.jsonl for fine-tuning, so you can check the expected input shape without hunting for your own sample first. When writing results to disk, take the rate from the model rather than hardcoding it, using model.tts_model.sample_rate as the sample rate argument to soundfile.
The generate call exposes three knobs and a fixed text argument
The first example call is short. The model is loaded with VoxCPM.from_pretrained, pointing at the openbmb/VoxCPM2 repository and passing load_denoiser=False, and the example generate call passes a text string plus three numeric controls. cfg_value sets the guidance scale at 2.0 in the example, inference_timesteps sets the diffusion steps at 10, and seed fixes the random seed at 42 so a run can be reproduced. Loading is where the download choice is made, and there are two routes: the default from Hugging Face, or a ModelScope snapshot downloaded to a local directory first with snapshot_download and then passed as a local path. The package registers a console script named voxcpm pointing at voxcpm.cli:main, so the same functionality is reachable from a shell.
There is no language argument, so the language follows from the text
Multilingual support is presented as something you do not configure. The description of the capability is that you input text in any of the 30 supported languages and it synthesises directly, with no language tag needed, and the README example generate calls pass no language parameter. The covered languages are listed explicitly, from Arabic and Burmese through Chinese, Danish, Dutch, English, Finnish, French, German, Greek, Hebrew, Hindi, Indonesian, Italian, Japanese, Khmer, Korean, Lao, Malay, Norwegian, Polish, Portuguese, Russian, Spanish, Swahili, Swedish, Tagalog, Thai, Turkish, and Vietnamese. Chinese adds nine named dialects, including Sichuanese, Cantonese, Wu, and Northeastern. The consequence for a caller is that the language is inferred from the input rather than selected, so a short string, a name, or a line of code has nothing to disambiguate it.
Two streaming routes, and the faster one is a separate deployment
Latency is quoted two ways and the second is not part of the pip package. The baseline figure is a real-time factor as low as about 0.3 on an NVIDIA RTX 4090, which means roughly three seconds of audio generated per second of compute. The faster figure, about 0.13, requires a serving stack rather than a library call: it is reached by accelerating VoxCPM with Nano-vLLM, or with vLLM-Omni, which the project describes as official vLLM omni-modal serving for VoxCPM2 with PagedAttention and an OpenAI-compatible API. That distinction matters for planning. If your workload needs the 0.13 figure you are deploying an inference server, not importing a package, and the OpenAI-compatible surface is what makes existing client code work against it.
The README and the package metadata disagree about the Python ceiling
There is a small inconsistency worth catching before you install. The README states the requirement as Python 3.10 or higher and below 3.13, alongside PyTorch 2.5.0 or higher and CUDA 12.0 or higher. The package metadata is looser: requires-python is written as >=3.10 with no upper bound, and the classifiers only name 3.10 and 3.11. Nothing in the metadata stops a 3.13 interpreter from installing the wheel even though the documentation says it should not be used there. The package also carries an honest label, the Development Status classifier is 3, Alpha, which is a signal about support expectations rather than about quality. Other signs of a fast-moving project: gradio is pinned to a single major at >=6,<7, datasets to >=3,<4, and separate optional extras exist for dev tooling and for timestamps.
Editorial conclusion
VoxCPM2 is worth trying if you need a self-hosted multilingual voice model whose licence permits commercial use, if you want voice design from a text description rather than a recording, or if a 16kHz reference clip is all you have and you still want 48kHz output. It is a poor fit if you need to force a specific language on ambiguous text, because the README's examples show no language argument, or if you need a production support commitment, since the package is classified as alpha and the release notes are terse. Before you install, check the Python ceiling against your environment, since the README caps it below 3.13 while the package metadata does not, and decide which cloning mode you actually need, because ultimate cloning requires the reference transcript as well as the audio.
Frequently asked questions
what is voxcpm
VoxCPM is an open source text-to-speech system from OpenBMB that generates continuous speech representations directly, with no discrete tokenizer in the pipeline. VoxCPM2 is the current release, a 2B parameter model covering 30 languages with 48kHz output, published under the Apache-2.0 licence.
how to install voxcpm
Run `pip install voxcpm`. The stated requirements are Python 3.10 or higher and below 3.13, PyTorch 2.5.0 or higher, and CUDA 12.0 or higher. Weights come from Hugging Face by default, or from ModelScope if you download a snapshot to a local directory first.
is voxcpm free
Yes. The weights and code are released under the Apache-2.0 licence, which the project states makes it free for commercial use. The only cost is the compute you run it on.
how to use voxcpm
Load the model with VoxCPM.from_pretrained, call model.generate with text, cfg_value, inference_timesteps, and seed, then write the result with soundfile using model.tts_model.sample_rate as the rate. There is also a console script named voxcpm and a Gradio web demo, and voice design is done by putting a parenthetical description at the start of the text argument.
Is voice cloning illegal?
The README describes the technical side: it states that cloning works from a short reference clip for controllable cloning, and from reference audio plus its transcript for ultimate cloning, and that the weights and code are under Apache-2.0 for commercial use.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openbmb-voxcpm)Star history chart for your README
[](https://hysenlabs.com/projects/openbmb-voxcpm)Was this useful?