Eleven authorable edge types, one empty database password, and a benchmark score presented as efficiency
Long-term memory for AI assistants. Graph + vector store that recalls decisions, relationships, and context across sessions.
At a glance
- What is it?
- A dual-store memory service where the graph is the source of truth and the vector index degrades. The recall formula, the deletion cycle and the compose defaults are where the useful detail sits.
- Who is it for?
- AutoMem is for someone who has decided that an assistant should remember why a decision was made rather than just what was said, and who can run two databases. The typed relationship layer is the substance here.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
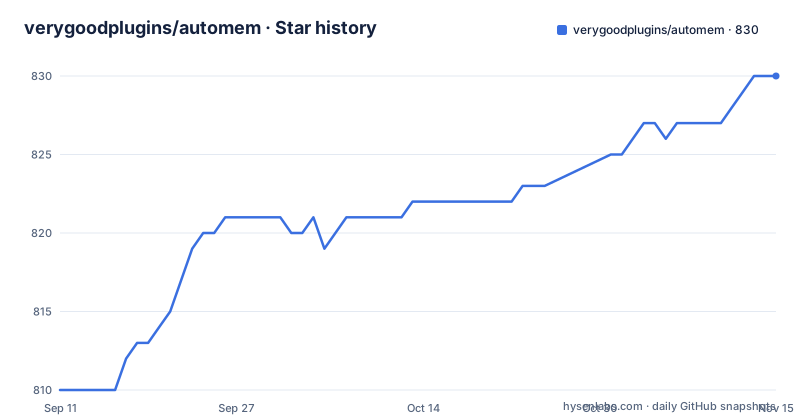
- verygoodplugins/automem830 ★ · +20
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| verygoodplugins/automem | 810 | 830 |
20 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Five recall signals are named and the ranking uses nine components
Recall is described as a hybrid query rather than a similarity search. The named factors are semantic similarity, graph traversal, temporal alignment, tag overlap and importance. Five factors.
The sentence then says the result is ranked by a nine-component score. Four components of the ranking formula are therefore not named on the front page, and the document that would carry the formula is `docs/COMPARISON.md`, which is also where the page sends anyone asking how AutoMem differs from plain retrieval-augmented generation and from a pure vector database.
That gap matters more than a documentation gap, because the score decides what your assistant sees. A weighted sum of five named factors and a weighted sum of nine are different systems, and the extra four could be anything from a recency bonus to a duplicate penalty.
The stated design constraint is that no language model call happens inside recall. The memory graph and the vector index are queried directly, which keeps retrieval fast and avoids paying for a generative call on every recall. Embeddings still come from Voyage, OpenAI or a local provider, and an optional enrichment pipeline can add structure over time.
Bridge discovery ranks the connecting memory above both memories that produced it
The multi-hop example is the clearest statement of what the graph is for. Ask why boring technology was chosen for Kafka, and the service starts from two seed memories: that the team migrated to PostgreSQL for operational simplicity, and that the team was evaluating Kafka against RabbitMQ for a message queue. Neither seed mentions the principle.
The bridge is a third memory, that the team prefers boring technology because it is proven and debuggable. Both seeds carry an `EXEMPLIFIES` edge to it, and the bridge is ranked above the seeds and surfaced in the response, so the assistant answers with the reasoning rather than two disconnected facts.
That behaviour is tuned from the request side, through `expand_relations`, `relation_limit` and `expansion_limit` on the `GET /recall` endpoint. Three parameters decide how far the graph walk goes, which is also the cost knob.
There are eleven authorable relationship types, from the general `RELATES_TO` through causal `LEADS_TO`, temporal `OCCURRED_BEFORE`, preference `PREFERS_OVER`, contradiction `CONTRADICTS`, invalidation `INVALIDATED_BY`, evolution `EVOLVED_INTO` and derivation `DERIVED_FROM`. Three more, `SIMILAR_TO`, `PRECEDED_BY` and `DISCOVERED`, are added automatically by the enrichment pipeline and the consolidation engine.
The graph is canonical, so the two stores fail in opposite ways
The failure behaviour is asymmetric and stated plainly. If Qdrant is unavailable, the graph still serves recall in a degraded mode. If FalkorDB is down, the API returns 503.
That is the correct ordering for a design that calls the graph the canonical record, and it has a practical consequence worth planning around: the vector store is the one you can afford to lose, and the graph is the one whose backup schedule matters. The compose file gives both services a bind-mounted backup directory, and the service diagram marks automated backups as an optional component inside the Flask service.
The architecture diagram also shows what writes where. The client calls the REST API for store, recall and associate; the API writes to both stores; the enrichment pipeline writes eleven edge types and pattern nodes to the graph, and semantic content to the vector store; and consolidation sits alongside as its own engine. The diagram itself breaks off mid-label on that last arrow, so the vector-side enrichment target is not fully drawn on the page.
Forget is off by default, and switching it on deletes
Consolidation runs on four cycles, modelled on biological memory consolidation.
| Cycle | Frequency | Purpose | | --- | --- | --- | | Decay | Daily | Exponential relevance scoring from age, access, connections and importance | | Creative | Weekly | REM-like processing that looks for non-obvious connections | | Cluster | Monthly | Groups similar memories and generates meta-patterns | | Forget | Off by default | Archives low-relevance memories and deletes very old ones |
The Forget row is the one to read twice. It is disabled by default, and when enabled it archives anything scoring below 0.2 and deletes anything below 0.05. Those are absolute numbers on the decay score, which itself is an exponential function of age, access count, connections and importance, so a memory's fate depends on all four.
Intervals are tunable through environment variables in the `CONSOLIDATION_*_INTERVAL_SECONDS` family, documented in `docs/ENVIRONMENT_VARIABLES.md`. A memory service that can delete is worth configuring deliberately rather than by copying a default environment file.
The other three cycles only add structure, which is why Forget is the one that needs a policy decision.
The graph database ships with an empty password on a published port
The local compose file is where the defaults are, and one of them is empty.
    environment:
      # Aggressive persistence: save every 60s if 1 key changed, enable AOF
      - REDIS_ARGS=${FALKORDB_REDIS_ARGS:---save 60 1 --appendonly yes --appendfsync everysec}
      - FALKORDB_DATA_PATH=/data
      - REDIS_PASSWORD=${FALKORDB_PASSWORD:-}
`REDIS_PASSWORD` falls back to an empty string, and the service publishes its port to the host. That default is fine for a laptop and wrong for anything else. The persistence settings next to it are aggressive by intent, saving every sixty seconds if a single key changed with append-only logging on and fsync every second.
A second port is published too, 3000 by default, described as the official local graph browser built into FalkorDB. That is a full graph visualisation UI reachable from outside the container.
There is also a documented upstream quirk in the comments: the `--dir` argument cannot be set through the extra arguments variable because FalkorDB's own start script appends its own directory flag afterwards and silently overrides it, so the data path is set through a separate variable instead.
The container image is tagged `latest`, so the version of the store that is the source of truth is not pinned anywhere in that file.
Qdrant is pinned and authenticated by nothing, the graph is unpinned
The two backing services are configured to different standards, and the contrast is worth noting before either is exposed.
Qdrant runs as `qdrant/qdrant:v1.11.3`, which matches the `qdrant-client==1.11.3` pin in the requirements, so the client and the server are deliberately aligned. FalkorDB runs as `latest`.
Neither service has an API key or token in the compose file. Qdrant publishes its HTTP port on 6333 and its gRPC port on 6334, both with a default host port, and carries a named volume plus a bind-mounted backup directory. It has no healthcheck, while FalkorDB does, with a ten-second interval and a password-aware `redis-cli` ping.
So the store that holds only the embeddings has a version pin and no health check, and the store that holds the canonical record has a health check, no version pin and an empty default password.
The application container is published on 8001 and reads an environment file whose comment explains an awkward detail: a compose-level `--env-file` only affects interpolation inside the compose file and never reaches the container environment, so a separate file is required for the search, recall and consolidation settings to arrive.
The image installs a pinned dependency list and then starts the Flask application directly
The runtime image is a Python 3.11 slim base with `build-essential` added, `requirements.txt` installed with no cache, and then the entire build context copied in. The final command is not a WSGI server:
EXPOSE 8001

CMD ["python", "app.py"]
There is no gunicorn, uvicorn or waitress in the requirements list, so this is the Flask application started as a script. That is the right thing for a local compose stack and the wrong thing behind a load balancer, and nothing in the image suggests the two cases are distinguished.
Two dependency pins are worth knowing about before an install fails on your machine:
onnxruntime<1.20  # Pin to avoid issues with fastembed 0.4.2
en-core-web-sm @ https://github.com/explosion/spacy-models/releases/download/en_core_web_sm-3.8.0/en_core_web_sm-3.8.0.tar.gz
The runtime version is capped below 1.20 with the reason given in the comment, and spaCy's English model is pulled straight from a GitHub release tarball rather than from a package index, so installation needs network access to that host and the model bypasses index-level pinning.
The embedding providers named on the front page are Voyage, OpenAI and a local one. The pinned list contains the OpenAI client and a local embedding library, and no Voyage client.
57.4 percent at ten million tokens is an efficiency result, not an accuracy one
The benchmark claim is stated in one sentence. On an independent agent memory benchmark's long-context tests, AutoMem scored 57.4 percent at ten million source tokens while giving the answerer an average of only about 2.6 to 4.8 thousand retrieved tokens.
The efficiency half is the interesting part. Retrieving on the order of three thousand tokens to answer a question drawn from ten million is a compression ratio in the thousands, and it is the reason the design argues against putting a language model inside the recall path.
The accuracy half deserves to be read as what it is. 57.4 percent is a modest score, and the page does not present a competing system's number on the same test, so the sentence establishes a retrieval budget rather than a lead. The word independent refers to the benchmark being run by someone other than the project.
The evidence trail is better than the headline. Test setup, raw outputs, methodology, historical runs and reproduction commands are said to be in the benchmark site and in `benchmarks/EXPERIMENT_LOG.md`, and the repository root carries shell harnesses for a live server, an auto mode, integration tests, and two named benchmark suites, LoCoMo and LongMemEval.
Editorial conclusion
AutoMem is for someone who has decided that an assistant should remember why a decision was made rather than just what was said, and who can run two databases. The typed relationship layer is the substance here. Eleven relationship types are yours to author, three more are added by the enrichment and consolidation engines, and the bridge discovery path is the part that actually changes an answer, because it ranks the memory connecting two memories above the two memories themselves. Use it if you run your own infrastructure and want an MCP bridge that works from Claude Desktop, Cursor, Claude Code, Codex and Copilot locally and from ChatGPT Developer Mode, Claude.ai and ElevenLabs remotely. Four things to check first. Decide whether the Recall cycle is right for you, because forgetting is off by default and switching it on archives below 0.2 and deletes below 0.05, so that is a data-retention decision rather than a tuning knob. Read the compose file before exposing anything, because the graph database's password defaults to empty while its port is published. Note that the container starts the Flask application directly with no WSGI server in front of it, so put a real server in front of it yourself if it is going anywhere near production. And treat the benchmark number in context: 57.4 percent at ten million source tokens is a retrieval-efficiency result with a modest accuracy figure attached, on someone else's long-context benchmark, with the reproduction material in an experiment log rather than in the page. What this is not is a drop-in chat memory button. It is two databases, a consolidation scheduler and a set of tunable recall knobs, and the tuning surface is documented in a separate variables reference rather than on the front page.
Frequently asked questions
Does AutoMem delete my memories automatically?
Not by default. The Forget consolidation cycle is off by default. When switched on it archives memories scoring below 0.2 and deletes those below 0.05, where the score comes from daily decay based on age, access, connections and importance. Cycle intervals are tuned through the CONSOLIDATION_*_INTERVAL_SECONDS environment variables.
What happens to AutoMem recall when the vector database is down?
The graph still serves recall in a degraded mode. The opposite case is hard failure: if FalkorDB is unavailable the API returns 503, because the graph is described as the canonical record and the embeddings are derived from it.
How many relationship types does AutoMem store between memories?
Eleven are authorable, including RELATES_TO, LEADS_TO, OCCURRED_BEFORE, PREFERS_OVER, EXEMPLIFIES, CONTRADICTS, REINFORCES, INVALIDATED_BY, EVOLVED_INTO, DERIVED_FROM and PART_OF. Three more, SIMILAR_TO, PRECEDED_BY and DISCOVERED, are added automatically by the enrichment pipeline and the consolidation engine.
Does AutoMem call a language model during recall?
No. Recall queries the graph and the vector index directly, which the project presents as keeping retrieval fast and avoiding a generative charge on every recall. Embeddings still come from Voyage, OpenAI or a local provider, and an optional enrichment pipeline can add structure over time.
What does the AutoMem benchmark number actually show?
On an independent long-context benchmark it scored 57.4 percent at ten million source tokens while retrieving only about 2.6 to 4.8 thousand tokens for the answerer. The result is a retrieval-efficiency figure with a modest accuracy score, and no competing system is given on the same test.
Does the AutoMem docker-compose file set a database password by default?
No. REDIS_PASSWORD falls back to an empty string through the FALKORDB_PASSWORD variable while the service port is published to the host, and FalkorDB's built-in graph browser is published on a second port. Qdrant has no authentication setting in the file at all, and its container is pinned to v1.11.3 while FalkorDB uses the latest tag.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/verygoodplugins-automem)Star history chart for your README
[](https://hysenlabs.com/projects/verygoodplugins-automem)Was this useful?