LiteLLM: A Rust-Core AI Gateway With a Python SDK and a Proxy That Speaks OpenAI
Self-hosted AI gateway with a Rust core and Python SDK that calls 100+ LLM providers in OpenAI format, adding cost tracking, guardrails, and load balancing.
At a glance
- What is it?
- LiteLLM is a self-hosted AI gateway that unifies 100+ LLM providers behind one OpenAI-compatible interface. Its Rust core and Python SDK make it a candidate for teams that want to swap providers without rewriting code, but the maintenance surface is large.
- Who is it for?
- Adopt LiteLLM if your team needs a single OpenAI-compatible interface across many providers and wants self-hosted control over keys, spend, and routing. The Python SDK is a low-friction way to start, and the proxy adds centralized governance for production.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
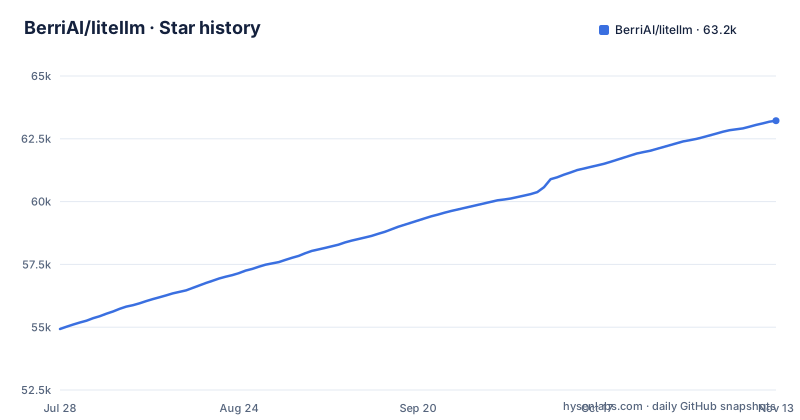
- BerriAI/litellm63,220 ★ · +8,293
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| BerriAI/litellm | 54.9k | 63.2k |
8,293 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What LiteLLM Actually Solves
LiteLLM attacks a specific pain: every LLM provider ships its own SDK, auth pattern, request schema, and error format. A team that wants to use OpenAI for one task and Anthropic for another ends up maintaining multiple client libraries and translation layers. LiteLLM collapses that into one interface. You call completion() with a model string like openai/gpt-4o or anthropic/claude-sonnet-4-20250514, and the library handles the provider-specific details. The project positions itself as an AI Gateway, which means it can run as a standalone proxy server, not just as a library. That proxy gives you virtual keys, spend tracking, guardrails, load balancing, and an admin dashboard. The target user is a developer or platform team that manages multiple LLM integrations and wants a single control point for access and cost.
The Rust Core and Python SDK Split
The repository description says Rust core with Python SDK, but the README leads with Python examples. The primary language listed is Python. That mix is worth understanding. The README claims 8ms P95 latency at 1k RPS, citing benchmarks in the docs. That number is a project claim, not something I verified. The Python SDK is the entry point for most users. You import litellm, set environment variables for API keys, and call completion(). The SDK is the thin layer; the proxy is the heavy service. For a small script, the SDK is enough. For a team, you deploy the proxy and point your OpenAI client at it. The proxy is reached through the OpenAI client with a base_url, as the README shows, whereas the SDK uses completion().
Getting It Running: SDK and Proxy Commands
The README gives two concrete paths. For the Python SDK, install with uv add litellm, then set API keys as environment variables. The example sets OPENAI_API_KEY and ANTHROPIC_API_KEY, then calls completion(model="openai/gpt-4o", messages=[...]). The model prefix tells LiteLLM which provider to route to. For the proxy, the README shows uv tool install 'litellm[proxy]' followed by litellm --model gpt-4o. That starts a server on port 4000. You then use a standard OpenAI client with base_url="http://0.0.0.0:4000" and any api_key string. The proxy accepts the OpenAI format, so existing OpenAI SDK code works unchanged. The README also points to a Getting Started E2E tutorial in the docs. The commands are straightforward, but the proxy is a separate service with more configuration surface than the SDK.
Beyond Chat: A2A Agents and MCP Tools
LiteLLM is not just chat completions. The README documents support for A2A agents. A2A is a protocol for agent-to-agent communication. LiteLLM provides an A2AClient in the Python SDK and lets you register agents in the proxy. The README lists LangGraph, Vertex AI Agent Engine, Azure AI Foundry, Bedrock AgentCore and Pydantic AI as supported A2A providers. This is a notable expansion beyond a simple gateway. It means LiteLLM is trying to be the connective tissue for the whole LLM ecosystem, not just a request router. That ambition adds complexity.
A Real Limitation: The Provider Prefix and Key Management
The core abstraction is the model string with a provider prefix. That works, but it puts a burden on the developer. You must know the exact provider name and model identifier for every model you use. A typo like openai/gpt-4 instead of openai/gpt-4o will fail or route to the wrong model. Also, the README's SDK example sets API keys as environment variables. That is fine for a local script, but in a production service, you do not want keys scattered in the environment. The proxy addresses that with virtual keys, but then you are running a separate service with its own auth and config. For a single-developer project with one provider, LiteLLM is overkill. The abstraction layer adds a prefix to every model call, and if you never switch providers, that prefix is pure overhead. The wrong tool is any project where the provider set is fixed and small.
The Alternative: Provider SDKs or a Hand-Rolled Adapter
The direct alternative is to use each provider's native SDK. OpenAI has its own Python client, Anthropic has its own, and so on. That approach gives you full access to provider-specific features like streaming options, tool schemas, or response formats that LiteLLM might abstract away. The cost is that you write and maintain your own translation layer. A lightweight alternative is to write a thin adapter class that maps a common request format to each provider's SDK. That gives you the same unification without the Rust core or the proxy server. The difference is in maintenance: LiteLLM tracks provider API changes for you, but you inherit its release cycle and its abstraction choices. A hand-rolled adapter is tailored to your exact needs but requires you to update it whenever a provider changes its API. For a team with one or two providers, the native SDKs are simpler and more transparent. For a team with ten providers, LiteLLM's unified interface starts to pay off.
Maintenance and Upgrade Cost
The release cadence is aggressive. The repository shows v1.109.0-dev.2 published on 2026-10-30, with v1.108.0-rc.1 a day earlier and v1.106.6 on 2026-10-28. That suggests weekly or more frequent releases. For a proxy that sits in your request path, that means constant review of changelogs and regression testing. The project is under active development, which is good for features but bad for stability if you cannot keep up. The default branch is litellm_internal_staging, not a stable name like main. That is a signal that the project's internal workflow is not conventional. You should pin your version and test upgrades in a staging environment before touching production. GitHub metadata lists the license as NOASSERTION, but pyproject.toml declares license = "MIT" with license-files pointing to LICENSE, so check the LICENSE file to confirm. The README mentions an Enterprise Tier and a Hosted Proxy, so there is a commercial layer.
Who Should Adopt It and What to Verify First
LiteLLM is a good fit for a platform team that manages LLM access for multiple internal teams and wants to track spend and manage virtual keys from one place. The proxy's virtual keys and admin dashboard are concrete features that address real governance problems. The Python SDK is a reasonable starting point for a prototype. Before committing, verify three things. First, confirm the license by reading the LICENSE file in the repository; GitHub metadata shows NOASSERTION while pyproject.toml declares MIT. Second, check the docs for the exact list of supported providers and confirm your models are there. The repository description names Bedrock, Azure, OpenAI, Anthropic, VertexAI, vLLM, and Nvidia NIM, but the full list is in the docs. Third, run your own load test against the proxy. The 8ms P95 claim is a benchmark, not a promise. If your traffic is low and your provider list is fixed, skip LiteLLM and use the native SDKs. If you need to support many providers and centralize control, this project is worth a trial, but treat the fast release cycle as a cost you must budget for.
Editorial conclusion
Adopt LiteLLM if your team needs a single OpenAI-compatible interface across many providers and wants self-hosted control over keys, spend, and routing. The Python SDK is a low-friction way to start, and the proxy adds centralized governance for production. Do not adopt it if you only use one provider and need minimal moving parts, or if you cannot commit to keeping pace with a project that pushes releases weekly. Before adopting, verify the license (GitHub metadata shows NOASSERTION, pyproject.toml declares MIT) and confirm the provider list covers the exact models you use. Also test the proxy's latency against your own workload; the 8ms P95 claim is a benchmark from the project, not a guarantee for your network. Start with the SDK, then add the proxy only when you need virtual keys or team-wide logging.
Frequently asked questions
Does LiteLLM cost money?
The proxy server is presented as an open source AI Gateway, but the project also offers a hosted proxy and an enterprise tier as separate products with their own pages.
What are the benefits of LiteLLM?
One interface in the OpenAI format across 100+ providers, so changing provider is a change to the model string rather than to your client code. Running it as the gateway adds virtual keys, spend tracking, guardrails, load balancing and an admin dashboard.
how to install litellm
As a library, uv add litellm. As the AI Gateway, uv tool install 'litellm[proxy]' followed by litellm --model gpt-4o to start the server, which then answers on port 4000.
how to use litellm proxy
Start it with the proxy extra installed, then point any OpenAI client at its base URL with a placeholder key such as api_key="anything". The proxy does its own authentication, which is where virtual keys come in.
Which companies are currently using LiteLLM?
The OSS adopters table in the README names Netflix.
Official sources
Where this project is recommended
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 5 in the last 30 days; newest first.
- Can't Beat Free: Gemma 4 31B on AMD Token Lab, with a Local Chat Page and an ADK Agentdev.to · Nov 13, 2026 · 20 points · 12 comments
- LiteLLM 1.107.0 Was Built From a Lookalike Fork: What PyPI Provenance Can and Cannot Tell Youdev.to · Oct 27, 2026 · 5 points · 0 comments
- How a Key Leaked in May Shipped Malware in Octoberdev.to · Oct 26, 2026 · 6 points · 0 comments
- Litellm 1.107.0 on PYPI CompromisedHacker News · Oct 21, 2026 · 3 points · 0 comments
- I put a logging proxy in front of an LLM client: here's what it emitteddev.to · Oct 19, 2026 · 11 points · 9 comments
- New LiteLLM Vulnerability: Privilege Escalation to Proxy Admin and RCEHacker News · Sep 30, 2026 · 1 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/berriai-litellm)Star history chart for your README
[](https://hysenlabs.com/projects/berriai-litellm)Community discussions
Was this useful?