DataFlex: a DeepSpeed cap justified by a README pin, and results measured on a benchmark subset
Data-centric LLM training with dynamic sample selection, domain mixture optimization, and example reweighting inside the LLaMA-Factory training loop.
At a glance
- What is it?
- A data-centric training framework that sits inside the LLaMA-Factory loop and reimplements sample selection, domain mixture and example reweighting, most of which have no official implementation anywhere. It installs as a package with five optional extras, but the one dependency cap in the metadata is justified by a version pinned in the README rather than by a tested matrix, and the headline results are measured against random sampling on the slice of a benchmark that matches the training domain.
- Who is it for?
- DataFlex earns its place if you are already training through LLaMA-Factory and want the selector to run inside the optimisation loop rather than as a separate offline pass, since that is the one thing none of the upstream repositories provide. Verify three things before you commit.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
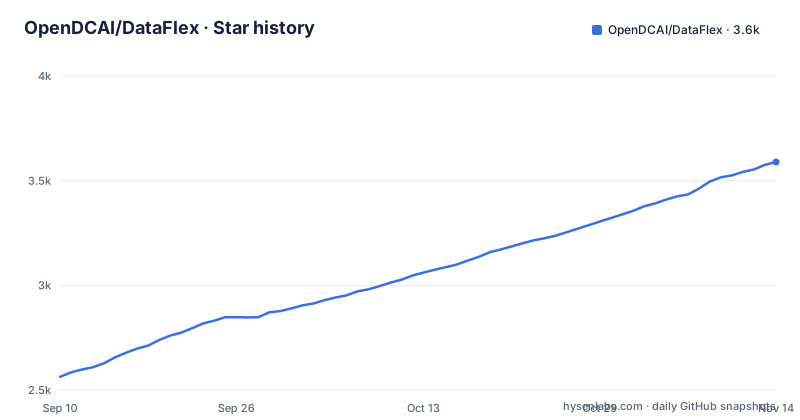
- OpenDCAI/DataFlex3,589 ★ · +1,026
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| OpenDCAI/DataFlex | 2.6k | 3.6k |
1,026 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The newest tag and the last push share a timestamp to the second
The version history is short enough to read exactly.
Release 1.0.0, titled Initial Release, was published 2026-04-16. Release 1.1.0, titled DataFlex v1.1.0, was published 2026-09-28 at 06:51:58 UTC. The last push to the main branch carries the same timestamp, 2026-09-28 at 06:51:58 UTC.
An identical timestamp to the second means the tag was cut from the branch tip rather than from a lagging commit, so there is no window in which the published artefact and the committed state diverged. That is worth noting because it is not universal, and because here it is verifiable rather than assumed.
The wider shape is a young project on a fast clock. The news section dates the announcement of the first Data-Centric Training System to 2025-12-23, so the first tag followed the announcement by about four months and the second came five and a half months after that. Two tags in nine months, with the second landing the same day as the NeurIPS acceptance was written up.
The classifier in the package metadata calls the project Beta at version 1.1.0, which is a fair description of a two-tag release history.
Most of what it reproduces has no official implementation
The overview states the value plainly: the system provides reproducible implementations of Data Selection, Data Mixture and Data Reweighting, and it integrates several difficult-to-reproduce repositories into a unified framework.
The three tables that follow are the honest part, because each carries a four-column judgement about whether a reference implementation exists. The legend defines three states: a cross for no official repository, a check for one that exists, and a warning for one that exists but contains issues.
Data Selection tabulates eight methods. Five have no official repository at all: Loss, Delta Loss, NEAR, Static and Random. One, TSDS, has a clean one. Two, LESS and NICE, have repositories marked as containing issues, though the page does not say what those issues are.
Data Mixture tabulates two, DOREMI and ODM, and both carry the warning marker.
Data Reweighting tabulates two, and both have no official repository.
Read together, the value of the project is highest exactly where the cross appears. Reweighting has no upstream reference in either of its methods, and four of the five unreferenced selection methods are the ones that need the model in the loop. That also explains why the fourth column matters more than it first appears: the marker is the project's own assessment of what it is standing in for.
One dependency cap is justified by a version pinned in the README
The install instructions pin torch to an exact version from a specific index:
pip install --index-url https://download.pytorch.org/whl/cu124 \
    torch==2.6.0 torchvision==0.21.0 torchaudio==2.6.0
python -c "import torch; print(torch.__version__, torch.cuda.is_available())"
The stated reason for doing torch first rather than letting the resolver handle it is that otherwise pip resolves a different build and then has to replace it. That is an acknowledgement of a real hazard rather than a stylistic preference, and the verification line afterwards is a sensible guard.
Now compare it with the metadata. The optional torch extra allows a wide window, from torch 2.4.0 up to and including 2.10.0, with torchvision up to 0.21.0 and torchaudio up to 2.6.0. So the README fixes one build while the package accepts thirty.
The consequence shows up in the DeepSpeed extra, which is held below 0.17. The comment in the package metadata gives the reason as that 0.17 and later cannot import on the torch 2.6 the README pins, and the README adds that on a newer torch you are free to lift the cap.
So a constraint in the machine-readable metadata derives from a version number in a prose document. Change the README pin and the package metadata becomes quietly wrong, with nothing to flag it. A tested compatibility matrix would be the sturdier place for that rule.
The Ascend path shows the same tension from the other side. The torch-npu extra pins torch to exactly 2.4.0, so a user on that hardware cannot move to a newer torch even though the general extra would allow it.
Five extras, and the dependency list is a file read at build time
The manifest declares its dependencies and version as dynamic, which means both are pulled in at build time rather than written inline. That is why a requirements file sits at the repository root carrying explanatory comments instead of a bare list.
Those comments are the useful part. One records that the transformers window matches the one LlamaFactory accepts and spans both major versions of that library. Another notes that the newer model families need a higher floor within that window while the rest works across the whole range, and that a specific minimum is recommended for training from scratch under ZeRO-3. A third explains that numpy is left uncapped because the current stack resolves to the 2.x series.
Five optional extras are declared. The README names two of them in prose: deepspeed, needed by every configuration under the DeepSpeed examples directory, and less, needed only by the LESS selector and described in the metadata as a heavy build. The torch and torch-npu extras are self-explanatory. The fifth, for metrics, pulls in text tooling including a Chinese segmenter, and its list is cut off in the visible text.
There is a single entry point, a console script named `dataflex-cli`, wired to a main function in the package's CLI module. A training run is then one command:
dataflex-cli train examples/train_lora/selectors/less.yamlSo the surface is small in one respect and wide in another: one command to start, but five extras and a thirty-version torch range behind it.
The paper is a benchmark and the repository is a training loop
The news section records an acceptance to the NeurIPS 2026 Evaluation and Dataset Track, and gives the paper's title as DataFlex: A Unified Benchmark and Evaluation Platform for Data-Centric Training of Large Language Models.
Every description of the software says something different. The repository description calls it data-centric training with dynamic sample selection, domain mixture optimisation and example reweighting inside the LLaMA-Factory training loop. The overview calls it a dynamic training framework that schedules data during optimisation. The package metadata calls it a data-centric training system.
None of those mention a benchmark or an evaluation platform. The title is about measuring, and the code is about training.
That is not necessarily a contradiction, since an evaluation track paper can ship a training system as its artefact. But it does mean someone arriving from the citation will not find what the title promises, and someone arriving from the repository will find a paper whose stated contribution is a different kind of thing.
The other headline is narrower than it looks. The technical report is said to have ranked first on a daily papers leaderboard for a single day, 2026-04-04. A one-day position on a daily board is a launch-week signal rather than a durable citation, and it is listed next to a genuine conference acceptance, which is not the same kind of claim.
Beta in the classifier, a student address in the author field
The package metadata is worth reading closely, because a few fields have drifted from the page's presentation.
The development status classifier says Beta. That is consistent with two tags in nine months and an announcement nine months old, and inconsistent only with the tone of the news section.
The supported Python versions are declared as an open-ended floor of 3.11 and above, while the classifiers enumerate only 3.11 and 3.12. So a 3.13 interpreter satisfies the constraint but is not advertised as tested.
The licence is written in the older table form rather than as an SPDX expression, which is the shape older tooling expects and newer tooling is moving away from.
The author field lists two people, and one of the contact addresses is a student one at a university domain rather than an organisational one. For a package whose news section leads with a conference acceptance, that is a small inconsistency between the project's public profile and its package metadata.
Even the keyword list has a slip in it. Four keywords are lower case and one is capitalised in the middle, so a search on the package index will match inconsistently depending on which form a user types.
None of these individually matters much. Together they are the signature of metadata maintained alongside a busy repository rather than generated from it.
The headline result is in-domain, against the weakest control
The results section makes one comparative claim and qualifies it carefully.
The claim is that the data selection algorithms and the data reweighting algorithm outperform the random selector baseline on the MMLU benchmark, and the qualifier is that this is the subset relevant to the training dataset.
That qualifier is doing real work. The training data is a subset of Open-Hermes-2.5, and the evaluation is the slice of MMLU that matches that training domain. So the comparison measures whether selecting better examples from a dataset improves performance on questions drawn from the same subject area. That is the right experiment for the claim being made, and it is not evidence about general capability.
The control is random sampling, which is the sensible floor and the weakest sensible ceiling. It establishes that the selectors beat picking arbitrarily. It does not establish that they beat a cheap heuristic such as deduplication or length filtering.
There is also a tension in the framing. The overview advertises full compatibility with LLaMA-Factory as a drop-in replacement, while the quick start says that unlike vanilla LLaMA-Factory your configuration file must also include DataFlex-specific parameters. Both cannot be literally true: an existing configuration does not pick up the new parameters by itself.
And there is no test directory at the top level. The examples tree carries a directory named for tests among its example configurations, which is a different thing.
Editorial conclusion
DataFlex earns its place if you are already training through LLaMA-Factory and want the selector to run inside the optimisation loop rather than as a separate offline pass, since that is the one thing none of the upstream repositories provide. Verify three things before you commit. Read the results as in-domain rather than general, because the reported gain is against random sampling on the benchmark slice matching your training data. Budget for the extras, since DeepSpeed and the LESS selector each need a separate install and one of them is a heavy build. And treat the version compatibility notes as a moving target, since the supported range is wide and the caps inside it are tied to documentation rather than to a tested matrix.
Frequently asked questions
What is DataFlex?
A dynamic training framework built on top of LLaMA-Factory that schedules training data during optimization, providing reproducible implementations of Data Selection, Data Mixture and Data Reweighting. It installs as the dataflex package and is driven through a dataflex-cli entry point.
What Python version and dependencies does DataFlex require?
Python 3.11 or newer and LlamaFactory 0.9.5 or newer, installed automatically with the other core dependencies. It works on transformers 4.55 through 5.6, the newer model families Qwen3.5 and Gemma 4 need transformers 5.5 or newer, and 5.3 or newer is recommended for train_from_scratch under DeepSpeed ZeRO-3.
How do I install DataFlex?
Install torch first from the pinned CUDA 12.4 index so pip does not resolve a different build, then run `pip install dataflex`, or clone the repository and run `pip install -e .`. The DeepSpeed example configs need `pip install "dataflex[deepspeed]"`, and the LESS selector needs `pip install dataflex[less]`.
Does DataFlex require DeepSpeed?
Only the configurations under examples/deepspeed, which ship as an optional extra. The extra is held below 0.17 deliberately because 0.17 and later fail to import on the torch version the README pins, and the page says the cap can be lifted on a newer torch.
Which data selection algorithms does DataFlex implement?
Eight are tabulated: LESS, NICE, Loss, Delta Loss, NEAR, TSDS, Static and Random. LESS and NICE have official repositories the page marks as containing issues, TSDS has one that is not marked, and the remaining five have no official repository at all.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/opendcai-dataflex)Star history chart for your README
[](https://hysenlabs.com/projects/opendcai-dataflex)Was this useful?