DataFlow: the package is open-dataflow and the command is dataflow
Easy Data Preparation with latest LLMs-based Operators and Pipelines.
At a glance
- What is it?
- OpenDCAI/DataFlow is a Python framework for turning noisy PDFs, text and QA into LLM training data, organised as operators assembled into pipelines. Its packaging has three different names, its Python floor is declared as 3.7 while its classifiers stop at 3.12, and its container image is locked to amd64 with a Chinese pip mirror baked in.
- Who is it for?
- Adopt DataFlow if you need reproducible pipelines for turning PDFs and raw text into fine-tuning data, and if you can live with a large dependency stack that includes torch, transformers and Google Cloud libraries. Do not adopt it if your platform is arm64 or your Python is outside 3.10 to 3.12, since the container is amd64-only and the metadata disagrees with itself.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
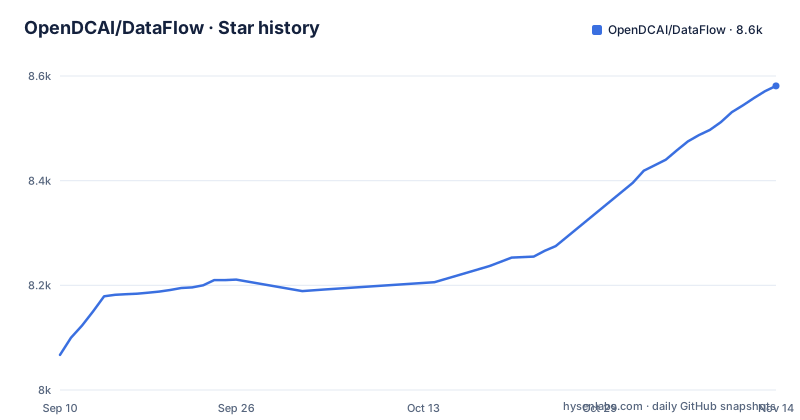
- OpenDCAI/DataFlow8,581 ★ · +514
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| OpenDCAI/DataFlow | 8.1k | 8.6k |
514 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three names: open-dataflow, dataflow, and the dataflow command
`pyproject.toml` names the distribution `open-dataflow` and describes it as a Modern Data Centric AI system for Large Language Models. The module it ships is `dataflow`, found by `include = ["dataflow*"]`, and the version is read out of the package itself with `version = {attr = "dataflow.version.__version__"}` rather than written in the file.
The console script is a third name: `[project.scripts]` maps `dataflow` to `dataflow.cli:app`. That is the command the README tells you to run to launch the visual pipeline builder, `dataflow webui`.
So installing and using this project means remembering which of the three names belongs where: `open-dataflow` is what a package manager resolves, `dataflow` is what you import and what appears in a traceback, and `dataflow` is the command. The README badges point at the PyPI project page for open-dataflow.
The Python floor says 3.7 and the classifiers stop at 3.12
The metadata does not agree with itself about interpreters. `requires-python = ">=3.7, <4"` is the declared floor, while the classifiers list only Python 3.10, 3.11 and 3.12, with the 3.7, 3.8 and 3.9 lines commented out in the same file.
The requirements file shows which of those two statements the code believes. `fasttext` is installed on `python_version >= "3.13"` and `fasttext-wheel` on `python_version < "3.13"`, each with a link to the pull request that split them, and `pyarrow==20.0.0` carries the comment that larger than this will bug on Python 3.10. So the dependency set changes with the interpreter, including one version above the newest classifier.
The practical consequence is that requires-python alone will not stop an install on 3.7 or 3.8. Treat the classifier list as the supported set and the floor as an artefact.
An Alpha classifier on a 1.0.11 release
The version has passed 1.0 and the maturity marker has not. `pyproject.toml` carries `Development Status :: 3 - Alpha`, and the licence block lists Apache-2.0 while also including a classifier of `License :: Free For Educational Use`, which describes a different set of terms.
The release record explains the pace. v1.0.10 shipped on 2026-03-26, v1.0.11 on 2026-09-28, six months after the one before it, and v1.0.13 on 2026-10-26, which is the current line.
What the marker means in practice is that the version number will not tell you whether an upgrade is safe. For a framework whose whole argument is reproducibility, that is the number to watch: the operators are meant to produce the same result twice, and a six-month gap with an Alpha label is where you check your own pipeline pins before moving.
The image is amd64-only and points pip at a Tsinghua mirror
The Dockerfile is short and makes three choices you inherit. The base image is pinned with an explicit platform:
FROM --platform=linux/amd64 nvidia/cuda:12.4.1-cudnn-runtime-ubuntu22.04The `--platform=linux/amd64` override means this image builds for x86 only, which rules out the arm64 machines that appear elsewhere in the ecosystem, including Apple silicon hosts and ARM servers.
Second, pip is pointed at a mirror inside the image, with an index URL of `https://pypi.tuna.tsinghua.edu.cn/simple`, a timeout of 120 and the host added to trusted-host. That is a deliberate choice for a fast install somewhere, and it is baked into every build of the image.
Third, the install is editable with a `vllm` extra:
RUN pip install -e ".[vllm]"The default command is `/bin/bash`, an interactive shell rather than a server.
Requirements.txt is a changelog with the removals commented out
The dependency list is organised by purpose, and several entries carry their own history. `numpy<2.0.0` is capped below 2. `matplotlib` appears as a comment with the reason: removed as no longer needed. Knowledge base cleaning has its own block with `chonkie`, `trafilatura`, `pymupdf` and `lxml_html_clean`; the dataflow agent block carries `cloudpickle`, `fastapi`, `uvicorn`, `httpx` and `sseclient-py`; speech brings `librosa` and `soundfile`; the Google Vertex AI block brings `google-cloud-aiplatform`, `google-genai`, `gcsfs` and `db-dtypes`.
Data quality libraries are there too, including `presidio_analyzer[transformers]` and `presidio_anonymizer` for named-entity work, `vendi-score==0.0.3` pinned exactly, `evaluate`, `simhash` and `symspellpy`.
The consequence is an install that pulls torch, torchvision, torchaudio, transformers, model APIs and Google Cloud clients whether or not your pipeline touches them. Reading requirements.txt before installing is worthwhile: it tells you which parts of the framework are optional in practice and which are unconditional.
Operators are the unit of reuse, not pipelines
The design claim is operator-based: DataFlow turns the whole data cleaning workflow into a reproducible, reusable and shareable pipeline, with more than 10 core operators defining interaction patterns and design principles and more than 100 pipeline-specific operators available for reuse or reference. Custom operators are plug-and-play and can be packaged and distributed through GitHub or PyPI.
The pipelines on top of those operators are named by task: large-scale PDF to QA conversion, book PDF to Visual-QA conversion, text, math and code data generation, Text2SQL workflow management accepted at ICDE 2026, and math data workflows accepted at KDD 2026.
Above them sits the DataFlow-agent, described as assembling new pipelines by recombining existing operators or creating new ones on demand. So there are two levels of reuse here: an operator you import, and a pipeline an agent assembembles from operators. The reproducibility claim rests on the first level, and the operator count is the honest measure of how much is already written.
The suite is four repositories, and the visual builder is not one of them
This repository is one of a set, and the split matters if you are evaluating it. The main repository holds the framework. DataFlow-Skills is a collection of skills and tutorials for working with it. DataFlow-WebUI is where the visual pipeline builder lives, and the entry point for using DataFlow through either the visual interface or MCP. DataFlow-Harness is the piece released in July 2026 that lets coding agents build DataFlow pipelines for you.
The news timeline in the README tracks the same expansion: officially released 2025-06-28, technical report on arXiv in December 2025, DataFlow WebUI in February 2026 with the `dataflow webui` command, DataFlow-Skills in May 2026, DataFlow-Harness in July 2026, and acceptance at ACM SIGMOD 2027 announced on 2026-09-12.
Documentation lives on the DataFlow-Doc site, tutorials are on Bilibili and a Feishu wiki, and a prebuilt image is published on Docker Hub as molyheci/dataflow.
Editorial conclusion
Adopt DataFlow if you need reproducible pipelines for turning PDFs and raw text into fine-tuning data, and if you can live with a large dependency stack that includes torch, transformers and Google Cloud libraries. Do not adopt it if your platform is arm64 or your Python is outside 3.10 to 3.12, since the container is amd64-only and the metadata disagrees with itself. Before starting, check which of the four repositories you actually need, because DataFlow-Harness download and installation entry points are in DataFlow-WebUI rather than this one.
Frequently asked questions
How do I install DataFlow?
The PyPI project is named open-dataflow, the Python package it installs is dataflow, and requires-python is declared as ">=3.7, <4" while the classifiers list 3.10 to 3.12. A container image is also published on Docker Hub as molyheci/dataflow.
How do I run the DataFlow visual pipeline builder?
The README says to launch it with the single command `dataflow webui`, which the pyproject console script maps to dataflow.cli:app. The WebUI code itself lives in the separate DataFlow-WebUI repository, and the DataFlow-Harness release adds MCP access to it.
What operators and pipelines does DataFlow provide?
More than 10 core operators define the interaction patterns and more than 100 pipeline-specific operators are available for reuse or reference, with custom operators supported as plug-and-play. Named pipelines cover large-scale PDF to QA, book PDF to Visual-QA, text, math and code data generation, Text2SQL and math workflows.
What licence is DataFlow released under?
pyproject.toml declares Apache-2.0 and the repository root has a LICENSE file. The classifier list in the same file also includes "License :: Free For Educational Use", which is a different set of terms, so read the LICENSE file rather than relying on the metadata.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/opendcai-dataflow)Star history chart for your README
[](https://hysenlabs.com/projects/opendcai-dataflow)Was this useful?