OpenRLHF: RLHF as a Ray and vLLM config surface, with pinned dependencies
An Easy-to-use, Scalable and High-performance Agentic RL Framework based on Ray (PPO & DAPO & REINFORCE++ & VLM & TIS & vLLM & Ray & Async RL)
At a glance
- What is it?
- OpenRLHF runs reinforcement learning from human feedback on a Ray plus vLLM distributed stack, with PPO, REINFORCE++, GRPO, RLOO and the newer FlashREINFORCE, which is selected by a config value. The sharpest practical detail is not the architecture, it is requirements.txt, where transformers, Ray, DeepSpeed and flash-attn are exact pins.
- Who is it for?
- Adopt OpenRLHF if your team already trains on Ray and vLLM and wants the whole RLHF pipeline in one repository, from SFT through reward modelling to PPO or REINFORCE++ runs. Skip it if you share a Python environment with anything else that needs a different transformers or Ray version, because the exact pins make that impossible without a separate environment.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 12 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
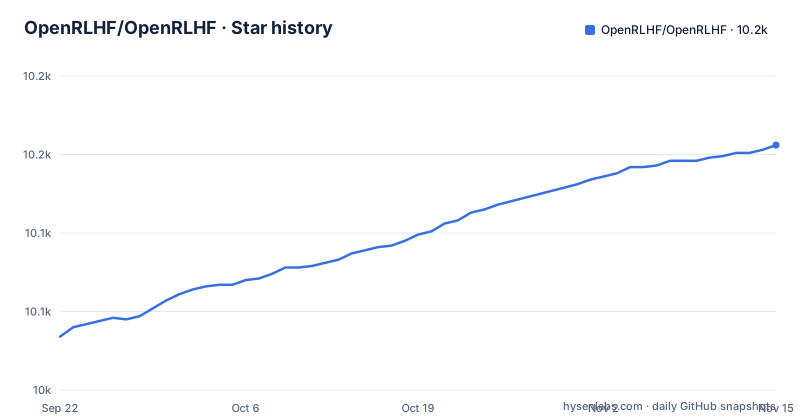
- OpenRLHF/OpenRLHF10,156 ★ · +122
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| OpenRLHF/OpenRLHF | 10k | 10.2k |
122 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Every algorithm is a value of --algo.advantage.estimator
OpenRLHF describes itself as the first RLHF framework built on a Ray plus vLLM distributed architecture with a unified agent based design. Ray acts as the distributed scheduler and controller, while vLLM serves generation. PPO, REINFORCE++, GRPO and RLOO are all listed as supported, and the newest addition, FlashREINFORCE, is described as a composition of configs, selected with `--algo.advantage.estimator flash_reinforce`, a binary-KL trust region on the vLLM logprobs, and sample-mean aggregation.
So the decision you make in week one is a flag value, not a fork. FlashREINFORCE is critic free and uses a single rollout per prompt, which means no critic model is trained and you give up the variance reduction a critic buys in exchange for throughput.
--train.async_enable and --train.agent_func_path are different switches
Two flags added in the 0.8 release are easy to read as one feature and are not. Async RLHF training comes on with `--train.async_enable`. Async agent RLHF comes on with `--train.agent_func_path`. The first changes how the training loop overlaps with generation; the second points at a Python file, which means the agent implementation lives in your repository rather than inside the framework.
The repository ships a runnable example for the async path, `examples/scripts/train_reinforce_baseline_ray_agent_async.sh`, and the Python side lives under `examples/python/`, where `vlm_multiturn_agent.py` shows multi-turn interaction with images in both the prompt and the environment feedback. Feature level training scripts follow the same naming pattern, including `train_vlm_math_hybrid_engine.sh` and `train_prorlv2_math_hybrid_engine.sh`.
Consequence for a reader wiring this up: agent work is ordinary Python on your side of the boundary, and the framework only holds the training loop and the distributed placement. A custom reward or a custom multi-turn environment is your file to maintain, not an upstream feature request.
version.txt picks the version, and OPENRLHF_BUILD_MODE renames the package
setup.py reads the version from a single file at the repository root and takes an environment variable to decide what kind of build you are making:
_build_mode = os.getenv("OPENRLHF_BUILD_MODE", "")


def _is_nightly():
    return _build_mode.lower() == "nightly"
When that variable reads nightly, the package is renamed to `openrlhf-nightly` and the version gains a date suffix built from the current day, so nightly builds from the same commit on different days carry different version strings. The distribution name changes; the import name does not. Installing a nightly next to a release leaves both distributions claiming the same `openrlhf` package directory, and which one wins depends on install order rather than on the name you asked for.
That is the practical reason to use one environment per experiment rather than flipping between the two mid run.
Linux wheels are tagged manylinux1_x86_64 whatever the build host
setup.py subclasses bdist_wheel and overrides two things. It forces `root_is_pure = False`, so the wheel is never treated as pure Python, and it builds the platform tag itself:
def get_tag(self):
    python_version = f"cp{sys.version_info.major}{sys.version_info.minor}"
    abi_tag = f"{python_version}"

    if platform.system() == "Linux":
        platform_tag = "manylinux1_x86_64"
    else:
        platform_tag = platform.system().lower()

    return python_version, abi_tag, platform_tag
Any Linux build, whatever distribution and glibc it came from, is labelled manylinux1_x86_64. That tag declares compatibility with the oldest manylinux baseline rather than measuring the system that produced it, so a wheel built on a recent image can claim a floor its binary dependencies never tested. Off Linux the tag collapses to the lowercased name of the operating system, which means a wheel built on macOS or Windows is not a manylinux artefact at all and will not install on a training cluster.
transformers, Ray, DeepSpeed and flash-attn are exact pins
requirements.txt is short and unforgiving. Four lines decide whether your environment can be built at all:
deepspeed==0.19.6
flash-attn==2.8.3
ray[default]==2.55.0
transformers==5.15.0
Four more carry lower bounds rather than pins: grpcio at 1.74.0, huggingface_hub at 1.0.0, optree at 0.15.0 and pynvml at 12.0.0. wheel, torch, accelerate, datasets, peft, loralib, optimum, tensorboard, torchmetrics and wandb are listed without a version.
The consequence is environmental, not editorial. An operator cannot share one virtual environment between OpenRLHF and another project that needs a different transformers or Ray build, because any resolver that tries to satisfy both has to pick, and these four lines do not move. Teams working this way keep a dedicated environment per training stack.
The same file also shows where the framework sits in the stack: DeepSpeed for the training engine, Ray for scheduling, transformers and peft and loralib for models, wandb and tensorboard for tracking.
pytest collects ./tests and never opens examples/
The test configuration in pyproject.toml is narrow and strict:
addopts = "--verbose --pyargs --durations=0 --strict-markers" # always add these arguments to pytest`--strict-markers` means any marker you use has to be declared, and the declared list is short: unit, integration, system and acceptance, each with a description of what it selects. `testpaths` is pinned to `./tests` so a stray tests module elsewhere on the path cannot be imported by accident, and `norecursedirs` excludes external, examples, docs, scripts, tools and tutorials from collection.
Read together, those settings define what a green test run does not cover. Nothing under `examples/` is collected, so a training script or an agent file that stops importing is not caught by the suite. Formatting is enforced separately through black and ruff, both set to a line length of 119, with isort configured to the black profile and python 3.10 as the target version.
Where OpenRLHF stops and its forks begin
Two forks are named with their purpose. MARTI was released as a fork of OpenRLHF to train LLM based multi agent systems with RL, combining centralised multi agent interaction with distributed policy training. LMM-R1 is a fork aimed at high performance RL infrastructure for reproducing DeepSeek-R1 on multimodal tasks.
The README also recommends Molt, from the NVIDIA NeMo labs, as a lightweight, PyTorch and Hugging Face native RL framework powered by NVIDIA AutoModel, with fully asynchronous training, multimodal and multi-turn agents, and large-scale MoE support.
Two limits are worth stating plainly. First, the repository is a training framework with shell scripts under `examples/scripts/` and agent code under `examples/python/`.. Second, the licensing is Apache-2.0 with the text in LICENSE at the root, which is the permissive end of the scale, so a fork and a commercial deployment are a much lighter conversation here than they would be under a copyleft licence.
Editorial conclusion
Adopt OpenRLHF if your team already trains on Ray and vLLM and wants the whole RLHF pipeline in one repository, from SFT through reward modelling to PPO or REINFORCE++ runs. Skip it if you share a Python environment with anything else that needs a different transformers or Ray version, because the exact pins make that impossible without a separate environment. Before installing, read requirements.txt and check the four pinned lines against your cluster, then confirm your accelerator topology matches the Ray and vLLM placement the README describes.
Frequently asked questions
How does OpenRLHF compare with TRL?
What the README states about OpenRLHF itself is a Ray plus vLLM distributed architecture with a unified agent based execution pipeline, and support for PPO, REINFORCE++, GRPO and RLOO.
What do I need to install to run OpenRLHF?
The README links the documentation at openrlhf.readthedocs.io and has a Quick Start section for installation, and requirements.txt holds the dependency list. It pins transformers at 5.15.0, ray[default] at 2.55.0, deepspeed at 0.19.6 and flash-attn at 2.8.3.
How do I pick a different RL algorithm in OpenRLHF?
The advantage estimator is a config value. FlashREINFORCE is selected with `--algo.advantage.estimator flash_reinforce`, and the README lists PPO, REINFORCE++, GRPO and RLOO among the supported algorithms.
What is the difference between --train.async_enable and --train.agent_func_path in OpenRLHF?
Async RLHF training comes on with `--train.async_enable`, and async agent RLHF comes on with `--train.agent_func_path`, which points at your own Python file. A runnable example sits at examples/scripts/train_reinforce_baseline_ray_agent_async.sh.
Where are OpenRLHF training scripts kept?
Shell training scripts live under examples/scripts/ and agent implementations under examples/python/, including vlm_multiturn_agent.py for multi-turn image interaction. Feature specific scripts include train_vlm_math_hybrid_engine.sh.
What licence is OpenRLHF released under?
Apache-2.0, with the licence text in the LICENSE file at the repository root.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openrlhf-openrlhf)Star history chart for your README
[](https://hysenlabs.com/projects/openrlhf-openrlhf)Was this useful?