SenseNova-U1: picking a checkpoint from the MoT, Infographic and 8-step lines
SenseNova-U series: Native Unified Paradigm with NEO-unify from the First Principles
At a glance
- What is it?
- SenseNova-U1 is a family of MoT image models from OpenSenseNova, published as Hugging Face checkpoints rather than GitHub releases, with GGUF quantization and layer offload for single-GPU use. The naming carries the generation, the task and the step count, and the training pipeline for the 1.5 generation is announced but not yet in the repository.
- Who is it for?
- Adopt SenseNova-U1 if you generate or edit images on a single Linux GPU and you want the 1.5 generation's native 4K and editing work without standing up a multi-GPU cluster. Do not adopt it yet if you need the full 1.5 training recipe, since SFT, RL and MOPD are announced for open-source release and the code in `training/` covers the earlier 1.0 generation.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
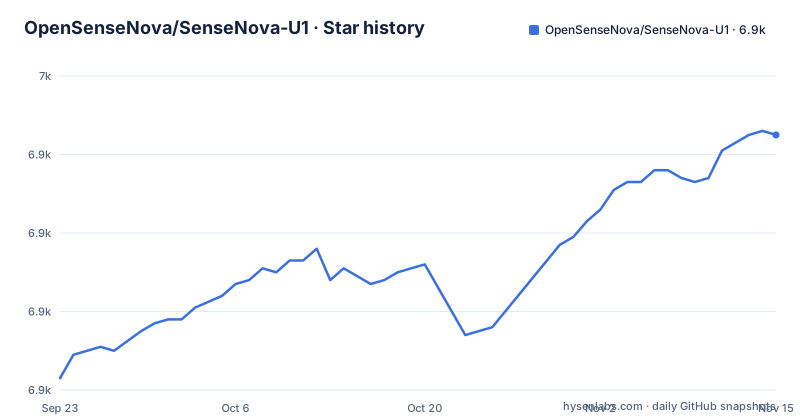
- OpenSenseNova/SenseNova-U16,945 ★ · +62
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| OpenSenseNova/SenseNova-U1 | 6.9k | 6.9k |
62 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The checkpoint name tells you the generation, task and step count
Almost everything you need to know about a SenseNova-U1 model sits in its filename. `SenseNova-U1-A3B-MoT` and `SenseNova-U1-8B-MoT` are the original MoT generation, and the A3B suffix marks a different size class from the 8B one. Task variants append their own word: `SenseNova-U1-8B-MoT-Infographic` for infographic generation and editing, `SenseNova-U1-8B-MoT-Interleaved` for image-text sequences that need narrative coherence across pages, and the `-Preview` suffix marks an intermediate checkpoint such as `SenseNova-U1.5-8B-MoT-Preview` from 2026-07-31.
The 1.5 generation arrived in pairs on 2026-08-20: the base `SenseNova-U1.5-8B-MoT` checkpoint and a `SenseNova-U1.5-8B-MoT-LoRA-8step` adapter for faster inference. The second entry in that pair is why the names are hard to parse at first. A base checkpoint runs the full denoising schedule; the LoRA variant compresses it to eight steps. They are two files for the same model, not two models.
No GitHub releases, so the weights live on Hugging Face
The repository has no GitHub releases at all. Everything a user downloads sits on Hugging Face and ModelScope instead, and the README links the collections directly: one for the U1 line, one for U1.5. A ModelScope mirror exists for `SenseNova/SenseNova-U1.5-8B-MoT`. The last push to the repository was on 2026-10-30, which is recent, but that date tracks code and documentation. It tells you nothing about when a checkpoint was uploaded, because the uploads happen elsewhere.
Code and weights therefore move on separate schedules, and the mismatch has practical consequences. The training code in the repository covers the earlier generation, while the announcement for the 1.5 checkpoints said the technical report and the full training pipeline, from SFT and RL to MOPD, were being prepared for open-source release; the SenseNova-U1.5 Technical Report was then released on 2026-09-11. So the newest weights exist before the recipe that produced them. Anyone planning to fine-tune 1.5 is planning to write part of the pipeline themselves.
GGUF and layer offload are the single-GPU path
The 2026-05-08 entry added GGUF quantized checkpoints and layer-offload VRAM modes for low-VRAM single-GPU inference, and the project credits smthemex for contributing the quantized weights for `SenseNova-U1-8B-MoT-Merger`. Two quantized files for the 1.5 line came from community contributors: a Q8 GGUF for `SenseNova-U1.5-8B-MoT-Preview` at 19.9 GB on 2026-08-04, and another for `SenseNova-U1.5-8B-MoT` at 21.2 GB on 2026-09-01.
Read those sizes as the real constraint. Layer offload keeps weights in host memory and moves layers to the GPU as they are needed, trading speed for capacity. The README has a separate Memory-efficient inference section on the GGUF and VRAM modes.
Infographic and Interleaved are separate models, not modes
Two task lines branch off the main generation, and treating them as settings rather than checkpoints is the easy mistake. The Infographic series has its own release history: a V1 model on 2026-05-15, a `-LoRA-8step-V1.0` adapter on 2026-06-12, `SenseNova-U1-8B-MoT-Infographic-V2` on 2026-06-29, and `SenseNova-U1-8B-MoT-Infographic-V3` on 2026-07-16. V2 sharpened dense small-text edges and fixed a black-background problem; V3 added localized text and content editing, global style editing and global layout editing.
Interleaved is a single checkpoint, `SenseNova-U1-8B-MoT-Interleaved` from 2026-06-11, aimed at multi-page image-text output where characters and styles have to stay consistent from page to page. A ComfyUI workflow ships alongside the Infographic V3 model at `apps/comfyui/example_workflows/infographic_series_t2i_edit.json`, so the tool has an ecosystem presence rather than a Python API only.
An eight-step LoRA trades detail for speed, and the V2 release says how
The LoRA line has been revised once and the revision note is unusually specific. `SenseNova-U1.5-8B-MoT-LoRA-8step-V2`, released 2026-09-24, is described against its predecessor as better color balance, more natural contrast and reduced oversharpening. Those are the kinds of changes a user would notice in skin tones and skies, and they are the kind of claim that comes from looking at outputs rather than from a single metric.
The same shape applies to the 1.0 line: `SenseNova-U1-8B-MoT-LoRA-8step-V1.0` on 2026-05-06, and an infographic-specific 8-step adapter on 2026-06-12. Example scripts are under `docs/base_vs_distill.md`, including a section for the 1.5 generation and one for running base and distilled models side by side. That is the honest starting point for anyone deciding.
requirements.txt pins torch 2.8.0 to a CUDA 12.8 wheel index
The Python package is a thin shell around the weights, and its dependency list is where the real constraints live. `pyproject.toml` names the package `sensenova-u1` at version 0.1.0 and requires Python from 3.10 up to but not including 3.14. What it does not do is float the ML stack. `torch==2.8.0` and `torchvision==0.23.0` are pinned exactly, as are `pillow==12.0.0`, `tqdm==4.67.1`, `packaging==25.0` and `sentencepiece==0.2.1`. Transformers and its companions take bounded ranges instead, `transformers>=4.57.1,<6` among them, so the package can sit next to other ComfyUI nodes in one environment.
`requirements.txt` is generated from that file by `scripts/render_requirements.py` and is what most people should install:
--extra-index-url https://download.pytorch.org/whl/cu128

torch==2.8.0
torchvision==0.23.0
transformers>=4.57.1,<6
accelerate>=1.1,<2
The extra index URL is the line to read twice. It points at the CUDA 12.8 wheels, so on an older driver or an AMD card this is where an install will stop working. `uv.lock` is described in the project comments as the exact, tested environment, and the classifiers list Linux as the only supported operating system.
What is promised and not yet in the repository
The gap that matters most is reproducibility of the 1.5 generation. The 2026-08-20 announcement says the technical report and the full training pipeline, from SFT and RL to MOPD, are being prepared for open-source release. What exists in `training/` today is the full-parameter fine-tuning code released on 2026-05-21 for the earlier U1. The two technical reports are already published as PDFs under `docs/pdf/`, `SenseNOVA_U1.pdf` and `SenseNOVA_U1_5.pdf`, so the architecture write-ups are available even though the 1.5 recipe is not.
Two smaller gaps shape day-to-day use. Serving examples live in `examples/serving/`, and the code you run is the Python package plus a downloaded checkpoint.
One more expectation to set. The README's opening line calls the series a paradigm, and a Discord invite and a link to unify.light-ai.top sit in the header. None of that is documentation. The parts worth trusting are the per-model notes under `docs/`, the example scripts in `examples/`, and the pin file.
Editorial conclusion
Adopt SenseNova-U1 if you generate or edit images on a single Linux GPU and you want the 1.5 generation's native 4K and editing work without standing up a multi-GPU cluster. Do not adopt it yet if you need the full 1.5 training recipe, since SFT, RL and MOPD are announced for open-source release and the code in `training/` covers the earlier 1.0 generation. Verify three things first: which checkpoint name matches your task, whether the Q8 GGUF file the community maintains is the one you can fit on your card, and whether the pinned torch 2.8.0 and cu128 wheel index in requirements.txt match your CUDA stack.
Frequently asked questions
How do I run SenseNova-U1 on a single GPU with limited VRAM?
The project added GGUF quantized checkpoints and layer-offload VRAM modes for low-VRAM single-GPU inference on 2026-05-08. Community Q8 GGUF files exist for the U1.5 models, one at 19.9 GB for the preview checkpoint and one at 21.2 GB for the base checkpoint.
What is the difference between the SenseNova-U1 base checkpoint and the 8-step LoRA?
They are two files for the same model. The base checkpoint runs the full denoising schedule, and the LoRA-8step adapter compresses it to eight steps for faster inference. Example scripts for comparing them are under docs/base_vs_distill.md.
Is the SenseNova-U1 training code available?
Full-parameter fine-tuning code for the U1 generation was released on 2026-05-21. For the 1.5 generation the technical report was released on 2026-09-11, and the full training pipeline, from SFT and RL to MOPD, was announced as being prepared for open-source release.
What Python and PyTorch versions does SenseNova-U1 need?
pyproject.toml requires Python from 3.10 up to but not including 3.14, and pins torch to 2.8.0 and torchvision to 0.23.0. requirements.txt adds the CUDA 12.8 wheel index, and the project classifiers list Linux as the only supported operating system.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/opensensenova-sensenova-u1)Star history chart for your README
[](https://hysenlabs.com/projects/opensensenova-sensenova-u1)Was this useful?