NNCF's usage snippets all stop mid-statement, and its PyTorch floor has no classifier
Neural Network Compression Framework for enhanced OpenVINO™ inference
At a glance
- What is it?
- openvinotoolkit/nncf post-training compression covers four backends while training-time compression covers one, every usage snippet in the README stops partway through a statement, OpenVINO is the preferred quantization backend and is not a dependency, and openvino-telemetry is a hard runtime requirement of a compression library.
- Who is it for?
- NNCF fits a team that already has a working PyTorch or OpenVINO model, knows its accuracy target, and wants 8-bit quantization plus pruning rather than an open search over compression recipes. Four things to check first.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
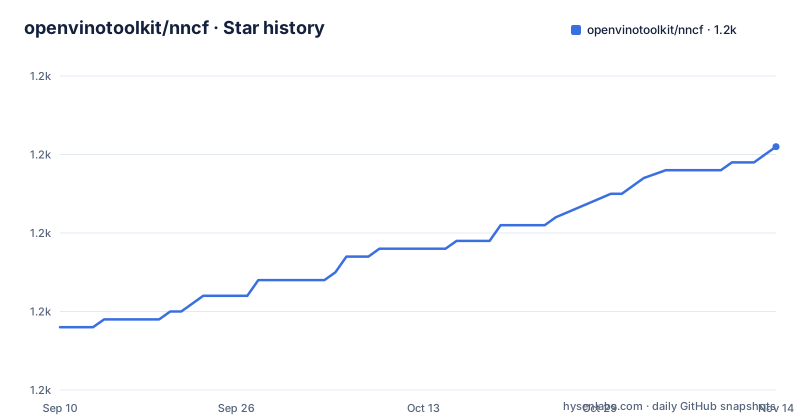
- openvinotoolkit/nncf1,221 ★ · +23
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| openvinotoolkit/nncf | 1.2k | 1.2k |
23 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Post-training covers four backends, training-time covers one
The two feature tables in the README have different shapes, and the difference is the whole scope of the project in one glance.
The post-training table has four columns: OpenVINO, PyTorch, TorchFX, and ONNX. Post-Training Quantization is supported on three of them and experimental on TorchFX. Weights Compression is the same pattern. Activation Sparsity is the outlier: not supported on OpenVINO, experimental on PyTorch, not supported on TorchFX, not supported on ONNX.
The training-time table has one column. Quantization Aware Training, Weight-Only Quantization Aware Training with LoRA and NLS, and Pruning are all supported on PyTorch, and there is no OpenVINO column and no ONNX column at all.
So the compression that happens after training travels between four frameworks, and the compression that happens during training is PyTorch only. That asymmetry is not hidden anywhere else in the README, and it decides your architecture: if you need quantization aware training, you are training in PyTorch and exporting afterwards, and the export path is listed as producing ONNX checkpoints or SavedModel and Frozen Graph formats ready for the OpenVINO toolkit.
Activation sparsity is one experimental path, documented inside src/nncf/experimental
Activation Sparsity is the one algorithm whose own documentation lives inside the experimental source tree. The link in the feature table points to a path under src/nncf/experimental/torch/sparsify_activations/ rather than to docs/usage like the other four rows.
That is a structural signal rather than a cosmetic one. Every other algorithm's documentation is under docs/usage/, split into post_training_compression and training_time_compression. This one is documented where the experimental code is, which tells you it is maintained as an experiment rather than as a documented feature.
The support matrix agrees. It is the only algorithm marked not supported on three of four backends, and the one place it is marked experimental is PyTorch, which is also the only backend with a training-time table.
So the honest summary of activation sparsity is that it exists as a PyTorch experiment, with no OpenVINO or ONNX path, and its user-facing documentation lives in the same namespace the type checker is configured to skip.
All four usage snippets stop partway through a statement
The post-training quantization section has four collapsible snippets, one per backend. Each one stops before it finishes.
The OpenVINO one ends on the comment Step 2: Initialize NN. It is otherwise complete through the model read, the ImageFolder validation set, a DataLoader with batch_size=1, and a transform_fn that returns the images. That is the longest of the four:
import nncf
import openvino as ov
import torch
from torchvision import datasets, transforms

# Instantiate your uncompressed model
model = ov.Core().read_model("/model_path")

# Provide validation part of the dataset to collect statistics needed for the compression algorithm
val_dataset = datasets.ImageFolder("/path", transform=transforms.Compose([transforms.ToTensor()]))
dataset_loader = torch.utils.data.DataLoader(val_dataset, batch_size=1)

# Step 1: Initialize transformation function
def transform_fn(data_item):
    images, _ = data_item
    return images

# Step 2: Initialize NN
The PyTorch and TorchFX snippets are the same code apart from the extra torch.fx import, and both end inside the nncf.Dataset call. The PyTorch one reaches nncf.Dataset(data and the TorchFX one stops one character earlier at nncf.Dataset(d. The ONNX snippet ends inside the model load.
The gap between those two is a good illustration of what a copy-then-truncate leaves behind: the two files had the same length to begin with, and one got one character further before it stopped.
One difference between the OpenVINO snippet and the others is real rather than accidental. The OpenVINO one sets batch_size=1 on the DataLoader; the PyTorch and TorchFX ones pass no batch size.
OpenVINO is the preferred backend and is not in the dependency list
The README states that OpenVINO is the preferred backend to run post-training quantization with, while PyTorch and ONNX are also supported. The framework exists to optimize inference in OpenVINO, and the whole point of compressing a model is the speed of the runtime you deploy it to.
Now look at what pip installs. The runtime dependencies are networkx, ninja, numpy, openvino-telemetry, packaging, psutil, pydot, rich, safetensors, scikit-learn, scipy, and tabulate. There is no openvino package among them.
So the preferred backend has to be installed separately, and nothing in the dependency metadata says so. For a library whose purpose is to serve one runtime, that is a deliberate choice to stay backend-neutral at install time, and it is also a first-run failure for anyone who follows the README's preferred path and then hits an import error rather than a documentation pointer.
The same pattern shows up in the Makefile, where the install targets for each backend run pip install -e . and then add the backend-specific test requirements separately.
A calibration set of roughly 300 samples is the other number worth holding on to, because it is what the README calls the small dataset the algorithm needs.
openvino-telemetry is a hard runtime dependency of a compression library
The dependency list includes openvino-telemetry at 2023.2.0 or newer. It is not in an extras group. Anyone who installs NNCF installs the telemetry package.
For a library that runs on someone's inference box and touches their models, that is worth a conscious decision rather than an inherited one. It is also not hidden: the package is named plainly in pyproject.toml, so a reader can see it before installing.
Three other entries in that list deserve a look. ninja is a build tool sitting in runtime dependencies. Several dependencies carry upper bounds as well as floors, with networkx capped at 3.6.1, numpy below 2.5.0, pydot at or below 4.0.1, and ninja below 1.14, which means an install can be blocked by a cap rather than by a floor. And psutil is unpinned while its neighbours are bounded.
The contrast with the optional group is sharp. The plots extra is a tidy set of floors for kaleido, matplotlib, pillow, and plotly-express with a single pandas cap below 2.4, and none of it installs unless you ask for it.
So the runtime surface is wide and bounded, the optional surface is small, and telemetry is on the wrong side of that line if your policy says libraries should not ship it.
Python 3.10 is the floor, and the classifier list does not say so
The project metadata is precise in most places. The name is nncf, the license is Apache-2.0, the authors are Intel with a named contact address, and requires-python is 3.10 or newer.
The classifier list then says only Operating System :: OS Independent and Programming Language :: Python :: 3.
One generic Python 3 classifier, no per-minor-version entries. A package that requires 3.10 or newer and declares no 3.10, 3.11, 3.12, or 3.13 classifier is telling a package index very little about what it has been tested on, and it means the metadata cannot be used to filter by interpreter version.
Two more details in the same file. The version is dynamic, resolved from a custom_version.version attribute rather than written in pyproject.toml, so the number you install is read out of a Python file at build time. And the readme field points at docs/PyPiPublishing.md, so the long description on the package index is the project's own guide to publishing to PyPI rather than the README.
None of that is wrong. It is a set of choices that trade convenience in the index for control over the build, and the classifier line is the one that costs something without buying anything.
mypy runs strict on src and excludes the experimental tree
The type checker configuration is short enough to read in full. follow_imports is set to silent, strict is on, and files points at src.
The exclude list is where the information is. It begins with the whole experimental namespace, src/nncf/experimental/*, and then names three specific ONNX modules: the metatypes file, the graph model transformer, and the graph model utilities.
So the algorithm whose documentation lives inside src/nncf/experimental is also outside the strict typing boundary, and three ONNX graph modules are outside it by name. That is a reasonable trade for experimental and generated-adjacent code, and it is the same boundary the support matrix draws: experimental is where the guarantees stop.
A smaller configuration sits alongside it. The dead link checker excludes ReleaseNotes.md, which is the file most likely to reference versions or paths that have since moved.
Two other files at the repository root say something about how the project is run. AI_POLICY.md sits next to CODE_OF_CONDUCT.md, CONTRIBUTING.md, and Security.md, and CODEOWNERS is present, so there is a named set of people responsible per path.
The default branch is develop rather than main, with releases cut from it, which is the branch to look at if you want what is next rather than what shipped.
Install targets are duplicated per backend, and accuracy_checker is pinned twice
The Makefile organises itself by backend, with an ONNX block and an OpenVINO block and more below that are cut off partway. Each block has its own install target and its own test targets.
Inside those two install targets the same command appears twice, pinned to the same commit:
git+https://github.com/openvinotoolkit/open_model_zoo.git@e7df86da686d2e1600282422e54f66c2fecea160#egg=accuracy_checker&subdirectory=tools/accuracy_checker
So the accuracy checker comes from Open Model Zoo at a fixed commit, installed from git rather than from an index, and the pin is duplicated in the file rather than shared through a variable. If that commit ever needs to move, there are two places to change and no single declaration of which version is intended.
The test targets differ in what they pass. The main ONNX target takes the coverage arguments, the worker count, an optional data path, and a JUnit XML output. The cross-framework install and example targets run with output unbuffered and a backend flag, and they do not take the coverage or data arguments. So the coverage switch applies to the primary suite and not to the cross-framework checks.
Other switches are all conditional on environment variables: coverage on NNCF_COVERAGE, data on DATA, weekly models on WEEKLY_MODELS, worker count on NUM_WORKERS. The pre-commit target installs one exact version, pre-commit==4.3.0.
The OpenVINO install target ends partway through a line, at pip install -r tests/openvino/requireme.
Editorial conclusion
NNCF fits a team that already has a working PyTorch or OpenVINO model, knows its accuracy target, and wants 8-bit quantization plus pruning rather than an open search over compression recipes. Four things to check first. Which backend you will actually run, since activation sparsity exists on one experimental path and not on the rest, and TorchFX is marked experimental for both post-training algorithms. That a calibration set of roughly 300 samples is enough for your distribution. Whether you want the telemetry package installed at all, since it is a runtime dependency rather than an extra. And which examples directory fits, because llm_compression/ sits in the tree without appearing in the feature tables.
Frequently asked questions
What is NNCF used for?
NNCF is the Neural Network Compression Framework from the OpenVINO toolkit. It provides post-training and training-time algorithms for optimizing neural network inference in OpenVINO with minimal accuracy drop, and works with models from PyTorch, TorchFX, ONNX, and OpenVINO.
Which backends does NNCF post-training quantization support?
Post-Training Quantization and Weights Compression are supported on OpenVINO, PyTorch, and ONNX, and are marked experimental on TorchFX. OpenVINO is described as the preferred backend to run post-training quantization with.
Does NNCF support training-time compression outside PyTorch?
No. The training-time table has only a PyTorch column, listing Quantization Aware Training, Weight-Only Quantization Aware Training with LoRA and NLS, and Pruning. There is no OpenVINO or ONNX column for those algorithms.
Does installing NNCF install OpenVINO?
No. The runtime dependencies do not include the openvino package, even though OpenVINO is the preferred post-training quantization backend. openvino-telemetry is included as a runtime dependency at 2023.2.0 or newer.
How much calibration data does NNCF post-training quantization need?
A small dataset of roughly 300 samples is what the README describes as sufficient to run the algorithm, alongside your model. The usage snippets pass a validation dataset through a transform function to collect the statistics the algorithm needs.
Which Python versions does NNCF support?
requires-python is set to 3.10 or newer, and the version is resolved dynamically from a custom_version.version attribute. The classifier list names only Operating System :: OS Independent and Programming Language :: Python :: 3, with no per-minor-version entries.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openvinotoolkit-nncf)Star history chart for your README
[](https://hysenlabs.com/projects/openvinotoolkit-nncf)Was this useful?