Oracle AI Developer Hub: a monorepo of Oracle 26ai reference apps, not a framework
Technical resources for AI developers to build applications, agents, and systems using Oracle AI Database and OCI services
At a glance
- What is it?
- The repository collects working applications, notebooks and workshops that put Oracle AI Database 26ai and OCI services under an agent stack. It is sample code you read and copy, not a library you install, and several apps trade portability for features that only exist inside the database.
- Who is it for?
- Adopt this repository if you already run Oracle AI Database 26ai and want working patterns for vector search, hybrid retrieval and agent memory inside the same database. Skip it if your data lives elsewhere, because several apps rely on in-database features such as JSON Duality Views, DBMS_VECTOR_CHAIN and per-caller DBMS_RLS row policies, and none of those move with a changed endpoint.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
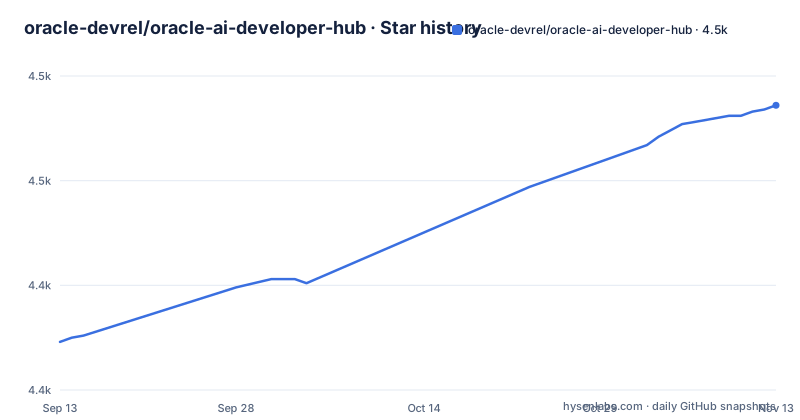
- oracle-devrel/oracle-ai-developer-hub4,486 ★ · +113
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| oracle-devrel/oracle-ai-developer-hub | 4.4k | 4.5k |
113 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A collection of directories, with no package to pip install
Clone first, install later, and only if you want to. Oracle AI Developer Hub is a documentation-shaped repository rather than a distribution: the top level holds apps/, build-paths/, docs/, guides/, notebooks/, partners/ and workshops/, and the project publishes a rendered site at https://oracle-devrel.github.io/oracle-ai-developer-hub/. The primary language is Jupyter Notebook, which tells you what the centre of gravity is. Notebooks for experimentation sit next to complete applications for reading.
There is no hub package to install: the root pyproject.toml holds only tool configuration. Each application under apps/ carries its own requirements, its own deployment configuration and its own documentation, and you copy the pieces you want rather than depending on the parent. What you do get at the root is tooling for working on the repository, not for running it: a pyproject.toml that configures Ruff and Pytest across the whole tree, and a SETUP_PRE_COMMIT.md alongside .pre-commit-config.yaml.
That distinction matters more than it sounds. Nothing here resolves as a dependency, so no version of the hub can break your build, and equally no update reaches an application you already copied into your own repository. You own the fork.
apps/ is the real product, and each entry assumes one Oracle feature
The apps table is the repository's index, and reading it closely shows that the entries are not variations on one sample. FitTracker uses Oracle 26ai JSON Duality Views with FastAPI and Redis. agentic_rag adds multi-agent Chain of Thought and PDF, Web and repository processing. finance-ai-agent-demo treats Oracle AI Database as a unified memory core for vector, graph, spatial and relational queries in one agent.
Then the storage model gets sharper. idp-oracle-ai-database keeps the BLOB, the extracted text, the structured JSON and the vector for a single document in one database, running text extraction, summarization, embeddings, k-NN classification and LLM field extraction inside or from the database through DBMS_VECTOR_CHAIN, with AWS supplying only compute through Lambda, S3 and CloudFront. supplychain-demand-planning-agent runs a LangGraph supervisor over two specialist agents where vector knowledge, long-term memory, per-thread checkpoints, the semantic LLM cache and chat history all share the same Oracle AI Database.
team-brain is the odd one worth reading closely. It mixes Slack, GitHub and documentation connectors into one shared table, computes in-database ONNX embeddings, fuses Oracle Text and vector results with RRF through langchain-oracledb, and enforces per-caller access with a DBMS_RLS row policy on the table itself. It is exposed to Claude Code over MCP (stdio or HTTP) and to a LangChain create_agent CLI. A separate entry, oraviz-mcp, has seven read-only tools that cap what returns to the model's context with 25-row previews and a 500-row hard cap.
Every row of the app table says 26ai, which dates the table
Here is a detail a skim misses. The descriptions name Oracle AI Database 26ai for FitTracker, agentic_rag, idp-oracle-ai-database, generative-ui-data-chat, tanstack-shoe-store, the migration harness and oraviz-mcp, while the repository carries exactly one release, tagged OCW24 and dated 2024-11-19, and its last push was on 2026-10-30.
The table does not state a minimum database version for each app. Check each app's own directory before planning an upgrade, and read the deployment files it ships before you assume a config key is yours to change.
The only commands at the root are lint and test, and the test default hides the stack
There is no install command to copy, so the tutorial is short. Clone the repository, open the app directory you want, and follow that app's own README. At the root, the runnable surface is Pytest and pre-commit, configured in pyproject.toml.
The Pytest configuration declares four markers and then makes the default run skip integration work:
pytest
pytest -m integration
A bare pytest excludes anything marked integration, which the configuration describes as a full-stack test requiring Oracle DB, Ollama or a live server. The same block declares requires_oracle, requires_ollama and requires_playwright, so a run that passes on a laptop with no database and no Ollama says very little about the agent paths. Run the full stack deliberately, not by accident.
Ruff covers the Python side with a line-length of 100 and target-version py311, double quotes, four-space indentation and isort configured with known-first-party entries for oracle and oci. Ruff's target-version points at Python 3.11.
Where the in-database approach stops working
The recurring architecture is to keep embeddings, documents and chat history in the same engine as the relational rows, and to let the database do extraction, classification and caching. That removes a network hop and a second system to operate. It also ties the sample to Oracle.
The failure modes follow from that. An agent whose memory lives behind DBMS_RLS row policies cannot be pointed at a database that has not been configured for row-level security, so team-brain's access control becomes your access control problem on day one. Apps built on DBMS_VECTOR_CHAIN assume a chain you can define inside the database, so moving the corpus elsewhere means rewriting the pipeline, not swapping an endpoint. supplychain-demand-planning-agent keeps its per-thread checkpoints in Oracle AI Database, which means losing the database loses conversation state rather than degrading to a stateless call.
The stated limits also cut both ways. A 500-row hard cap keeps what oraviz-mcp returns to the model's context small.
Against a separate vector store, the difference is operational, not algorithmic
The usual alternative is a standalone vector database or a hosted vector service, with embeddings, chunks and query results living outside the transactional engine while Oracle holds only the relational side. Retrieval quality depends on the embedding model and the ranking function in either case, and the vector-development entry points readers to the separate Oracle VecDB Python SDK for Python-side vector work, which confirms that the client-side route exists alongside the in-database one.
The real difference is where the joins happen. With a split design, a semantic hit has to be hydrated back through application code before you can filter by tenant, status or date. With the in-database designs here, that filtering is SQL against the same table that holds the embedding, which is why team-brain can express access control as a DBMS_RLS row policy and the migration harness can call JSON Duality queries on a corpus it just moved.
The cost of that advantage is concentration. One engine holds the documents, the vectors, the checkpoints and the cache, so its availability ceiling and its upgrade cycle govern the whole application.
Reading the hub as a pattern catalogue rather than a dependency
Treat the repository the way you would treat a set of well-annotated reference implementations. Pick the one app whose data model matches yours, read how it stores state, then port the pattern. supplychain-demand-planning-agent shows a supervisor over specialists with shared storage; team-brain shows connector fan-in with fused retrieval and row-level access; idp-oracle-ai-database shows document processing pushed into the engine with compute borrowed from Lambda and S3.
Take the parts that are portable and leave the rest. Embedding generation, chunking and prompt construction move to any stack. DBMS_VECTOR_CHAIN, Oracle Text plus vector fusion through langchain-oracledb, and DBMS_RLS policies do not.
Fork the app, not the hub, because the only release is the 2024 OCW24 snapshot and nothing here is installed on your behalf. Start with vector-development, then move to the app that matches your use case.
Editorial conclusion
Adopt this repository if you already run Oracle AI Database 26ai and want working patterns for vector search, hybrid retrieval and agent memory inside the same database. Skip it if your data lives elsewhere, because several apps rely on in-database features such as JSON Duality Views, DBMS_VECTOR_CHAIN and per-caller DBMS_RLS row policies, and none of those move with a changed endpoint. Before anything else, verify that vector-development and the app matching your stack target the 26ai features your own database instance actually exposes.
Frequently asked questions
How do I install the Oracle AI Developer Hub?
The repository ships no installable package. Clone it and follow the README inside the app directory you want, since each app carries its own requirements and configuration.
Which Oracle database version do the Oracle AI Developer Hub apps need?
The app descriptions name Oracle AI Database 26ai for entries such as FitTracker, agentic_rag and idp-oracle-ai-database. The README does not state a minimum version per app, so check the individual app directory.
Does the Oracle AI Developer Hub test suite need a running database?
A bare pytest run excludes anything marked integration, which the pyproject.toml describes as a full-stack test requiring Oracle DB, Ollama or a live server. Additional markers covers requires_oracle, requires_ollama and requires_playwright.
What does the vector-development app in the Oracle AI Developer Hub cover?
It holds Oracle AI Database vector sample apps for semantic search, RAG, product discovery, code search and geospatial search. For Python-side work it points to the Oracle VecDB Python SDK.
How does oraviz-mcp limit what it returns to the model?
It exposes seven read-only tools that return compact markdown tables with 25-row previews and a 500-row hard cap, so larger result sets are truncated rather than returned in full.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/oracle-devrel-oracle-ai-developer-hub)Star history chart for your README
[](https://hysenlabs.com/projects/oracle-devrel-oracle-ai-developer-hub)Was this useful?