HippoRAG 2 is published as an alpha while the only release tag is version 1
[NeurIPS'24] HippoRAG is a novel RAG framework inspired by human long-term memory that enables LLMs to continuously integrate knowledge across external documents. RAG + Knowledge Graphs + Personalized PageRank.
At a glance
- What is it?
- HippoRAG is a retrieval framework that builds a graph over your documents and walks it, described as a memory model for language models. Its second generation is the whole page, yet the only release tag is the first generation and the published package is an alpha. The dependency list appears three times in the repository.
- Who is it for?
- The framework fits a research team reproducing a published retrieval result, or anyone who wants the graph-then-walk structure in front of them rather than behind an API. It does not fit a production service that pins versions carefully, because the package is an alpha and the dependency list has three sources of truth.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 40 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
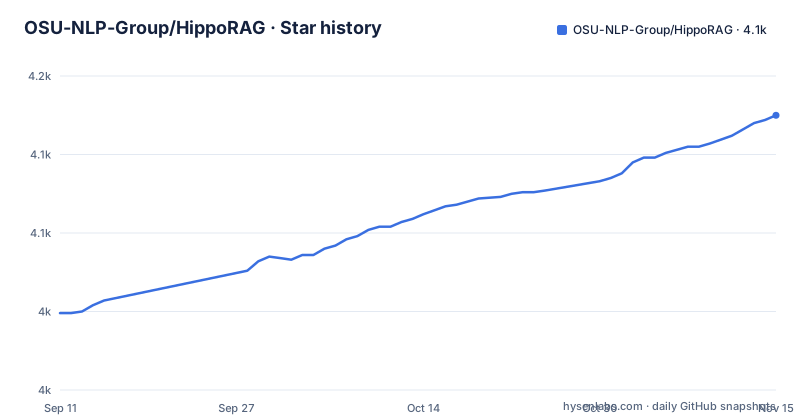
- OSU-NLP-Group/HippoRAG4,125 ★ · +126
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| OSU-NLP-Group/HippoRAG | 4k | 4.1k |
126 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The page describes generation two, the tag says generation one, the package says alpha
The heading of the page is the second generation, from a paper about moving from retrieval to memory. Everything after it, both papers, the installation section, the quick start and the index-upgrade notes, describes that generation.
The release list has one entry. It is the first generation, named as such, published 2025-02-27.
The package metadata declares a version of two point zero point zero, alpha five, in both the project file and the packaging script. So the pip command on the page installs a pre-release of the second generation, and there is no release tag for it at all.
The first generation has not been deleted, either. One of the links near the top of the page goes to a legacy branch, which is where that older code lives now that the main branch is the second generation.
Three versions, three places, and a reader who reads the release list first concludes the project is a year and a half behind where the readme says it is. That is the wrong impression to start from, but it is the impression the release list gives.
Three files declare the same twenty dependencies and nothing checks they agree
The dependency list appears in the project metadata, in the packaging script, and in a requirements file. All three carry the same twenty entries with the same versions, including the two pinned deep learning libraries, the pinned tokenizer, the pinned graph library and the range-constrained client library.
The project metadata is the file a modern build system reads. The packaging script repeats the name, the version, the description, the interpreter floor, the dependencies and the extras, and adds the console entry point. The requirements file repeats the dependencies a third time, with a comment saying the optional local-model dependencies live in two named extras.
The build configuration names a modern build backend, so both of the first two files are read by a single install. Nothing in the repository compares them.
One thing is declared in only one of them, and it is not a dependency: the prompt template files, which the packaging script lists as package data under a prompts directory. A reader who edits the project metadata to add a data file will not ship it.
The compatibility apparatus went to the one range-constrained package
Twenty dependencies, and exactly one of them has a stated policy.
The client library is accepted from a floor within the current major, and the page says that compatible updates inside that major are taken while a new major requires an explicit compatibility review. It then gives two commands for reproducing that review: one that installs from a constraints file, and one that installs the newest allowed release and runs a named test module.
Against that, two dependencies are pinned to exact versions from late 2024, with no policy, no comment and no upper bound, and a third and fourth are pinned the same way. Six packages are pinned outright in a project whose readme is about the second generation.
So the library that changes on a schedule is the one with a review process and a test module, and the library that effectively never changes is pinned silently.
There is a detail in that section too. The command for reproducing the tested baseline points at a constraints file under a directory the repository root does not contain. The command that installs the newest allowed release and runs the compatibility test is the one that works from a checkout.
An index carries the identity of the configuration that produced it
The upgrade section is the densest paragraph on the page and it is about refusing state rather than about migrating it.
The current alpha binds persisted vectors and extracted knowledge to the endpoint, the deployment, the model, the normalisation and the component identity that produced them. An index with no manifest file is rejected. An index whose recorded identity no longer matches the active configuration is rejected rather than mixed. The advice is to re-index into a fresh output directory, and it says plainly that copying or fabricating the manifest is not a safe migration.
There is a second identity, and it is numeric. Two defaults bound the output of the extraction step: two thousand and forty-eight tokens for entities and four thousand and ninety-six for triples, sized to leave room for reasoning. Those two values are part of the identity, and the page names the earlier development defaults, five hundred and twelve and two thousand and forty-eight, and says an index built with them must be re-indexed or loaded with those values set explicitly.
For anyone injecting a custom embedding model or extraction model there is an explicit override: set the identity to a stable version string, so a configuration change cannot silently reuse incompatible state.
The two documented install routes install different things
The installation section gives a Conda route and a project-local route, and the first one is three lines:
conda create -n hipporag python=3.10
conda activate hipporag
pip install hipporag
No version constraint. That installs whatever is on the index, which is the second-generation alpha.
The project-local route creates a virtual environment on the same interpreter version and installs the checkout in editable mode, which installs whatever is in the clone. Same three-step shape, two different artefacts.
The interpreter floor is 3.10 for both, and the page recommends a project-local environment for development.
Then the environment variables, and that block has a small oddity: it activates the Conda environment, exports three variables, and activates the environment again. Harmless, and a leftover from two drafts of the same section.
A response the library cannot cost is not cached at all
The quick start is a context manager, an index call and a query call, with a one-sentence document list. The interesting requirements are in the endpoint section that follows it.
The first is a hard one: an OpenAI-compatible chat or embedding endpoint must return standard token usage data, and the library fails closed rather than caching a response whose token cost cannot be accounted for. That is an unusual choice, and it means a gateway that omits usage breaks the pipeline rather than degrading it.
The second is token-parameter selection, which differs per endpoint. The official hosted endpoints get one parameter name. Gateways with a recognised model-name prefix get whichever parameter they document, with the prefix stripped before the request goes out. Everything else gets the more widely supported older parameter. There is a configuration flag to override the choice when an endpoint needs the newer one, and the page names reasoning models as the case that needs it.
The key handling is per endpoint too. Each side, model and embeddings, can name its own environment variable for its key, defaulting to the one OpenAI variable, and when a variable is unset and the endpoint is a loopback address that needs no authentication, the library supplies a placeholder local to the client rather than mutating the process environment.
The output directory the quick start writes into is committed at the root
The quick start constructs the framework with an output directory argument set to a relative path, and the repository root contains a directory of that name.
So a first run writes into the checkout, and the artefact of that run is in the tree. For a library whose central state is an index directory, that is worth knowing before the first command rather than after it.
The rest of the root is small and explainable. There is a script at the top level next to a source layout, which is unusual and looks like a convenience entry point rather than the package itself. There is a reproduction directory, an images directory for the figures, and seven runnable demonstrations under examples.
Those seven are worth listing because they map to the endpoint matrix the page describes: one for the hosted provider, one for Azure, two for a second cloud provider including a hosted variant of it, one for a gateway, one for a local endpoint, and one shared helper module.
Editorial conclusion
The framework fits a research team reproducing a published retrieval result, or anyone who wants the graph-then-walk structure in front of them rather than behind an API. It does not fit a production service that pins versions carefully, because the package is an alpha and the dependency list has three sources of truth. Check three things before you install. Which generation you are getting, since the documented command has no version and the only tag is the earlier one. Which of the three dependency files your build actually reads. And what happens to an index you already built, because the second generation binds stored vectors to the configuration that produced them and refuses a mismatch rather than repairing it.
Frequently asked questions
What is HippoRAG?
A memory framework for large language models that recognises and uses connections in new knowledge, described in its repository description as retrieval augmented generation combined with knowledge graphs and personalised page ranking. It was published at a neural information processing conference, and its second generation at a machine learning conference.
Which version of HippoRAG does pip install?
The second generation, as a pre-release. The package metadata declares an alpha of version 2, the documented command carries no version constraint, and the repository's only release tag is the first generation from 2025-02-27, whose code now lives on a legacy branch.
Where are HippoRAG's dependencies declared?
In three files at the repository root: the project metadata, the packaging script, and a requirements file. All three carry the same twenty entries with the same versions, and nothing in the repository compares them. The prompt template files are listed as package data in only one of them.
Can I keep an index I built before upgrading HippoRAG?
Only if its recorded identity matches your active configuration. The second generation binds stored vectors and extracted state to the endpoint, deployment, model, normalisation and components that produced them, refuses an index with no manifest or a mismatched one, and recommends re-indexing into a fresh directory rather than editing the manifest.
What does HippoRAG require from an OpenAI-compatible endpoint?
Standard token usage data: it fails closed rather than caching a response whose token cost cannot be accounted for. It also picks the token parameter by endpoint type, with a configuration flag to override, and lets the model and embedding sides read their keys from separately named environment variables.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/osu-nlp-group-hipporag)Star history chart for your README
[](https://hysenlabs.com/projects/osu-nlp-group-hipporag)Was this useful?