LEANN trades stored embeddings for on-demand recomputation, and the bill comes due at query time
[MLsys2026 Best Paper]: https://arxiv.org/abs/2506.08276. RAG on Everything with LEANN. Enjoy 97% storage savings while running a fast, accurate, and 100% private RAG application on your personal device.
At a glance
- What is it?
- LEANN is an MIT-licensed Python vector index for private RAG on a laptop. It keeps a pruned graph and recomputes embeddings when you search, which is where its storage savings come from and where its costs hide.
- Who is it for?
- LEANN suits people who want semantic search over personal files, mail or chat exports on one machine and care more about disk size than raw query speed. Skip it if you need GPU acceleration today, and measure latency and recall on your own corpus before trusting the 97% storage claim.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
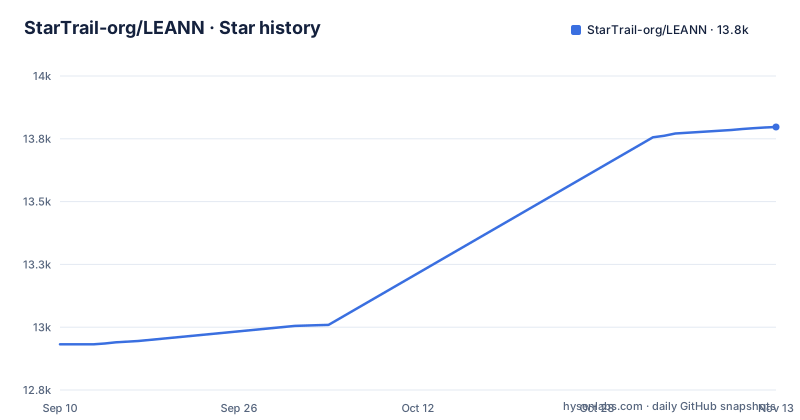
- StarTrail-org/LEANN13,797 ★ · +865
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| StarTrail-org/LEANN | 12.9k | 13.8k |
865 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Embeddings are recomputed per query instead of stored
A conventional vector database writes one embedding per chunk to disk, and that table dominates its size. LEANN keeps a graph and works out embeddings when a search needs them. The project calls this graph-based selective recomputation, paired with high-degree preserving pruning so the graph stays small, and it stores that graph in CSR format. The headline number is 60 million text chunks in 6GB instead of 201GB.
The consequence is that every query spends compute that a stored-embedding index would have paid once at build time. The pitch quantifies storage and does not give a latency figure for a given laptop, so a search over your own corpus is the only way to find out what that trade costs you.
The 97% storage saving and the no-accuracy-loss claim come from the authors
The repository description points to a paper at arxiv.org/abs/2506.08276 and labels it an MLsys2026 Best Paper. The 97% less storage figure and the statement that search quality matches heavyweight solutions are both the project's own claims, backed by its paper and its per-application storage comparison.
That comparison covers the data types the authors chose. Your mix of PDFs, mail and chat logs may compress differently, and recall depends on your embedding model and your questions. If retrieval quality matters for your use, build the same corpus into a conventional index and compare answers side by side before you delete anything.
Hardlinked installs break leann build on Linux
The quick install clones the repository for its examples and then installs the package from PyPI inside a uv virtual environment:
git clone https://github.com/StarTrail-org/LEANN.git leann
cd leannuv venv
source .venv/bin/activate
uv pip install leannOn Linux, the install comment says to use the cpu extra, for example leann[cpu], for a CPU-only setup. There is also a known failure. If a later leann build stops with Security Violation [pathsec.open]: refusing multiply-linked file, the cause is uv's default hardlink installs tripping the hardened file loader in nltk, which ships with llama-index. The fix is to reinstall with UV_LINK_MODE=copy uv pip install --reinstall ..., or UV_LINK_MODE=copy uv tool install --reinstall ... if you installed as a tool. Anyone who hits this on a fresh Linux box loses the first build to an error that looks unrelated to LEANN.
Building from source drags in the DiskANN toolchain
The source route is for development and starts with a submodule checkout:
git clone https://github.com/StarTrail-org/LEANN.git leann
cd leann
git submodule update --init --recursive
On macOS the system packages are installed first, then the diskann extra is synced:
brew install libomp boost protobuf zeromq pkgconf
uv sync --extra diskann
DiskANN needs macOS 13.3 or later, so older Macs cannot take this path. On Ubuntu 20.04 you may have to build a newer Abseil and pin Protobuf to something like v3.20.x before DiskANN compiles, and the project points to Issue #30 for the step-by-step note. Intel oneAPI MKL can be installed by hand in place of libmkl-full-dev. The practical cost is that a pip install gets you a working index while a source build gets you a compiler problem on older systems.
The workspace pins protobuf and transformers tightly
The repository's pyproject.toml defines a workspace named leann-workspace at version 0.1.0 that requires Python 3.10 or newer. Two pins stand out. protobuf is fixed at ==4.25.3, and on Python 3.10 and above transformers must be at least 4.53.1 and below 4.58. The list also includes torch, sglang, ollama, openai, boto3, sentence-transformers, several PDF parsers (PyPDF2, pdfplumber, pymupdf, pypdfium2), and tree-sitter grammars for Python, Java and C# used by AST-aware code chunking. On Apple Silicon it adds mlx and mlx-lm.
If you install the workspace into an environment that already holds another protobuf or a newer transformers, expect a resolver conflict. Give LEANN its own virtual environment. The openai, boto3 and ollama entries also mean the dependency set is wider than a purely local stack, so check which embedding or LLM provider a given example uses before you assume nothing leaves the machine.
The coding-agent benchmark is 30 tasks against BM25 only
LEANN ships as a semantic search MCP service that works with Claude Code, whose built-in search is grep-style keyword matching. The project tested it against BM25 on 30 SWE-Bench Pro tasks from ContextBench, holding the model, agent, tools and an 8,192-token retrieval budget fixed. Reported results: 24.2% initial relevant-code recall against 11.4% for BM25, 38.4% relevant-code coverage after exploration against 25.8%, and 3.22M tokens against 3.51M, which is 8.4% fewer.
The limits are stated by the project itself. These are macro-averaged annotated gold-line metrics, and better context access does not guarantee issue resolution. The comparison is against BM25, not against other embedding indexes, and 30 tasks is a small sample. A reproduction recipe sits in benchmarks/contextbench/README.md, which is the place to start if you want to check the numbers on your own repository.
Releases arrived after a six-month gap, and GPU support is still a survey question
The repository is not archived. The last push was on 2026-11-02, the same day as v0.3.9. Before that, v0.3.8 landed on 2026-09-28 and v0.3.7 on 2026-03-08, so there was a gap of roughly six months between the first two. All three are 0.3.x releases, which tells you the interface is still pre-1.0.
The project says it tracks zero telemetry and uses a short survey to ask whether users want GPU acceleration or more integrations next. That means GPU acceleration is a vote, not a delivered feature, so recomputation runs on whatever CPU or Apple Silicon hardware you have. The README also links a Slack community and the GitHub issue tracker for help, including invite trouble.
Editorial conclusion
LEANN suits people who want semantic search over personal files, mail or chat exports on one machine and care more about disk size than raw query speed. Skip it if you need GPU acceleration today, and measure latency and recall on your own corpus before trusting the 97% storage claim.
Frequently asked questions
How does LEANN reduce vector index storage?
It uses graph-based selective recomputation with high-degree preserving pruning, computing embeddings on demand instead of storing them all. The project claims 60 million chunks fit in 6GB instead of 201GB.
What does LEANN need to build from source on macOS?
macOS 13.3 or later for DiskANN, plus brew install libomp boost protobuf zeromq pkgconf and then uv sync --extra diskann after initializing the git submodules.
Why does leann build fail with a multiply-linked file error on Linux?
uv's default hardlink installs trip nltk's hardened file loader bundled with llama-index. Reinstalling with UV_LINK_MODE=copy fixes it.
Is LEANN actively released, and what license does it use?
It is MIT licensed and not archived. The last push was 2026-11-02, the same day as release v0.3.9.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- LeannHacker News · Oct 26, 2026 · 1 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/startrail-org-leann)Star history chart for your README
[](https://hysenlabs.com/projects/startrail-org-leann)Was this useful?