Oxylabs AI Mode scraper: a repository with no code and a 400 character query cap
Scrape Google AI Mode responses without blocks on a large scale.
At a glance
- What is it?
- This repository is a request sample, a parameter table and a sales page for a hosted SERP endpoint that returns Google AI Mode answers as parsed JSON. What is worth reading closely is the interface it documents and the gaps it leaves: a mandatory HTML render for a JSON product, two different status codes in one payload, a schema the README warns will change per query, and example links frozen at one commit hash.
- Who is it for?
- Treat this as documentation for a paid API rather than as a library, because that is what it is, and the sample code is thirty lines you could write yourself once you have credentials.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
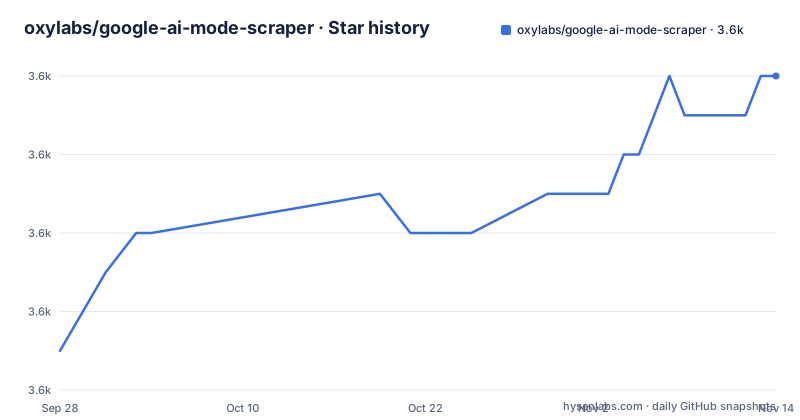
- oxylabs/google-ai-mode-scraper3,632 ★ · +7
| Repository | 2026-09-28 | 2026-11-14 |
|---|---|---|
| oxylabs/google-ai-mode-scraper | 3.6k | 3.6k |
7 Stars in the last 47 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three parameters are mandatory and one defaults to false
The request table is the whole interface, and it is small. Three parameters are mandatory: `source`, which must be set to `google_ai_mode` to select the scraper, `query`, the prompt itself, which cannot exceed 400 characters, and `render`, where `html` is required for this source. That last one is the odd requirement in the table, since the product's pitch is parsed JSON rather than rendered HTML, and the documentation does not explain why an HTML render is the prerequisite for it. `parse` defaults to `false` and turns parsed data on when set to true, `geo_location` names the country the prompt is sent from, and `callback_url` takes an endpoint for push delivery. The default column is inconsistent too, mixing a dash character with a hyphen for the same meaning of not applicable, so a reader parsing the table has to normalise it.
The sample posts to one endpoint with credentials in a tuple
The whole request is thirty lines and one POST. Install `requests`, then:
import json
import requests

# API parameters.
payload = {
    'source': 'google_ai_mode',
    'query': 'best health trackers under $200',
    'render': 'html',
    'parse': True,
    'geo_location': 'United States'
}

# Get a response.
response = requests.post(
    'https://realtime.oxylabs.io/v1/queries',
    # Replace with your credentials.
    auth=('USERNAME', 'PASSWORD'),
    json=payload,
)

# Print the response to stdout.
print(response.json())

# Save the response to a JSON file.
with open('response.json', 'w') as file:
    json.dump(response.json(), file, indent=2)
Note what the sample does not do. There is no retry, no timeout, no status check on the HTTP response, and it calls `response.json()` twice rather than once, so a non-JSON error body surfaces as an exception rather than a message. Authentication is HTTP basic with the username and password sitting in the source file as placeholders, and `geo_location` is sent as a plain country name. The response is written to disk with an indent so a human can read it, which is a reasonable default for a first call and a poor default for a loop.
Two status codes, one for the job and one for the parse
The output is a job envelope. At the top level sit `url`, `page`, `content`, `created_at`, `updated_at`, `job_id` and `status_code`, where the last one is the status of the scraping job itself. Inside `content` there are `links` for the external references shown in the side box, `prompt` for the original prompt, `citations` for the citation list in the main block, `response_text`, `markdown_text`, and `parse_status_code`, the status of the parsing operation alone. So a successful job can carry a failed parse, and the two fields are the only way to tell that apart. The schema documentation adds a warning that matters more than the field list: depending on the search query, both the number of items and the fields included can change. A consumer that treats this as a fixed schema will break on the first unusual prompt.
The JSON sample ends mid object and the HTML section is empty
The output samples section has two headings. The JSON one opens an object, shows a `results` array with one content object, two real citation entries and then an elided third, and stops in the middle of the `citations` array at an opening brace. The second heading, for an HTML example, has nothing under it at all, even though `html_example.png` sits in the repository tree as an image showing what that example would have been. A reader who needs the HTML output shape has to look at a picture or at the full sample file. The full JSON sample is linked, and it is one of the links worth reading carefully, because the two example links in the README are not to the current branch.
Both sample links are pinned to one commit hash
The link to the full JSON output sample points into the blob view of a specific commit, and the link to the language samples points into the tree view of the same commit. Both carry a forty character hash in the path. Nothing in the README links to `main` or to a directory, so a reader who clicks through sees a frozen snapshot and has no way from the page to tell whether it is the current state. For an example file that is defensible, since samples should not drift under a reader's feet, but here the same hash is used for the code examples directory as well, which is where drift actually matters. The repository's default branch is `main` and the last push was 2026-08-21, so there is content on the branch that the README's own example links do not show.
There is no source code and the language field says Java
The entire top level of the repository is `README.md`, `output-sample.json`, a directory named `Code examples`, and three images: `ScraperAPI+GoogleAI-1090x275px.png`, `html_example.png` and a GitHub repositories banner. There is no build file, no library, no wrapper, no test and no licence file. Repository metadata reports the primary language as Java, which comes from the language sample files inside the examples directory rather than from anything that ships. The licence field is empty, so neither the metadata nor the tree tells you what you are licensed to use the samples under. The interesting number is the shape of the audience: 3628 stars against 32 forks and zero open issues, which is the ratio you get when a repository is a signposting page rather than a codebase.
The first badge is an affiliate link carrying a transaction id
The header line before the title is a link to the vendor's product page, and it is not clean. It carries `utm_source=877`, `utm_medium=affiliate`, `utm_campaign=llm_scrapers`, `utm_content=google-ai-mode-scraper-github` and a `transaction_id` of thirty-two hex characters. A second badge links to a Discord invite, a third to the vendor's YouTube channel, and a callout later in the file offers a free trial on the vendor's dashboard. So the path from the repository to a paying account is laid out in the first three lines and repeated at the point where the request sample is introduced. None of that is hidden, and affiliate tracking on an open source README is normal practice. It does mean the repository should be read as the top of a sales funnel, which is the frame to keep in mind when weighing the use cases listed further down.
The legality question is answered with a referral
The first entry in the README's own FAQ asks whether it is allowed to scrape AI generated content from Google, and the answer is that legality depends on factors like Google's terms of service, your use case and applicable laws, followed by a recommendation to consult a legal expert before proceeding. That is the honest answer and it is also the only one available, since the vendor cannot grant permission on Google's behalf. The second question, about limitations of the scraper, is answered with a single word in this copy of the file and then cut off. The use cases the README does commit to are monitoring brand presence in AI results, adapting content for AI driven search interfaces, and gathering responses as training data, which is the one that carries the most legal weight of the three.
Editorial conclusion
Treat this as documentation for a paid API rather than as a library, because that is what it is, and the sample code is thirty lines you could write yourself once you have credentials. Read the parameter table before budgeting anything: the 400 character query cap will shape how you chunk prompts, the mandatory html render is unexplained, and parse defaults to false, so an unparsed response looks like an empty one unless you check parse_status_code separately from status_code. Treat the response schema as unstable, since the project itself says fields and item counts vary by query. And settle the legal question for your own use case before writing the first call, because the repository explicitly declines to answer it.
Frequently asked questions
Is scraping Google AI Mode legal?
The project's own FAQ does not claim permission. It says legality depends on factors like Google's terms of service, your use case and applicable laws, and recommends consulting a legal expert before proceeding. Nothing else in the repository addresses the question.
What does the Google AI Mode scraper require in a request?
Three mandatory parameters: source set to google_ai_mode, the query prompt capped at 400 characters, and render set to html for this source. parse defaults to false and switches parsed data on, geo_location names the country the prompt is sent from, and callback_url takes a push endpoint.
Which fields come back from the google_ai_mode source?
url, page, content, created_at, updated_at, job_id and status_code at the top level. Inside content: links, prompt, citations, response_text, markdown_text and parse_status_code, which reports the parse rather than the job. The README warns that the number of items and the fields present can change with the query.
What is actually in the oxylabs google-ai-mode-scraper repository?
No source code. The top level holds README.md, output-sample.json, a Code examples directory, and three images. Metadata reports Java as the primary language, which comes from the sample files rather than from anything that ships, and the licence field is empty with no licence file in the tree.
Can the Oxylabs AI Mode scraper return markdown instead of JSON?
The response includes content.markdown_text next to content.response_text, so both arrive in one call. The README points at the result processing documentation for output types including Markdown, and suggests that format for integrating with AI tools.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/oxylabs-google-ai-mode-scraper)Star history chart for your README
[](https://hysenlabs.com/projects/oxylabs-google-ai-mode-scraper)Was this useful?