Convert.to.it crosses media instead of staying inside one format family, and it has a rubric for format requests
Truly universal online file converter
At a glance
- What is it?
- A look at a browser-based file converter whose two arguments are that conversion should leave the medium and that your file should not need a server: a handler architecture with a naming convention and a registration array, a three-part rubric for format requests with a licence check, a cache the first page load builds in your browser, compose files that live in a subdirectory so every command needs a flag, and an Electron desktop build the readme's deployment section never mentions.
- Who is it for?
- Convert.to.it fits someone who needs a one-off conversion that crosses formats, in a browser, without uploading the file to a third-party server. It does not fit someone who needs a guaranteed format matrix, because the project says outright that there are formats it does not support, and the project's own rule for new formats is deliberately high.
- Can I use it commercially?
- Yes, with conditions. GPL-2.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
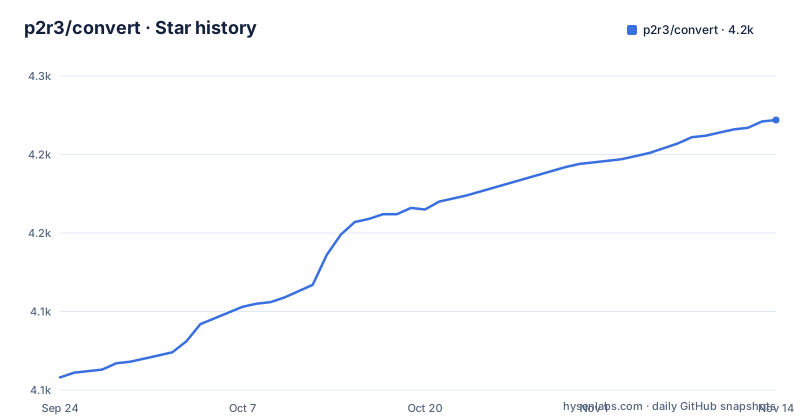
Star history
- p2r3/convert4,222 ★ · +164
| Repository | 2026-09-24 | 2026-11-14 |
|---|---|---|
| p2r3/convert | 4.1k | 4.2k |
164 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The pitch is a single argument: conversion should not stay inside one medium
The readme opens by criticising other online converters on two counts, and both are about limits rather than about quality.
The first is that they only allow conversion between two formats in the same medium, images to images or videos to videos. The second is that they require you to upload your files to some server.
The upload point is framed as a privacy problem and the medium restriction as a boredom problem, and the readme is blunt about the second one, offering a challenge to go and find an online tool that converts an AVI video into a PDF document.
That example is the whole project in one sentence. It is not a feature list; it is a claim that the interesting conversions are the ones a format-family converter refuses, because those are the ones where the source and the target are different kinds of object rather than two encodings of the same thing.
The stated goal follows from it: a tool that just works, where you are almost guaranteed to get an output, perhaps not always the one you expected, but the tool will try its best not to leave you hanging. That last clause is a deliberate promise about failure behaviour. It is saying that when a conversion is imperfect you still get a file, which is a different contract from getting an error.
There is a video linked as a semi-technical overview, and the maintenance position is visible in the release list: a tag named latest, titled as a rolling release, and a tag named prebuilts for prebuilt artifacts. There is no version to pin.
Format requests have three written requirements and one of them is a licence check
The issues section exists because the project was, in its own words, spammed with requests for niche formats after the video came out, and the response is a written policy rather than a slower reply queue.
The policy opens with an important notice that simply asking for a file format to be added is not a meaningful issue. The reasoning is arithmetic: there are thousands of file formats, adding support for one can take hours, and the project already knows which formats it does not support, so a ticket listing favourites adds nothing.
A request has to meet three conditions at minimum. First, check that there is not already an issue and that the format is not already supported. Second, explain what you expect the conversion to be like, in terms of what medium it converts to or from, with a specific warning attached: simply parsing the underlying data is not sufficient. The illustration given is treating SVG images as raw XML and not supporting conversion to raster images, which would defeat the point, and the phrase used for the wrong approach is a crude binary waterfall.
Third, provide links to existing browser-based solutions if possible, or at least a reference for implementing the format, and make sure the licence is compatible with GPL-2.0.
The stated reason for all three is a ratio: a developer has to do a hundred times more work to actually implement a format than the requester does to write it up. Doing the research saves time and weeds out unserious proposals.
A bug report has to say the conversion worked, and differ from what you expected
The bug report policy is two paragraphs and it draws a line that is more useful than the format policy.
For a bug report you only need the first step of the format rubric: check that the problem is not already reported. That is all. And the text says bug reports are generally quite important otherwise, which is a rarer thing for a project with a strict issue policy to say.
Then the distinction. Writing that converting X to Y does not work is not a bug report. Writing that converting X to Y works but not how you expected probably is a bug report.
That is a precise definition of a bug in a converter, and it follows from the project's promise. The stated goal is that you are almost guaranteed to get an output, so a failed conversion is not the failure mode being designed against. The failure mode is a conversion that completes and produces something that is technically an output of the right format but wrong in content.
So if a conversion fails outright, the project's position is that the format is probably unsupported rather than that the code is broken. If a conversion succeeds and the result is wrong, that is the case where the handler's behaviour is the bug.
The rest of the contribution guidance is one line: adding support for new formats is the best way to contribute, and if you have no format to add, the issues have plenty of suggestions.
The first page load builds the format list in your browser, and there is a command for that
There is a performance footnote in the deployment section that is worth reading before you file anything about the tool being slow.
When you first open the page, it takes a while to generate the list of supported formats for each tool, and the browser console complains about missing caches while it does it. That first visit is paying for a cache the project cannot ship.
The fix is one command. You generate the list beforehand and save it into the dist directory by running the cache build script after a normal build, and the optional step is labelled as recommended for performance. If your changes seem not to be applying, the advice is to delete dist/cache.json.
The manifest shows two variants of that script. One writes a minified cache file, the other writes the same file without minification, which is the development version. Both take the output path as an argument, so the cache is a file you can inspect, diff and delete rather than an opaque store.
Everything runs on Bun. Local development is four steps: clone the repository, install Bun, run the install, and run the dev script. The dev and build scripts both start with the same assembly step before the bundler runs, so there is one code generation phase shared by both.
Compose files live in docker/, so every documented command needs -f from the root
The container story has an unusual wrinkle that will waste ten minutes of your first attempt if you miss it.
The compose files are in the docker subdirectory rather than the repository root, which means you cannot run compose from the root without naming the file. The prebuilt route is:
docker compose -f docker/docker-compose.yml up -dThe alternative is to download the compose file separately and run compose in that directory instead, where the default lookup finds it.
The second route builds the image locally, and it adds the override file to the command so compose merges the two:
The application then runs on a subpath rather than the root, at a convert path under localhost on port 8080. That matters if you put anything in front of it, since the base path is not a bare slash.
The build is slow the first time and the readme says why: Chromium and related system packages are installed in the build stage, needed by Puppeteer in the cache script. Later builds are much faster because of Docker layer caching. So the first build is installing a browser, and the cache script is the reason.
One more detail is in the manifest rather than the readme. The image build passes a build argument carrying the current commit hash, computed with git, and the name of that argument is a Vite environment variable prefix, so the commit is baked into the front end at build time.
There is an Electron desktop build that the deployment section never mentions
The manifest describes a desktop application that the readme's deployment section does not mention.
The package entry point is an Electron main file built from the src directory into dist-electron, and there are seven desktop scripts. The build sets an environment variable marking the build as a desktop one before running the bundler, and then regenerates the cache file. The preview step runs electron against the current directory. The start step chains the two. And there are three distribution scripts, one each for Windows, macOS and Linux, each running electron-builder with publishing disabled.
So the project has three delivery shapes: a website, a container, and a desktop application, and only the first two appear in the deployment section of the readme.
That gap is worth knowing about for two reasons. If you are evaluating it as a desktop application, the capability is there and the packaging is set up for all three desktop platforms. If you are contributing, the desktop flag changes the build, and a change that works in the browser may not behave the same way in that mode.
The same pattern shows up elsewhere in the manifest. The version is 0.0.0, the package is marked private, and there is no conventional version to look up: the release list has two entries, a tag named latest with the title announcing it as a rolling release and a tag named prebuilts for prebuilt artifacts.
A handler has a naming convention, a registration array, and responsibility for the filename
Adding a format means writing a typed class, and the readme gives a barebones template plus two rules that are easy to miss.
The template is a class implementing the handler interface, with a name field set to the tool's name, a supported formats array built from format builders, a readiness flag, an asynchronous init method, and the convert method. The format builder chain is where the direction is expressed: a lossless modifier and a from-to direction for one format, a single direction for another, with a comment in the template noting that modifiers go before the direction. New formats themselves are added to a separate formats module.
The first rule is the naming convention. If the tool is called dummy, the class is called dummyHandler and the file is called dummy.ts. Tool name, class name and file name are three fixed strings derived from one identifier.
The second rule is where the filename of the output comes from. The handler is responsible for setting the output file's name, and the stated reason is flexibility in the rare cases where the full file name matters.
After the class exists, one more edit: an empty entry in the handlers array in the handlers index, so the handler can be used in conversions. The readme points at the doc comments in the handler interface file for how the pieces fit together, and at the existing handlers for a practical example, since a template that does nothing is not much of a demonstration.
Bun for the toolchain, oxlint and oxfmt for quality, and husky for the commit
The tooling choices are visible in the manifest and the tree, and they are internally consistent.
The runtime and package manager is Bun, which is why the lockfile is a bun lockfile rather than an npm or pnpm one, and why most scripts in the manifest are invoked through bun run. The build system is Vite, with a build script that assembles first, then typechecks with TypeScript, then bundles.
Quality is handled by two tools with configuration files at the root, both written in TypeScript: oxlint.config.ts and oxfmt.config.ts.
There is a husky directory for git hooks.
The build scripts themselves are not a single command. Six of them delegate to one script with different subcommands: assemble, prebuild, check, upload, patch and add. The dev, build and desktop build scripts all begin by running the assemble step with an all flag, which is why the dev server can start from a fresh clone without a separate generation pass.
One repository-level detail: there is a git-blame-ignore-revs file, which lists commits to exclude from blame. That file exists because the codebase has been through a bulk reformat, and it is the courtesy equivalent of the release history: it keeps the blame view pointing at the change that matters rather than at the reformat that touched every line.
Editorial conclusion
Convert.to.it fits someone who needs a one-off conversion that crosses formats, in a browser, without uploading the file to a third-party server. It does not fit someone who needs a guaranteed format matrix, because the project says outright that there are formats it does not support, and the project's own rule for new formats is deliberately high. If you self-host it, run `bun run cache:build` after `bun run build` so the format list does not have to be generated on first load, and if you are thinking of adding a format, read the rubric first: you need a browser-based implementation or a reference, a licence compatible with GPL-2.0, and an argument about the conversion's medium rather than a demonstration that the bytes can be parsed.
Frequently asked questions
How do I convert a file with Convert.to.it?
Open the site, click the big box or drag a file onto the window, check that the input format was detected or search for it, choose an output format from the second list, and click Convert. The tool converts between media rather than only within one format family, and the file is processed in the browser rather than uploaded to a conversion server.
Can Convert.to.it convert a Visio or SolidWorks file to PDF?
The project's premise is that conversion should not be restricted to one medium, and it names converting an AVI video into a PDF document as the kind of request other tools refuse. Whether a particular format is present depends on whether a handler exists for it. New formats are gated by a rubric that requires a browser-based implementation or a reference and a licence compatible with GPL-2.0.
How do I run Convert.to.it locally instead of using the website?
For development, clone the repository, install Bun, then run bun install and bun run dev. For a container, the compose files live in the docker subdirectory, so the command needs a file flag from the repository root, and the result serves on a convert path under localhost on port 8080.
Is Convert.to.it a server-side converter?
It is described as browser-based, and one of its two stated criticisms of other online tools is that they require you to upload your files to some server. The package manifest describes it as a truly universal browser-based file converter. You can also run it yourself locally with Bun or as a container.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/p2r3-convert)Star history chart for your README
[](https://hysenlabs.com/projects/p2r3-convert)Was this useful?