markdown-crawler turns a site into one Markdown file per page
A multithreaded 🕸️ web crawler that recursively crawls a website and creates a 🔽 markdown file for each page, designed for LLM RAG
At a glance
- What is it?
- Paul Pierre's crawler walks a site breadth-first by depth and writes each page to disk as Markdown with BeautifulSoup and markdownify, aimed at RAG corpora and fine-tuning data. It resumed development after two and a half years with version 0.0.9, which fixed six issues, and its own documentation contradicts itself about which command-line flags exist.
- Who is it for?
- markdown-crawler fits a static, well-linked documentation site you want as a clean corpus, especially when you need to strip navigation and keep the article body. It does not fit a JavaScript-rendered application, an authenticated area, or a crawl large enough that politeness matters.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 142 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
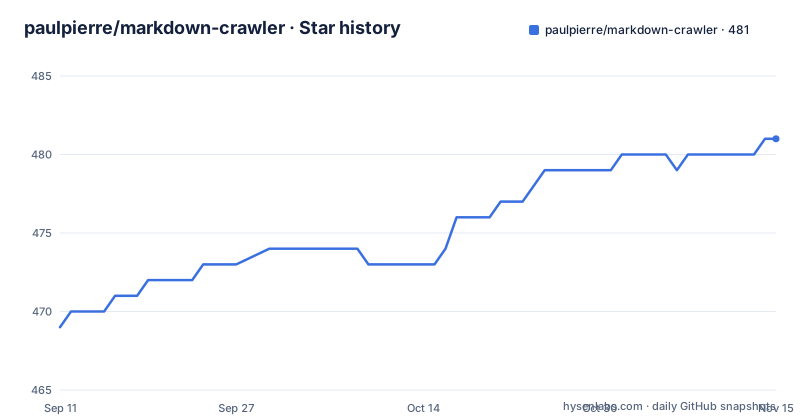
Star history
- paulpierre/markdown-crawler481 ★ · +12
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| paulpierre/markdown-crawler | 469 | 481 |
12 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Markdown as the intermediate format, not the goal
The premise is that retrieval pipelines want documents, not pages. Walking is straightforward: the crawler visits a site, parses each page with BeautifulSoup, converts the HTML with markdownify, and writes one Markdown file per URL. The stated reason is chunking, and it is a good one: Markdown keeps document structure, so a chunker can split by header, paragraph or sentence instead of by token count, and the files stay readable and small on disk. The format choice also makes the output inspectable, which is the property that matters when a corpus turns out to be missing the pages you expected. The HTML-to-Markdown step is delegated entirely to markdownify, credited in the README to Matthew Tretter, so the fidelity of the output is that library's behaviour rather than this project's. Licence is MIT in a LICENSE.txt carrying a 2023 copyright, so the legal text has not been touched since the earlier releases.
Two and a half years, then six issues in one release
The release history has three tagging schemes: `markdown-crawl-0.0.4` in October 2023, `markdown-crawler-0.0.8` a week later, and `v0.0.9` on 2026-06-26, the same day as the last push. The long gap is the interesting part, because version 0.0.9 is where the project resumed rather than started. Its contents are a maintenance release: UTF-8 on every file write to fix a UnicodeEncodeError on non-ASCII content, a browser-like User-Agent header, a new `--exclude-paths` and `-x` flag, null href links skipped instead of crashing target-content selection, an UnboundLocalError fix in `get_target_content`, dependencies declared in `pyproject.toml` so the package can be launched through uvx without a separate install step, and a configurable `heading_style` for markdownify accepting styles such as ATX and UNDERLINE. That release ships 60 tests at 95 percent coverage.
The example flags and the usage block disagree
The documented invocation uses short options:
pip install markdown-crawler
markdown-crawler -t 5 -d 3 -b ./markdown https://en.wikipedia.org/wiki/Morty_Smith
The usage block printed a few paragraphs later lists only long options, `--max-depth`, `--num-threads`, `--base-dir`, `--debug`, and no short forms at all, so the mapping from `-t`, `-d` and `-b` to their long names is left to the reader. One malformed entry sits in the same block, for `--links`, printed with an empty metavar. Small documentation defects, but they sit in the two places a new user reads first, and the CLI is the primary interface of this project.
target_content is what separates a corpus from a dump
The configuration knobs that matter are the filtering ones. `target_content` takes a CSS selector such as `div#content`, so only the article body is converted and the site chrome is dropped; several selectors concatenate. `valid_paths` restricts crawling to an explicit list of relative paths. `domain_match` and `base_path_match` decide whether the walk stays inside the starting domain and inside the starting path. `--exclude-paths` does the opposite of an allowlist. `example.py` sets `max_depth` to 3, five threads, and writes into a `markdown` directory, with `is_debug` on for verbose logging. The usage listing also carries `--target-links` for choosing which links are followed and a `--links` entry whose metavar is missing, so the two sections are not describing quite the same surface. Set those five things and the crawler produces a corpus; leave them and it produces a copy of your navigation.
A User-Agent header is not a browser
Version 0.0.9 added a browser-like User-Agent header on every request, described as bypassing JavaScript checks. Worth being precise about what that buys: a User-Agent string is a header, not a JavaScript engine, so a page whose content is assembled client-side will still hand the crawler an empty document container, and no amount of header spoofing changes that. Sites like that need a different class of tool. What the header does help with is the many sites that serve a bot-challenge page to anything not identifying as a browser, and it is the reason the crawler can get through to static documentation at all.
Resumable crawling, and no politeness settings
Two operational features stand out. Threading gives parallel fetching, described in the docs as five parallel-ish threads, and the crawler can continue scraping where it left off, which matters when a run over a large documentation set is interrupted by a rate limit or a laptop closing. Against that, the documented options contain nothing about a request delay, a concurrency ceiling per host, or robots.txt. The visible README does not mention robots.txt at all, so the etiquette question is left entirely to whoever runs the tool, and the browser-like User-Agent makes following the spirit of a site's policy your own responsibility rather than the default.
Two build configs and an emoji in the package description
Packaging carries both a `pyproject.toml` and a legacy `setup.py`, each declaring the name and package discovery. The `setup.py` excludes a directory called `markdown` from package discovery, which is the tell: that is the crawler's own output directory, and without the exclusion a previous run's output would be picked up as an installable package. The `pyproject.toml` is the real one, with a console script `markdown-crawler = markdown_crawler.cli:main`, `requires-python >= 3.8`, and pinned minimums on beautifulsoup4, markdownify and requests. Its description carries the same spider and download emoji as the README heading, which is the sort of thing that renders as tofu in some terminals and in some package indexes. Dev extras are pytest and pytest-cov, the repository keeps a CHANGELOG.md alongside an `img/` folder of screenshots, and `example.py` sits at the root as the worked reference for the library API.
Search first, then crawl, if you want to be polite
The README offers an alternative to crawling everything: use a search engine to find the relevant pages, take the top N results, and run markdown-crawler over those only. That inverts the cost profile, since the crawl shrinks from a whole site to a result page, and it suits the agent-tool use case the project lists, where a chatbot needs a handful of fresh documents rather than an archive. Listed uses also include a RAG corpus to chunk by header, a fine-tuning corpus to mine for question and answer pairs, and an expert knowledge base for agents built with autogen, the example given being reconstructing the knowledge corpus of a videogame or a film so an agent can answer in character. Where the crawler is the wrong tool is the mirror image of all of that: authenticated areas, client-rendered applications, and any site where you would need to send hundreds of requests a minute.
Editorial conclusion
markdown-crawler fits a static, well-linked documentation site you want as a clean corpus, especially when you need to strip navigation and keep the article body. It does not fit a JavaScript-rendered application, an authenticated area, or a crawl large enough that politeness matters. Verify two things before pointing it at a site: that your pages serve their content in the initial HTML, and that the site permits what you are about to fetch, since the tool offers a browser-like User-Agent to get past checks and documents no rate limit.
Frequently asked questions
How do I install and run markdown-crawler?
Install it with pip install markdown-crawler, then run the CLI, for example markdown-crawler -t 5 -d 3 -b ./markdown followed by a URL. From a checkout of the repository, pip install . does the same thing. Three dependencies are required: BeautifulSoup4, requests and markdownify.
Can I use markdown-crawler as a Python library?
Yes. Import md_crawl from markdown_crawler and call it with the URL and keyword arguments such as max_depth, num_threads and base_path, exactly as example.py in the repository does.
How do I crawl only part of a website with markdown-crawler?
Use target_content with a CSS selector such as div#content so only the article body is converted, restrict the walk with valid_paths, domain_match and base_path_match, and skip specific routes with the --exclude-paths flag. Several content selectors can be given and their results concatenate.
What changed in markdown-crawler version 0.0.9?
Six open issues were resolved: UTF-8 writes for non-ASCII content, a browser-like User-Agent header, the --exclude-paths and -x flag, null href links skipped during target-content selection, an UnboundLocalError fix in get_target_content, and dependencies declared in pyproject.toml for uvx. A configurable heading_style for markdownify was added, with 60 tests at 95 percent coverage.
Does markdown-crawler respect robots.txt?
The visible README does not mention robots.txt, a request delay or a per-host concurrency limit, and it documents a browser-like User-Agent used to bypass JavaScript checks. Ethiquette settings are therefore left to whoever runs the crawler.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/paulpierre-markdown-crawler)Star history chart for your README
[](https://hysenlabs.com/projects/paulpierre-markdown-crawler)Was this useful?