chinese-novelist-skill: five phases in one section, four in another
AI novel writing skill: generates complete Chinese novels of 10-50 chapters from scratch, with three-layer Q&A, creative memory, suspense hooks and automatic verification; suited for both serials and standalone novels. Free and open source, compatible with mainstream coding agents.
At a glance
- What is it?
- An agent skill that writes a complete Chinese novel one chapter at a time, driven by a question sequence, a JSON writing plan and an automatic word count check. Its documentation numbers the phases three different ways, and the quick start gives a single npx install command.
- Who is it for?
- What this project shows most clearly is the shape of an agent skill as a repository: one instruction file, a directory of reference documents split between process and craft, one script that enforces the measurable constraint, and an output directory whose layout is designed to be read by a person rather than only by the tool. Two things to settle before using it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
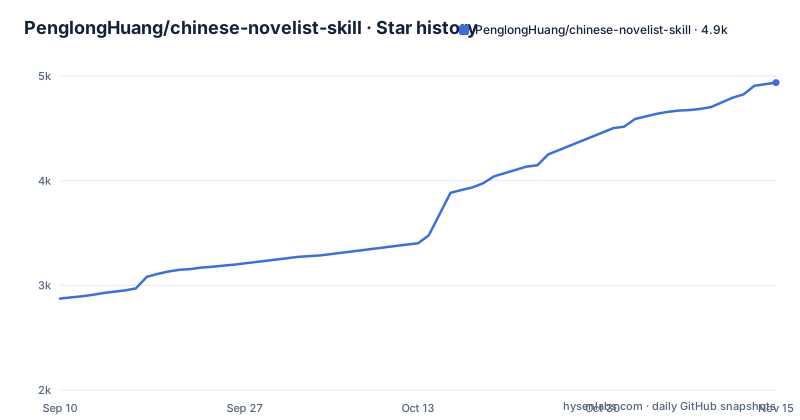
- PenglongHuang/chinese-novelist-skill4,937 ★ · +2,064
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| PenglongHuang/chinese-novelist-skill | 2.9k | 4.9k |
2,064 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The phases are numbered three different ways
The README describes the same pipeline three times and the numbering does not line up. The summary table shows four phases: interactive questions, planning confirmation, creation, and output. The flow diagram that follows starts one phase earlier, at a zero phase for initialisation, and runs to four. And between the planning phase and the creation phase there is a step numbered two and a half, where the writing mode is chosen. So the count a reader gets from the table is four, the count from the diagram is five, and the prose adds a fractional step in the middle. None of it is fatal, since each section is internally consistent, but it does mean a reader following the prose will keep a different count from a reader following the diagram, and neither count is wrong.
Two install instructions for the same skill
The quick start gives one instruction, a command that adds the skill from the repository using a package runner, followed by a line telling the agent which skill to use:
npx skills add PenglongHuang/chinese-novelist-skillThis is the only install instruction in the README. A badge at the top links to Claude Code, while the repository description says the skill is compatible with mainstream coding agents.
Preferences are one JSON file shared across every project
The memory feature is a file, and the file lives at the root of the chinese-novelist output directory rather than inside any novel's project directory. The output layout shows it first, above the per-novel directory: a preferences file with a comment saying it is shared across projects. What gets written into it is a list of tendencies rather than prose: preferred genres, narrative style, a leaning on chapter count, and text density. On the next run those are loaded during the initialisation phase, which is also where an unfinished project is detected so a novel can be resumed from where it stopped. So the memory is not a database and not a transcript, it is a small preference profile that changes the opening questions of the next book, and it is deliberately outside any project directory so it survives across them.
Each chapter runs a five step pipeline with a word count floor
The creation phase writes continuously after one confirmation, with no per-chapter confirmation, and can resume from saved progress if interrupted. Each chapter then follows the same fixed sequence: analysis before writing, the writing itself, a polish pass whose stated purpose is removing the flavour of machine-written text, a word count check, and an update of the summary. The target is stated as a range, three thousand to five thousand words per chapter, and a Python script in the scripts directory is named as the thing that verifies it. The sample progress lines in the README show the shape of a run, with one line per chapter and its count: three thousand two hundred, then three thousand five hundred, then three thousand four hundred. The count is therefore not advisory. A chapter outside the range is the input to the next phase.
Validation rewrites a failing chapter at most three times
The last phase is short and mechanical. When the manuscript is finished the tool checks the chapter files and word counts, and any chapter that fails is repaired automatically, up to three rounds. Coherence and writing quality are reviewed by the agent, and the README says they still need the author's own check. The reference documents make the same split, with one file for the validation phase and separate files for the writing guides.
The writing plan is a JSON file, and the numbering runs backwards
The output layout is the most concrete thing in the README. Inside a directory named with a timestamp and the novel's title sit five metadata files and then one file per chapter. The outline is numbered 01, the character profiles 00, the machine-readable writing plan 02, the style baseline 03 and the chapter summaries 99. The comment on the plan file says it records chapter status and word counts.
Four craft rules, and one of them is a percentage
The writing guides in references/guides/ include a file on ending hooks that claims thirteen distinct types, and a file on dialogue that covers pacing and power dynamics.
There is no GitHub release, but the README points at a version tag
The release badge links to the Releases page, and the README's v2.0 note links to a pull request describing the move from v1.0 to v2.0. The repository publishes GitHub releases; the latest is v2.3.2, published on 2026-10-29, and the last push to the default branch was on 2026-11-01. The root holds one instruction file, a references directory split into process and guides, a scripts directory and an assets directory, which is the standard shape for a skill.
Editorial conclusion
What this project shows most clearly is the shape of an agent skill as a repository: one instruction file, a directory of reference documents split between process and craft, one script that enforces the measurable constraint, and an output directory whose layout is designed to be read by a person rather than only by the tool. Two things to settle before using it. The word count rule is enforced by a script, so a run either lands inside the per chapter range or is rewritten, and that is the constraint most likely to shape your output. And the preferences file is written at the root of the output directory and shared across projects, so on a shared machine the second project's opening questions will already be answered.
Frequently asked questions
What is chinese-novelist-skill?
An agent skill that writes a complete Chinese novel chapter by chapter. It runs a question sequence, produces an outline and character profiles plus a machine-readable writing plan, writes each chapter to a length target, and validates the finished manuscript automatically.
How do I install chinese-novelist-skill?
The README gives one command in the quick start: npx skills add PenglongHuang/chinese-novelist-skill. After installing, you ask the agent to use chinese-novelist to write a novel.
How long are the chapters chinese-novelist-skill writes?
Between three thousand and five thousand words, and the requirement is checked by a script rather than left to the model. A chapter that misses the range is the input to the rewrite step in the final phase.
What writing modes does chinese-novelist-skill offer?
Three, chosen at a confirmation step: a serial mode where the main agent writes one chapter at a time, which is the default recommendation; a parallel mode where sub-agents write in batches for speed; and a team mode described as multi-agent collaboration inside one specific agent product, aimed at large novels.
Does chinese-novelist-skill remember previous sessions?
It claims to. It stores learned preferences, such as genre, narrative style, chapter count tendency and text density, in user-preferences.json at the root of the chinese-novelist output directory, shared across projects, and loads them during initialisation on the next run.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/penglonghuang-chinese-novelist-skill)Star history chart for your README
[](https://hysenlabs.com/projects/penglonghuang-chinese-novelist-skill)Was this useful?