pgBackRest and the mechanics of a fast PostgreSQL backup
Reliable PostgreSQL Backup & Restore
At a glance
- What is it?
- pgBackRest compresses and copies a PostgreSQL cluster in parallel, then keeps serving WAL to the server while the archive fills. That makes it a different tool from a file copy, and a heavier one to configure.
- Who is it for?
- Adopt pgBackRest if your PostgreSQL cluster is large enough that restore time or WAL archive latency is a real constraint, and if you have someone who will maintain the repository layout and the stanza over time. Leave it alone if a single cluster under a few hundred gigabytes fits comfortably on local disk, because the configuration surface is bigger than the problem it solves and a plain base backup needs no repository protocol.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
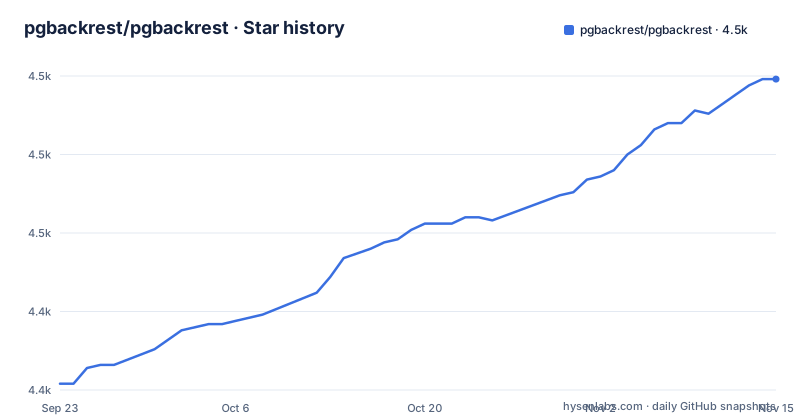
- pgbackrest/pgbackrest4,499 ★ · +97
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| pgbackrest/pgbackrest | 4.4k | 4.5k |
97 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Compression, not disk, is the target
pgBackRest starts from a claim about where backup time actually goes: compression, not copying. The project is written in C and uses more efficient compression algorithms such as lz4 and zstd, and it splits work across processes so that several files are compressed and written at once.
The write path is not a two stage affair. Checksum calculation and compression both happen while the file is being copied, so a file is read once. When the repository sits on a separate host the compressed bytes travel over the link and the repository host stores them as they arrive, doing no further work. With compression turned off it drops to a lower level of compression rather than none, which keeps CPU cost low while still packing the stream for the network.
That design has a cost the reader should price in. Parallel workers reading the data directory compete with PostgreSQL for page cache and IO bandwidth, so the same parallelism that shortens a backup can slow foreground queries while it runs. The README notes that backups can be made from a standby to reduce load on the primary.
One repository protocol, from local disk to S3
Repositories are addressed through a custom protocol layer rather than per backend code paths in each command. That layer lets pgBackRest work with a repository on the same host or one reached over SSH or TLS, and the README also mentions object stores such as S3. Because the protocol also carries PostgreSQL queries, pgBackRest can read what it needs from the database during a backup without requiring remote access to the PostgreSQL port itself. The README presents that as a security benefit.
Multiple repositories are a first class idea rather than an afterthought. A short retention repository on fast local disk keeps restores quick, while a long retention repository on object storage carries redundancy and wider access. Rotation is expressed as retention policy for full and differential backups, and the WAL archive can be kept for every backup or only for the most recent ones, with the WAL still needed to make an older backup consistent retained so the older backup never becomes unrecoverable.
The manifest is what makes resume and delta restore cheap
Every file copied into a backup gets a checksum, and those checksums plus the file list are stored in a manifest in the repository. Two features fall out of that single artifact.
The first is resume. An interrupted backup restarts from where it stopped, comparing the files already present against the manifest rather than copying them again. The comparison can run entirely on the repository host, so the PostgreSQL machine does no checksum work, and because calculating a checksum is faster than compressing and retransmitting a file, a resume after a network drop is much cheaper than starting over.
The second is delta restore. During a restore, files that are not in the backup are removed first, then checksums are generated for the files that remain. Anything that already matches is left untouched and only the rest is restored. On a cluster that was evacuated and then largely rewritten, that is the difference between copying the whole data directory and copying the small part of it that moved. The same manifest drives verify, which rechecks the stored copies against what was recorded at backup time.
The catch is that the manifest checksums record each file as it was when the backup ran, so verify catches storage and transfer damage; page-level corruption already present in the cluster is what the separate page checksum validation is for.
Async WAL push and get, and the guard against a misconfigured archive
Archive handling gets its own pair of commands rather than being folded into the backup path. Both push and get accept parallelism and can run asynchronously, which matters because PostgreSQL blocks on the result. Asynchronous push hands the transfer to a separate process that compresses WAL segments in parallel, so a database with heavy write volume does not stall in archive_command waiting for the network. Asynchronous get keeps a local queue of segments that are already decompressed and ready for replay, which is where high latency storage such as S3 pays off most.
Push is de-duplicating. If a segment that has already been archived is pushed again and is byte identical, the duplicate is dropped; if it is not identical, an error is raised instead of overwriting history. That asymmetry is deliberate.
Both commands compare the PostgreSQL version and the system identifier between database and repository before transferring anything. The reason is operational rather than clever: the README says the check virtually eliminates the possibility of misconfiguring the WAL archive location. This is a detail worth knowing when you read a restore that fails on version mismatch, because it is the guard doing its job.
Where to get it, and what the first run looks like
The repository is built with meson, and release v2.60.0 is the current stable one. The top level of the source tree shows the pieces of a C project rather than a packaged application: src/, test/, doc/, build/, meson.build, and meson_options.txt. The project directs you to its own site, pgbackrest.org, for the current stable version and for change notes, and to its news page for security announcements.
One ordering detail follows from the README: after a backup finishes copying files, it waits until every WAL segment required to make the backup consistent reaches the repository, so WAL archiving has to be working before the first backup can complete.
Page checksum failures warn rather than abort
If page checksums are enabled in PostgreSQL, pgBackRest validates them for each file it copies. All of them are checked during a full backup, and during a differential or incremental only the changed files are checked. The detail that matters is the failure behaviour: a validation failure does not stop the backup. Warnings naming the exact pages that failed are written to the console and to the file log, and the backup completes.
Read one way this is a design flaw, because a backup that knowingly contains bad pages can be recorded as successful. Read the intended way it is a detector: corruption is surfaced early, while backups that still hold good copies of the data have not yet expired, which gives you a window in which the good copy still exists. By default, restore errors when the backup has invalid page checksums, and expire will not leave a backup with invalid page checksums as the oldest backup.
The same reasoning applies to verify. It re-checksums the repository against the manifest, which tells you the stored copy matches what was recorded. It cannot tell you the original copy was good.
Where a plain base backup or another tool fits better
The nearest neighbour is PostgreSQL's own base backup, and the difference is not quality but shape. A base backup produces one copy of the cluster and leaves compression, retention and archive handling to whatever you wrap around it. pgBackRest owns all three, adds parallel restore and delta restore, and stores the result in a repository layout that can be moved to object storage. If your cluster is small, restores are rare, and someone already has a working archive script, the base backup path is fewer moving parts.
Snapshots are the other honest comparison. With compression disabled and hard links enabled, a backup in the repository can be snapshotted and a cluster brought up directly on that snapshot, which is far cheaper than a restore for terabyte scale data. That shortcut depends entirely on shared storage semantics, so on object storage or across hosts it simply does not apply.
Editorial conclusion
Adopt pgBackRest if your PostgreSQL cluster is large enough that restore time or WAL archive latency is a real constraint, and if you have someone who will maintain the repository layout and the stanza over time. Leave it alone if a single cluster under a few hundred gigabytes fits comfortably on local disk, because the configuration surface is bigger than the problem it solves and a plain base backup needs no repository protocol. Before anything else, check whether your storage and network can absorb parallel reads from the data directory without starving the server, then run a full backup and a restore into a scratch location to confirm the manifest and delta path behave on your filesystem.
Frequently asked questions
what is pgbackrest
pgBackRest is a backup and restore tool for PostgreSQL written in C. It compresses with lz4 and zstd, copies files in parallel, and can operate locally or remotely over SSH or TLS.
how to install pgbackrest on ubuntu
The README names v2.60.0 as the current stable release and points to pgbackrest.org for release notes; the source tree builds with meson.
how does pgbackrest stop WAL from mixing between clusters
Both the WAL push and get commands compare the PostgreSQL version and system identifier between database and repository so segments are not mixed with another cluster's archive.
is pgbackrest open source
The repository ships a LICENSE file at the top level of the source tree, but the project page records no SPDX licence identifier, so the terms in that file are what you have to read before relying on it.
pgbackrest is dead
The last push to the repository was on 2026-10-30, and v2.60.0 (Page Checksum Errors and Object Store Prefetch) was released on 2026-10-18. Before that, v2.59.3 fixed a weak encryption subkey bug on 2026-10-04.
how to use pgbackrest
WAL archiving needs to be working before a backup completes, because a backup waits until every WAL segment required to make it consistent reaches the repository. Restores can then use the manifest checksums for a delta restore, and tablespaces can be remapped to any location, including all of them into one directory.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pgbackrest-pgbackrest)Star history chart for your README
[](https://hysenlabs.com/projects/pgbackrest-pgbackrest)Was this useful?