A RAG tutorial that promises no cloud APIs and depends on the openai client
Demystify RAG by building it from scratch. Local LLMs, no black boxes - real understanding of embeddings, vector search, retrieval, and context-augmented generation.
At a glance
- What is it?
- rag-from-scratch is a JavaScript teaching repository that walks through retrieval augmented generation in numbered example directories, each holding an example.js plus two markdown explainers. Its dependency list, its empty test script and its two competing orderings of the pipeline are all visible in the same manifest and the same README.
- Who is it for?
- This repository works as a reading path rather than as something to install: there is no start script, no run command in the visible walkthrough, and the package exports seven subpaths that a learner never has to touch. Use it when you want the chunking, embedding, hybrid and fusion code in front of you rather than a framework call.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
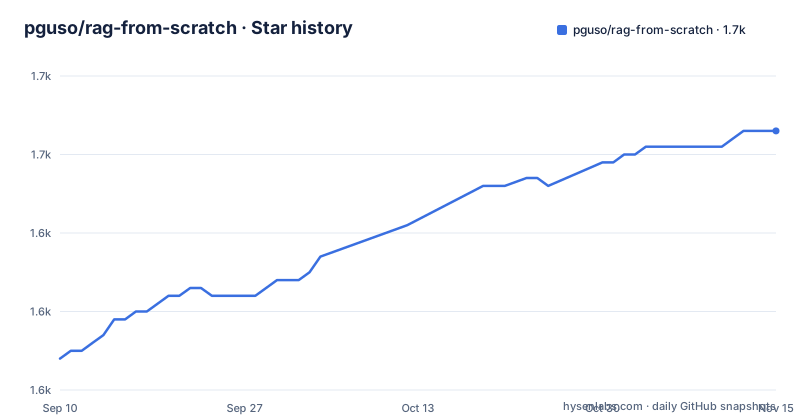
- pguso/rag-from-scratch1,653 ★ · +29
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| pguso/rag-from-scratch | 1.6k | 1.7k |
29 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The no-cloud claim and the openai dependency sit in one manifest
The header states it plainly: no black boxes, no cloud APIs, only clear explanations and local code. The dependency list is more mixed. Local inference is covered by node-llama-cpp at 3.14.2, which is the piece that makes a local model real, and PDF input is handled by pdf-parse. Alongside them sit the openai client at 6.7.0 and node-fetch, which are the two packages a project reaches for when it is talking to a hosted API. Whether any given example uses them is not settled by the manifest, but a reader who installs the tree has installed both, and the line in the README describes the examples rather than the dependency set. Three more packages shape the environment: dotenv for configuration, backed by a .env_example at the root, chalk and boxen for terminal output, and ora for spinners.
The test script is an empty string and the version exists only in the manifest
package.json carries two scripts. One is prepare, set to husky, matching the devDependency on husky 9.1.7 and the .husky/ directory at the root, so git hooks run on install. The other is test, and its value is an empty string, which means npm test has nothing to run and no example in the repository is checked by it. The manifest also leaves description blank and carries no licence field at all, while the licence itself sits as a LICENSE file in the root of the tree. The version is 1.0.0, and that number exists in exactly one place: the repository has no published releases, so nothing on the outside records which commit a given installation came from. The last commit on main is dated 2026-03-11.
Step numbers, directory numbers and the missing step six
The learning path numbers its steps 0, 1, 2, 3, 4, 5, 7, 8, 9 and 10, and six is simply absent from the run. The directory names do not line up with those numbers either. Step 0 points at examples/00_how_rag_works/, step 1 at examples/02_data_loading/, step 2 at examples/03_text_splitting_and_chunking/, step 3 at examples/04_intro_to_embeddings/02_generate_embeddings/, step 4 at examples/05_building_vector_store/01_in_memory_store/, and steps 5, 7, 8, 9 and 10 all live under examples/06_retrieval_strategies/. The tree also holds examples/01_intro_to_llms/, which has no step in the visible list. So one directory holds six of the numbered steps, two steps are labelled with directories two and three steps ahead of them, and a directory that exists in the tree never appears in the order to follow.
The pipeline runs query preprocessing after the retrieval it feeds
The concept overview gives ten numbered stages, ending with augmentation and generation, and two of them are in an order that cannot be the order of execution. Retrieval is stage six, post-retrieval re-ranking is stage seven, and query preprocessing and embedding normalization is stage eight, meaning the query is cleaned and normalized after the results have already been fetched and reordered. The learning-path list tells the opposite story, with basic retrieval at step five and query preprocessing at step seven, and the earlier summary says to normalize and rewrite user queries before retrieval. Re-ranking is worse off: it is a named stage of the pipeline and part of the promised material, yet no re-ranking directory appears in the visible path, which moves from basic retrieval straight to query preprocessing.
Three files per step, and a line-count claim for the first one
Every step in the learning path is the same shape: an example.js holding the code, a CODE.md walking through it, and a CONCEPT.md holding the ideas, each linked separately from the step heading. The claim attached to step zero is a specific one, a minimal end-to-end flow in under seventy lines of code, and nothing in the tree measures it. Step five adds one more file, showcase.js, which is where everything learned so far is put to work, and it is the only example directory in the visible list that has something beyond the standard three. Read together, the layout says the walkthrough is the product and the code is the illustration, which is the opposite of the usual arrangement where the package is built first and documented afterwards.
Seven export subpaths for a package nobody installs
The manifest publishes a library surface: a root export pointing at src/index.js and six named subpaths for embeddings, vector-stores, loaders, text-splitters, retrievers and chains. The package is ESM, so type is set to module, and the subpaths name directories that no step in the learning path mentions. A reader working through the examples is expected to live in examples/, where every script is standalone, while src/ sits beside it as the reusable part. Two supporting directories round out the root: helpers/, and models/, which sits next to a DOWNLOAD.md at the top level, the pair suggesting that model weights are fetched rather than bundled. That is the whole install story the repository offers, and it is the reason the vector store step can depend on an off-the-shelf package at version 0.0.4 while still teaching how nearest-neighbour search works.
Six retrieval strategies, five directories and no reranker
examples/06_retrieval_strategies/ carries the run of the curriculum, and what is inside it explains the missing step number. Its visible subdirectories are basic retrieval with similarity scoring and top-k selection, query preprocessing built on normalization and stopword removal, hybrid search that weights BM25 against embeddings, multi-query retrieval that decomposes a question, runs the parts in parallel and fuses the result lists by reciprocal rank fusion or by weights, with deduplication on the way out, and query rewriting in both heuristic and LLM form. Re-ranking, which the pipeline names as its own stage and the summary promises as a skill, has no directory among them. That leaves a course whose advertised middle stage is the one stage a reader is never walked through.
Editorial conclusion
This repository works as a reading path rather than as something to install: there is no start script, no run command in the visible walkthrough, and the package exports seven subpaths that a learner never has to touch. Use it when you want the chunking, embedding, hybrid and fusion code in front of you rather than a framework call. Three things to check first. The manifest pulls in the openai client and node-fetch even though the header promises no cloud APIs, so confirm which examples reach for a hosted model before assuming the set is fully offline. The npm test script is an empty string, so nothing verifies the examples. And the step numbers in the learning path disagree with the directory names, skip step six, and leave re-ranking promised in the pipeline without a directory of its own in the visible list. The last commit on main is dated 2026-03-11 and the repository has no published releases, so the 1.0.0 in package.json is the only version number available.
Frequently asked questions
What does the pguso rag-from-scratch repository teach?
It walks through retrieval augmented generation in numbered example directories, from a minimal end-to-end flow in under seventy lines through data loading, chunking, embeddings, a vector store, retrieval, query preprocessing, hybrid search and multi-query retrieval with reciprocal rank fusion. Each directory holds an example.js, a CODE.md and a CONCEPT.md.
Does rag-from-scratch need a cloud API key?
The README header promises no cloud APIs and local code, and local inference is handled by node-llama-cpp. The dependency list also includes the openai client and node-fetch, and configuration is read through dotenv from an .env_example at the root.
How do you run an example in rag-from-scratch?
The manifest defines no start script, its test script is an empty string, and the only other script is husky for install-time hooks. Each example is a standalone example.js inside its own directory, with the walkthrough held in the two markdown files beside it.
What retrieval strategies does rag-from-scratch cover?
Basic retrieval with similarity scoring and top-k, query preprocessing with normalization and stopword removal, hybrid search weighting BM25 against embeddings, multi-query retrieval with decomposition, parallel queries and reciprocal rank fusion, and query rewriting in heuristic and LLM form. Re-ranking appears in the pipeline outline without a directory of its own.
Is there a re-ranking example in rag-from-scratch?
Post-retrieval re-ranking is stage seven of the ten-stage pipeline and is named in the summary of what the project teaches, but the visible learning path lists no re-ranking directory. Its strategy folders cover basic retrieval, query preprocessing, hybrid search, multi-query retrieval and query rewriting.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pguso-rag-from-scratch)Star history chart for your README
[](https://hysenlabs.com/projects/pguso-rag-from-scratch)Was this useful?