iconv-lite: the benchmark predates the required Node
Convert character encodings in pure javascript.
At a glance
- What is it?
- iconv-lite converts legacy character encodings in pure JavaScript, with no native code and no runtime dependencies, and it is the encoding layer underneath a handful of well-known server packages. The readme is thorough about byte-order marks and about which malformed inputs are forgiven, and its one performance table was measured on a Node version the package no longer supports.
- Who is it for?
- iconv-lite suits a project that has to read or write legacy encodings in Node or in a browser and does not want a native build step, because it ships the single-byte families, the ten named multibyte encodings and the older Unicode forms with no compilation and no dependencies.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 22, 2026, and from our analysis. They are not legal advice.
Star history
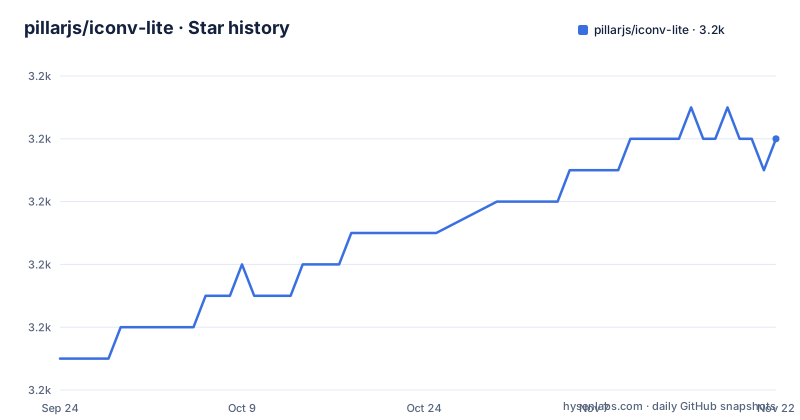
- pillarjs/iconv-lite3,186 ★ · +7
| Repository | 2026-09-24 | 2026-11-22 |
|---|---|---|
| pillarjs/iconv-lite | 3.2k | 3.2k |
7 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The benchmark predates the Node version the package now requires
The one performance figure on the page is a small table comparing this library against the native module, and everything in its header is old. The test is a thousand buffers of 256 kilobytes, run on a MacBook Pro with a 2.6 GHz Core i5, on Node v0.12.0, comparing version 0.4.7 of this library against version 2.1.4 of the other. The feature list above it claims, without qualification, that this library is faster than the native module. The manifest now requires a Node version from the current generation, and the version under test is many majors behind the stable line and behind the release candidate. So the headline number describes a build that cannot run on the runtimes the package supports, on hardware that no longer represents the target, and the page adds only that your results may vary.
Encoding with the endianness-detecting form writes a byte-order mark by default
There are two byte-order-mark behaviours on this page and they are not the same, so the distinction matters. For every ordinary encoding, decoding strips a mark if one is present and encoding adds none unless you ask for it. For the two forms whose whole purpose is to guess endianness, the guess is made by reading a mark and a heuristic based on spaces, and the default is little-endian. What is easy to miss is the other half: for those same two forms, encoding writes a mark by default. So a round trip through one of them produces a buffer that begins with three invisible bytes, where a round trip through the explicit little-endian or big-endian form does not. There is an option to turn it off, and the page names it, but the default is the surprising half.
One of those two forms throws on bad input and the other always forgives it
Read the two sections side by side and the asymmetry is exact. The thirty-two-bit section says decoding is strict per the Unicode Standard: a code unit that is a surrogate code point, one above the highest valid value, or a truncated trailing code unit is replaced with the replacement character, and you can pass a fatal option to throw instead. Encoding also replaces a lone surrogate so the output is always valid. The seven-bit section says the fatal option is not supported, that decoding is always lenient, and that lone surrogates pass through as their raw sixteen-bit code units. So the same malformed input either throws, is silently repaired, or is passed through unchanged, depending on which of the two encodings you chose, and the reason is only given for one of them.
The manifest tracks the candidate while the stable line is behind it
The release list and the manifest do not describe the same line. The newest tags are a candidate and a stable release published ninety-one minutes apart on the same afternoon, with the candidate numbered higher. An earlier candidate from January sits below both. The manifest's version field matches the candidate exactly, so a checkout or an install from the repository gives you the pre-release, while a registry install of the stable line gives you something two minors behind. There is no statement anywhere of which line is intended for production, and the readme's own installation guidance is silent on it. The one unambiguous signal is the runtime floor in the manifest, which is a current Node version and the thing the benchmark on the page was not run against.
The funding field points at a different project's collective
The manifest carries a funding block, and it names a collective that belongs to another project entirely. The funding type is the platform's standard type and the address is the collective for the Express project, not for this library. That is a defensible choice if the maintainers wanted revenue to flow to the wider server ecosystem, and it is also the only funding information a machine reading the manifest will find, because the readme has no donation section at all. The other identity details in the same file are the ones worth checking against the page: the author field names the original author, the repository, bugs and homepage fields all use the organisation the code now lives under, and every link inside the readme still addresses the repository under its previous name.
The readme's own links still address the repository's previous owner
A dozen links inside the readme point at a repository under a personal account that no longer holds the code. The type definition file, the wiki pages, the buffer warning page, the issues that document a Node bug, the test clone command, and the supported-encodings index all use the old path, while the manifest's repository, bugs and homepage fields use the organisation path. The result is a page whose own instructions for running the tests clone from somewhere the code is not. For a contributor this is a thirty-second fix, and for a reader who follows the testing section verbatim it is a dead end, which is a shame because the testing section is otherwise the most useful part of the page: three commands covering the suite, the benchmark and the coverage report. The commands are:
git clone [email protected]:ashtuchkin/iconv-lite.git
cd iconv-lite
npm install
npm test
The published package ships the generated tables and not the generator
The files list in the manifest is four directories long, and what is in them says a lot about how this project is built. The backends directory, the library directory, the encodings directory and the type definitions all ship. The generation directory, the performance directory and the test directory do not. So the charset tables travel with the package and the scripts that produce them do not, which is the right way round for an install. The tree explains where the tables come from: the single-byte ones are generated automatically from the native module, and the multibyte ones from the Unicode consortium's mapping tables and from the WHATWG encoding standard. The encoding support is therefore inherited rather than written, and the acknowledgements on the page name the two upstream projects accordingly.
The coverage check is switched off in the continuous-integration script
The test scripts are four long command lines and they share a shape. The suite runs under a leak checker in every case, which means a test that leaves a global behind fails the run rather than passing quietly. The continuous-integration script and the local coverage script each run mocha twice, once on the default backend and once with a require that switches to the web backend and a name filter that selects only that group, and the second coverage invocation does not clean the first one's data so the two accumulate. What the coverage flag says is the part to notice: the coverage check is explicitly switched off in both scripts, and the coverage tool is only used to produce a report. So a drop in coverage is visible in the report and invisible to the exit status.
Editorial conclusion
iconv-lite suits a project that has to read or write legacy encodings in Node or in a browser and does not want a native build step, because it ships the single-byte families, the ten named multibyte encodings and the older Unicode forms with no compilation and no dependencies. It is a poor fit if your pipeline treats a byte-order mark as corruption, because the two endianness-detecting forms emit one on encode by default, and a poor fit if you need malformed input to fail loudly, because that behaviour is consistent for one of those encodings and deliberately absent for another. Before you adopt it, decide whether lenient or strict decoding is right for your data, and if you rely on the speed claim, measure it yourself rather than reading the table.
Frequently asked questions
what is iconv lite
It is a library for converting character encodings in pure JavaScript, with no native code compilation, working in Node, in the browser and in React Native with one extra polyfill. It provides an encode and decode API with a streaming interface, supports everything Node handles natively plus a set of legacy single-byte, multibyte and older Unicode encodings, and is MIT licensed with no runtime dependencies.
Which encodings does iconv-lite support?
Four groups: everything the runtime handles natively, which includes base64 and hex as well as the usual text forms; extra Unicode encodings including the endianness-detecting forms and the seven-bit forms; the widespread single-byte families, which are generated automatically from another library; and ten named multibyte encodings, which are generated from the Unicode consortium tables and the WHATWG standard.
What does iconv-lite do with a byte-order mark?
For ordinary encodings it strips one on decode unless you pass a false value, and adds none on encode unless you ask. The strip option also accepts a callback, which fires only if a mark was actually present. The two endianness-detecting forms are the exception on encode: both write a mark by default, and both take an option to stop.
Does iconv-lite throw on malformed input?
For the thirty-two-bit form, decoding is strict and replaces an invalid code unit with the replacement character unless you pass a fatal option, which throws instead; encoding also replaces lone surrogates. For the seven-bit form the fatal option is not supported at all, decoding is always lenient, and lone surrogates pass through as their raw code units.
How fast is iconv-lite compared to node-iconv?
The page gives one table, comparing an old version of this library against the native module on a stated laptop, a stated workload and Node v0.12.0, with a note to test on your own hardware. The feature list states plainly that it is faster, without a version. The manifest now requires a current Node version, so the published figure does not describe a supported configuration.
How do I run the iconv-lite test suite?
Three commands are documented. The suite runs under a global leak checker, and the continuous-integration and coverage scripts each run it twice, once on the default backend and once with a require that selects the browser backend. The coverage check is switched off in those scripts, the performance script needs a native syntax escape hatch, and the type check compiles and then inspects the packed tarball.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pillarjs-iconv-lite)Star history chart for your README
[](https://hysenlabs.com/projects/pillarjs-iconv-lite)Was this useful?