Pimcore: open core, four editions, and version numbers that moved in 2026.1
Core Framework for the Open Core Data & Experience Management Platform (PIM, MDM, CDP, DAM, DXP/CMS & Digital Commerce)
At a glance
- What is it?
- Pimcore is a PHP platform for product and content data with a document database, an asset library and a page system, delivered as a core framework plus a long list of separately versioned modules. Its own page is careful about what open core means, and it documents a versioning change that took effect this year.
- Who is it for?
- Pimcore suits an organisation that already has a product or content catalogue and wants one system to serve a website, a shop, an app and a signage screen from the same data. Four things to know before you commit.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly PHP, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
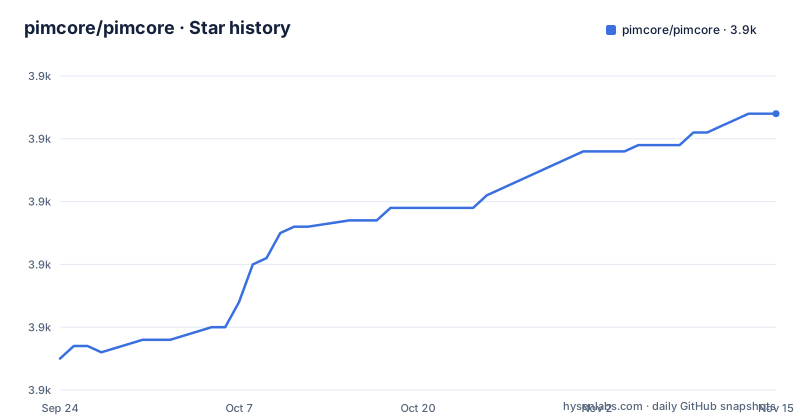
Star history
- pimcore/pimcore3,894 ★ · +39
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| pimcore/pimcore | 3.9k | 3.9k |
39 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It is open core, and the licence name says so
The page uses the phrase open core consistently and never once calls the project open source. The modules are described as licensed under a named licence of the project's own, the description field calls it an open core data and experience management platform, and the repository's own licence metadata reports nothing at all, which is consistent with a licence no automated tool recognises. What the page does give you is the shape of the arrangement. There is a core framework, and there is a modular set of extensions covering product information, master data, assets, customer data, documents and commerce, and those extensions are separately packaged, separately licensed and separately versioned. So the open source part is the framework and the modules, and the commercial part is decided per module per edition. The licence file and a third party licence file are both in the repository root, and a contributor licence agreement sits beside them, so both the inbound and the outbound licensing are non-default.
Four editions decide which modules you get
The page names the editions once and does not enumerate the differences: community, professional, enterprise, and a hosted platform edition. It then says module availability is listed per edition and links a documentation page for that matrix rather than printing it. That single decision point is what makes this open core rather than merely source available. Anyone evaluating the platform has to find that matrix, check whether the modules their use case needs are in the tier they intend to run, and price the remainder. It is a reasonable design, and it is also the reason a technical evaluation of this repository alone can mislead: the framework here is genuinely complete as a document and asset store, and the modules on top of it are where the edition boundary bites. The hosted demo the page offers is the enterprise edition, reached through a request form, which is a reasonable thing to be aware of before trying it.
Since 2026.1 every module carries the platform version number
The platform versions section explains a versioning model that is unusual and recently changed. Each module lives in its own repository and is released independently, which is the ordinary arrangement for a modular platform. A separate package bundles a set of specific module versions that have been tested and verified to work together, and that bundle carries a single version number of its own in a year and dot format. Major platform versions ship once per year, and the documentation and demos are based on those bundles rather than on latest releases. Then the change: starting with the 2026.1 bundle, every module carries the same version number as the platform. So the release trains have been synchronised in their numbering while remaining independent in their cadence, and the consequence is direct: a module version no longer tells you which platform generation it belongs to, and you have to consult the bundle.
The repository you are reading is one piece of a platform spread across many
The project's own description calls this repository the core framework for the platform, and the architecture section confirms that the framework is the layer everything else sits on. The modules listed on the page are eight groups of separately published packages, covering data onboarding and distribution with the graph and REST layer, data import, file export and webhooks; back office productivity tools including a workflow designer; automation including two components with a copilot name; portal and dashboard tooling; advanced data management including a data quality module; personalisation; integrations including single sign-on and translation providers; and an e-commerce framework covering catalogue, pricing, cart, checkout and orders. Adopt the platform and you are adopting a dozen repositories and a bundle package that pins them. The tree reflects that split, with a bundles directory that presumably records which module versions belong together.
Two delivery patterns that the page says can coexist
The architecture is layered so that three interfaces share one core data layer: the administration interface, server-rendered websites, and headless API consumers. The page then splits delivery into two patterns and makes a point about them. In the server-rendered pattern, pages are built and rendered by the platform itself, using the framework's own routing and templating with an inline editing mechanism that lets an editor change content on a rendered page. In the headless pattern, the platform becomes a pure data and content backend with no rendering at all, and any frontend consumes it. The sentence that makes this useful for planning is the last one in the section: both patterns can be used alongside each other in the same project. So a migration can start with a server-rendered site and move a channel to headless without splitting the data, which is the argument for the data-first element model underneath.
Real-time is server-sent events, and one library sits on both sides
Read the technology stack and you get an unusually specific list: two current PHP versions, the framework's components by name, and a separate list for the administration interface with a component library, a state store and a data-fetching layer. Persistence is a relational engine through an abstraction layer, with a filesystem abstraction covering local disk, object storage and other adapters. Search is a choice between two index engines behind one abstraction named as the generic data index. Caching is either a Redis-style store or the framework's own cache. Background work goes through the framework's message bus with a configurable queue backend. And real-time is server-sent events, not a socket. That last detail has a corollary worth noticing: the same real-time library appears in the browser-side list and in the real-time row, so the client and the server are the same project. That is a reasonable choice for one-directional updates from server to browser, and it is a constraint if you expected bidirectional messaging.
The data model is three element types and a class editor
Everything in the platform is organised into three kinds of element that can be linked and related to each other, and the page is careful to say which business use case each one serves. Structured data is held in objects defined by a model you design in a class editor, populated by hand or by API, and the page maps them onto the product, category, customer, order and article cases respectively. Files of any type are assets, previewable inside the platform across a stated two hundred or more formats, with automatic generation of channel-specific renditions, plus metadata and versioning. Pages are documents, built from templates in a specific templating language with inline editable regions, with multilingual and multi-site support, and the document type also covers emails, newsletters and web-to-print. That last point is the one that surprises people: the content model is not only for pages, so the same editorial system covers transactional and campaign content as well as the site.
Four static analysis configs, including one against the lowest dependency versions
The repository root is where the engineering practice shows. There are four separate static analysis configuration files, and two of them are unusual enough to be worth naming. One is a baseline, which is the standard mechanism for recording the violations a project has decided to live with rather than fixing, so the analysis is enforced going forward while a known backlog is grandfathered in. The other runs the analysis against the lowest supported dependency versions rather than the newest, which is a deliberate way to catch the class of bug where code compiles only because a newer dependency fixed a type or added a function. There is also a code style configuration for the language, a markdown lint configuration, an editor settings file, a test framework configuration, and stub definitions. For a project with this many contributors that is an unusually careful baseline, and the lowest-versions pass in particular is the one most projects skip.
Editorial conclusion
Pimcore suits an organisation that already has a product or content catalogue and wants one system to serve a website, a shop, an app and a signage screen from the same data. Four things to know before you commit. The licence is a custom open core one, not a standard permissive licence, and availability of modules varies by edition, so the module you need may not be in the community tier. This repository is the core framework only; the modules live in their own repositories, so you are adopting an ecosystem rather than a package. From the 2026.1 platform version every module carries the platform's own version number, which means a module release no longer tells you which platform it targets. And local development assumes Docker, including membership of the group that lets you run it and change file ownership.
Frequently asked questions
what is pimcore
An open core platform for product experience management, described as one platform for any data, any channel, any process. It provides a core framework plus modular extensions covering product information, master data, asset management, customer data, documents and commerce. Data is stored independently of the channel and delivered to websites, commerce systems, mobile apps, print, digital signage or headless consumers over REST and GraphQL, and a separate administration interface named Studio covers the whole platform.
What is Pimcore used for?
Storing and serving product and content data to many outputs. All data is organised into three element types: structured objects defined by a model you design, assets of any file type with previews, metadata and versioning, and documents built from templates with inline editing for pages, emails, newsletters and web-to-print. The platform also covers customer data, orders, catalogue, pricing, cart and checkout.
is pimcore open source
It is described as open core, not as open source. The modules are licensed under a named licence of the project's own, and the platform is split into four editions with module availability varying by edition, so what you can run depends on the tier. The repository's own licence metadata reports nothing. Both a licence file and a third party licence file are in the repository root, and there is also a contributor licence agreement for inbound changes.
is pimcore a cms
It includes one. Documents are one of the three core element types and build pages with templates and inline editable regions, with multilingual and multi-site support, plus emails, newsletters and web-to-print. What the page emphasises is that the same content can instead be served headless over REST and GraphQL, and that both delivery patterns can be used in the same project.
how to install pimcore
For local development the current branch uses Docker, and the page says no local PHP or Composer installation is required. You need Docker and Docker Compose installed, and your user must be allowed both to run Docker commands and to change file permissions, which is the membership requirement that most often blocks a first attempt. The page also offers a hosted demo of the enterprise edition through a request form, so you can look before installing anything.
what is pimcore studio
The unified administration interface for the whole platform, described as covering the entire system. The page lists its stack: a component library, a state store, a data-fetching layer, the real-time library, and a newer bundler. It is one of three interfaces that sit on the same core data layer as server-rendered sites and headless API consumers, and its functionality is split across separately published modules covering dashboards, a portal engine and a statistics explorer.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pimcore-pimcore)Star history chart for your README
[](https://hysenlabs.com/projects/pimcore-pimcore)Was this useful?