Pinecone's v10 makes the index declare its own shape
Official Python SDK for the Pinecone vector database
At a glance
- What is it?
- Version 10 of the Pinecone Python SDK moves index creation from `spec=` and `dimension=` to `schema=` and `deployment=`, which in practice means a schema-declared index is read and written as JSON documents rather than as vectors. The repository also carries a Rust crate built by maturin, and a test suite whose house rule is that it must not dirty the working tree.
- Who is it for?
- Use this SDK if you are on Pinecone and want typed records rather than a raw vector call, since the schema-declared index path gives you named JSON fields and one handle for both writing and searching. Expect to touch code when you move to v10, because the create and configure calls changed argument names and the data-plane method you get depends on how the index was created, so an old-style index will not answer the same calls a new one does.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 13 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
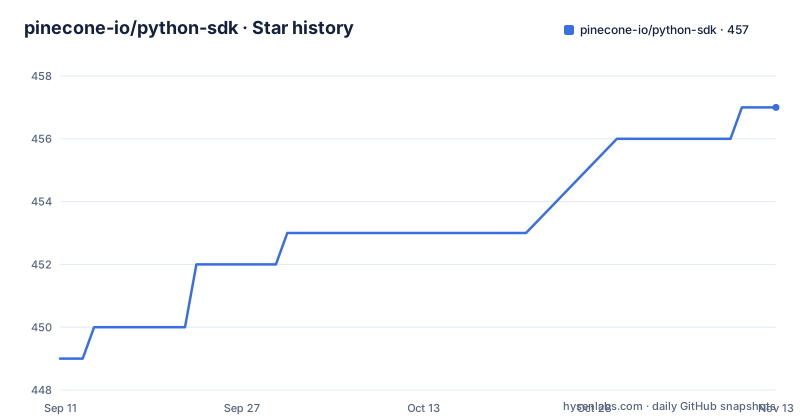
- pinecone-io/python-sdk457 ★ · +8
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| pinecone-io/python-sdk | 449 | 457 |
8 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A schema declaration turns the index into a document index
The v10 change is the reason this release matters. `create` and `configure` moved from `spec=` and `dimension=` to `schema=` and `deployment=`, so existing code does not simply keep working, and a field by field migration guide is published for the mapping. The shape of a schema index is what changes behaviour rather than just syntax. An index that declares its fields is a document index: you read and write it through `index.documents`, and each record is a JSON document whose field names you chose yourself. The creation call names the vector field inside the schema with its type, dimension and metric, and passes the deployment separately:
from pinecone import DenseVectorQuery, Pinecone

pc = Pinecone(api_key="your-api-key")
pc.indexes.create(
    name="movie-recommendations",
    schema={"fields": {"embedding": {"type": "dense_vector", "dimension": 3, "metric": "cosine"}}},
    deployment={"deployment_type": "managed", "cloud": "aws", "region": "us-east-1"},
)
index = pc.index("movie-recommendations")
The API key can be passed explicitly or omitted, in which case the client reads `PINECONE_API_KEY`. Note also that the create call blocks until the index is ready, and that `pc.index(...)` returns the data plane handle you work through afterwards. The `deployment` object is a separate concern from the schema and worth reading as its own decision, because it carries three keys that describe where the index physically lives: a deployment type, here `managed`, a cloud, here `aws`, and a region, here `us-east-1`. So one call declares both the logical shape of your records and the infrastructure they sit on, which is why the v10 rename is not just a tidier spelling. Anyone moving from 9.x is pointed at a field by field migration guide rather than left to infer the mapping from the signature.
Which methods you get depends on how the index was created
There are three data plane shapes in this SDK, and picking the wrong one produces attribute errors rather than empty results. A schema index, the one above, exposes `index.documents` for both reading and writing. An index created with the deprecated top level vector arguments instead answers on `index.upsert` and `index.query`, which is the older vector style still present for compatibility. And an index created through `pc.indexes.create_for_model(...)` takes a different path again: it embeds text server-side, and it answers on `index.upsert_records` and `index.search`. The consequence for you is that the creation call is not a cosmetic detail, it determines your method names for the life of the index. A schema index you created months ago and an integrated one you created today are not interchangeable just because both live in the same project. The quickstart and the rest of the documentation are where the full comparison sits, and this README deliberately stops at naming the three rather than reproducing the table. Two details of the document path are worth pulling out because they apply across all three flavours. Every upserted document needs an `_id`, and the sample comment states that before naming what the remaining keys are, so id assignment is your responsibility rather than the server's. And the async example shows a `namespace` on the search call, which means one index can hold several logically separate collections without you having to encode that into your field names. Get the index flavour right first and both of those behave the way the docs say; get it wrong and you are debugging method names.
Upserts apply asynchronously, so the next search can come up short
The single most common surprise in this SDK is a correctness surprise rather than an error. Upserts apply asynchronously, which means a document you have just written may not be visible to the next search. Nothing raises, no request fails, and the response to your write looks like success; the record simply is not queryable yet. That turns a class of bug from an exception into a flaky test, because the failure depends on timing rather than on input. Any code that writes and immediately verifies has to account for it, whether by tolerating a short absence, by searching on a field you know is eventually consistent, or by separating the write from the read the way a batch pipeline naturally would. The same property cuts the other way for deletes and updates, so treat the index as eventually consistent around writes rather than assuming read your writes. The short start example in the README makes the same point in a single line, immediately after the upsert snippet, rather than burying it in a caveats section.
The async client makes index() a coroutine and the handle a context manager
Async support is a parallel client rather than a flag, and it uses a separate class, `AsyncPinecone`. Two things change shape. `index()` becomes a coroutine, so you await it to get the handle, and the handle is itself a context manager, so the session closes when the block ends rather than when you remember to:
from pinecone import AsyncPinecone, DenseVectorQuery

async def main():
    async with AsyncPinecone(api_key="your-api-key") as pc:
        index = await pc.index("movie-recommendations")
        async with index:
            results = await index.documents.search(
                namespace="movies-en",
                top_k=5,
                score_by=[DenseVectorQuery(field="embedding", values=[0.1, 0.2, 0.3])],
                include_fields=["title"],
            )
The search call itself shows three arguments worth knowing about beyond the async wrapping. A `namespace` scopes the query, which is how one index holds several logical collections. `score_by` carries the vector, in this case a `DenseVectorQuery` naming the field and its values, so you are explicit about which field is being compared. And `include_fields` names the document fields to return, which matters because a schema index can hold many fields and you usually want a subset. The constructor takes the same configuration options as the sync client. The example in the README is cut off at the point where it would run the coroutine with `asyncio.run`, so the entry point itself is the one thing you supply from your own side rather than copying, which is a reasonable place to stop anyway since how you schedule the loop is your application's decision. The results object exposes `matches`, and each match carries an `id` and a `score`, so the returned document fields are whatever you asked for in `include_fields` and nothing else.
Four constructor options and three environment variables
Configuration is deliberately small and split between constructor arguments and environment variables. The API key is the first fork: pass it directly to `Pinecone(api_key=...)` or omit it and let the client read `PINECONE_API_KEY`. A specific control plane host is the second, set with `host=` and shown in the docs as `https://api.pinecone.io`, which is what you need for a non default environment. Timeouts are the third, given in seconds, so `timeout=30` caps a request rather than leaving the default in place. Debug logging is the fourth knob and the only one that is environment only, switched on with `PINECONE_DEBUG`. Beyond those, the example environment file shows two more that matter for SDK development rather than application use. `PINECONE_API_KEY_CI_TESTING` holds a second key used by the maintenance and cleanup helpers in `scripts/repl.py`, and `PINECONE_ADDITIONAL_HEADERS` attaches extra headers to every request, which must be written as a JSON string so it survives being round tripped through the environment.
The unit suite is expected to leave the working tree clean
The development section sets up with uv, matching what CI does, and the dev dependency group is installed with a single command:
uv sync --group devThen four commands cover the checks:
uv run pytest tests/unit/ -x -v      # tests
uv run mypy --strict pinecone/       # type checking
uv run ruff check --fix              # linting
uv run ruff format                   # formatting
The strict mypy mode is worth noting, because it is not the default and it means the package carries type annotations throughout its public surface. The rule that tells you what kind of codebase this is comes next: the unit suite must leave the working tree clean, so `git status` is expected to report no changes after a bare `uv run pytest tests/unit`. If a test genuinely needs a file on disk, the guidance is to use `tmp_path` or `tmp_path_factory` rather than write anywhere in the checkout. That is a small rule with a large effect, since it makes an accidental write during a test run visible immediately instead of surviving until someone commits it.
Live suites cost money and gate the releases that touch retry logic
Some suites are opt-in because they hit a real backend and cost money, and the gating is explicit. The live retry and throttle smoke tests live in `tests/integration/test_retry_smoke.py` and need both an API key and a second switch, `PINECONE_RETRY_SMOKE=1`. The instruction is not merely to run them but to run them before any release that touches retry logic, HTTP transport, the AIMD adaptive concurrency limiter, or the batch upsert path. That list is effectively a map of where this SDK can break quietly: a retry change that passes every unit test can still misbehave against a rate limiter, and an adaptive concurrency limiter is precisely the kind of component that unit tests with fake transports will not exercise. Each module documents its own gate and its own cost, so the budget for running them is visible before you start rather than discovered afterwards. Everything else in the test tree is meant to run offline, which is why the clean working tree rule and the live suite separation fit together. The rest of the tree explains the rest. Alongside the package itself sit `docs/`, `scripts/`, `tests/` split into unit and integration, and an `AGENTS.md` at the root, plus a committed `uv.lock` so the dependency resolution is reproducible rather than floating. Release cadence has been brisk through the major line: 9.0.1 in May 2026, 9.1.0 in June, and 10.0.0 on 3 September, with the last push to main on 19 September 2026. A major version every few months on a client library means you should expect to read the migration notes rather than assume a patch bump, which is why the v10 argument rename is called out at the very top of the README instead of being left to a changelog.
A Rust crate ships inside the Python package, and httpx is capped on purpose
The build backend is maturin rather than setuptools, which is the giveaway that this is not a pure Python distribution. The Cargo manifest at the top level declares a workspace with a single member, `rust`, and pins resolver version 2, and the tree carries `rust/`, `Cargo.toml`, `Cargo.lock` and an `internal/` directory next to the `pinecone/` package. The metadata declares the package as version 10.0.0, requiring Python 3.10 or newer and classifying itself as Production/Stable and OS Independent, with classifiers for Python 3.10 through 3.14. The dependency list has one entry worth reading closely: httpx is required as `httpx[http2]>=0.27,<1.0`, and the upper bound exists because the 1.0 pre-release line drops symbols the SDK relies on, with `httpx.BaseTransport` named as one. Without the cap, a `pip install --pre pinecone` resolves to a broken pre-release. Serialisation goes through msgspec and orjson, both with upper bounds, and aiofiles is declared explicitly rather than left as a transitive accident, which is the same discipline the code comment explains and a test under the tooling tests enforces.
Editorial conclusion
Use this SDK if you are on Pinecone and want typed records rather than a raw vector call, since the schema-declared index path gives you named JSON fields and one handle for both writing and searching. Expect to touch code when you move to v10, because the create and configure calls changed argument names and the data-plane method you get depends on how the index was created, so an old-style index will not answer the same calls a new one does. Three things to check before you start. Which index flavour you are on, because documents, the deprecated top-level vector path and the server-side embedding path expose different methods. Whether your write-then-read code tolerates asynchronous upserts, since a document may not be searchable immediately. And if you are working on the SDK itself, that the unit suite is expected to leave `git status` clean and that the live retry and throttle smoke tests cost real money and need an explicit opt-in before a release that touches retry or transport code.
Frequently asked questions
How do I install the Pinecone Python SDK?
Run `pip install pinecone`. The package requires Python 3.10 or newer, is licensed Apache-2.0, and ships with classifiers for Python 3.10 through 3.14. There is also a console usage path for development, where `uv sync --group dev` installs the dev dependency group the same way CI does.
What changed in version 10 of the Pinecone Python SDK?
The create and configure calls moved from spec= and dimension= to schema= and deployment=. An index created with a schema is a document index that you read and write through index.documents, where each record is a JSON document with field names you chose. A field by field migration guide is published for the old argument names.
Why do my Pinecone upserts not appear in the next search?
Upserts apply asynchronously, so a document may not be visible to the next search immediately. No request fails and no error is raised; the record simply is not queryable yet. Code that writes and immediately verifies has to tolerate that window rather than assume read your writes.
How do I authenticate and configure the Pinecone client?
Pass api_key= to the Pinecone constructor or omit it and set PINECONE_API_KEY. Constructor options also cover a specific control plane host with host= and a request timeout in seconds with timeout=, while debug logging is switched on with the PINECONE_DEBUG environment variable. The async AsyncPinecone client takes the same options.
How do I run the Pinecone SDK tests?
Install the dev group with `uv sync --group dev`, then run `uv run pytest tests/unit/ -x -v` alongside strict type checking and ruff. The unit suite is expected to leave the working tree clean, so use tmp_path or tmp_path_factory if a test needs a file. The live retry and throttle smoke tests are opt-in and cost money.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pinecone-io-python-sdk)Star history chart for your README
[](https://hysenlabs.com/projects/pinecone-io-python-sdk)Was this useful?