Scalene: a Python profiler that separates run from view, and where its AI suggestions stop
Scalene: a high-performance, high-precision CPU, GPU, and memory profiler for Python with AI-powered optimization proposals
At a glance
- What is it?
- Scalene is a CPU, GPU and memory profiler for Python from Emery Berger, Sam Stern and Juan Altmayer Pizzorno, with a browser interface and optional AI-generated optimization proposals. This review covers how its run and view commands split the work, what each profiling switch costs you and which platform constraints apply.
- Who is it for?
- Scalene fits Python developers who want line-level CPU, GPU and memory numbers in one tool and are happy to read them in a local browser page. It is a weaker choice if you need a quick answer without a native build step on an unusual platform, or if you expect the AI suggestions to be correct without review.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
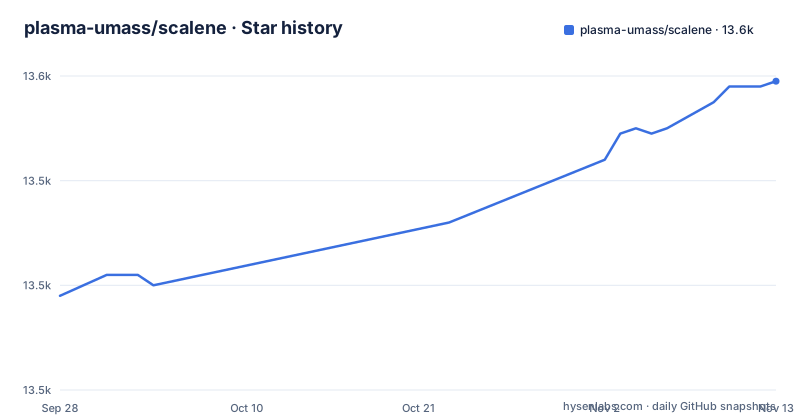
- plasma-umass/scalene13,559 ★ · +41
| Repository | 2026-09-28 | 2026-11-13 |
|---|---|---|
| plasma-umass/scalene | 13.5k | 13.6k |
41 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Profiling and viewing are two separate commands that share a profile file
Scalene's command line is verb based. There are two commands: run profiles a program, and view displays the result. The profile is written to a file called scalene-profile.json, and view reads that file back, so you can profile once and look at the data several ways.
scalene run your_prog.py
python3 -m scalene run your_prog.py
scalene view
scalene view --cli
scalene view --html
scalene view --standalone
The two run forms are equivalent. scalene view with no flag opens the profile in a browser, scalene view --cli prints it in the terminal, scalene view --html saves scalene-profile.html, and scalene view --standalone saves a self-contained HTML file. The standalone form is the one to attach to a bug report or send to a colleague, because it does not depend on anything else being installed on the receiving end.
The consequence of the split is that a long profiling run does not have to be repeated to change how you look at it. The cost is an extra step for anyone used to older Scalene tutorials that put everything into one invocation. If a blog post shows a different command shape, trust scalene --help and the README command list over the post.
The faster profiling modes work by turning measurements off
Scalene measures CPU, GPU and memory, and the options let you choose which of these you pay for. The README marks the CPU-only switch as the faster one.
scalene run --cpu-only your_prog.pyThe YAML configuration file makes the same choice explicit with three mutually exclusive lines, and the comment above them tells you to use only one:
cpu-only: true
# gpu: true
# memory: true
The practical reading is that cpu-only gives you a profile with no memory or GPU columns in exchange for speed. If you suspect a memory problem, a CPU-only run cannot show it, and you have to rerun with the memory mode before you can say anything. The README claims Scalene runs orders of magnitude faster than many other profilers while delivering more detail, but that is the authors' statement. The repository has a benchmarks directory, and you should run your own program under both modes before deciding which one your workflow can afford.
The YAML file is loaded with -c or --config, and command line arguments override whatever the file says:
scalene run -c scalene.yaml your_prog.pyPath filters decide whether your own code or the whole stack is measured
A profile that includes every installed library is hard to read. The example scalene.yaml shows the filters that control scope.
outfile: my-profile.json
profile-only: "mypackage,mymodule"
profile-exclude: "tests,venv"
profile-all: false
cpu-percent-threshold: 1
outfile renames the JSON that run writes. profile-only restricts reporting to the listed paths, profile-exclude removes paths such as tests and a virtual environment, and profile-all set to false means only the target program is profiled and not all code. cpu-percent-threshold sets the minimum CPU percentage a line needs before it is reported, with a default of 1.
The consequence is that the defaults hide small costs. A line that takes less than the threshold share of CPU will not appear, so a death by a thousand cuts pattern, where many lines each cost a little, can look clean. Lower the threshold if the report does not add up to the wall-clock time you saw. Equally, turning profile-all on pulls in library code and makes the output longer, which helps when the slow work is happening inside a dependency you did not write. The sampling rate option is also present in the file, but the README text for it is cut off, so check the file in the repository for its default.
Code can start and stop the profiler itself, or mark single functions
You do not have to profile a whole program. Scalene offers three ways to narrow the window from inside the code. The first is explicit start and stop calls, used after launching the program through the scalene command:
from scalene import scalene_profiler

# Turn profiling on
scalene_profiler.start()

# your code

# Turn profiling off
scalene_profiler.stop()
The second is a context manager:
from scalene.scalene_profiler import enable_profiling

with enable_profiling():
    # do something
The third is the @profile decorator, which is applied to the functions you care about. The README is firm on one detail, which is that you must not import profile:
# do not import profile!

@profile
def slow_function():
    import time
    time.sleep(3)
The decorator is injected by Scalene at run time, so running the same file under plain python will fail on the undefined name. That makes decorated code awkward to keep in a module that also runs in production. The programmatic calls have the same dependency: the program must be launched with scalene for start and stop to have an effect, as the README says to invoke using scalene as above and then use them.
AI optimization suggestions need provider credentials and a human reviewer
Scalene's distinguishing feature is that it can ask an AI model for a proposed rewrite of a slow line. The README lists Amazon Bedrock, Microsoft Azure, OpenAI and local models via Ollama as supported providers. In the browser interface you choose a provider and, if needed, enter credentials in the box under AI Optimization Options.
scalene view --api-keys-from-envThat flag prefills the credentials from environment variables such as OPENAI_API_KEY, ANTHROPIC_API_KEY or AWS_ACCESS_KEY_ID. The README states that the keys are passed only to your local browser session and are never written into the HTML file. This matters for the --html and --standalone outputs, because it means a profile you share does not carry your key with it. The v2.4.0 release title lists safer API keys among its changes.
Once a provider is set, the lightning bolt beside a line, or the explosion icon for a whole region, generates a proposal, and clicking a proposal copies it to the clipboard. You can click repeatedly and get different suggestions each time. The README itself says your mileage may vary, so treat each output as a draft to benchmark. Choosing Ollama is the way to avoid sending code to a hosted service, but the README does not say how the quality of local models compares.
A compiled extension and a Python version exclusion shape installation
Installation is a single pip or conda command:
python3 -m pip install -U scaleneconda install -c conda-forge scaleneUnder that sits a native build. setup.py imports setuptools Extension, and on macOS it raises MACOSX_DEPLOYMENT_TARGET to 10.9 when the detected value is lower, because the comment says gcc or clang need that target to find libstdc++ headers. It also probes the compiler for x86_64, arm64 and arm64e support and adds the architectures that compile. On Windows it passes /std:c++14. When a prebuilt wheel exists none of this runs, but if pip falls back to a source build you need a working C++ compiler.
The package metadata says requires-python is >=3.8 with 3.11.0 explicitly excluded, and the classifiers go up to Python 3.14 on Linux, macOS and Windows. The nvidia-ml-py dependency is declared for every platform except Darwin, which is the reason GPU profiling in the README is tied to NVIDIA hardware on Linux and Windows and not to Apple machines. The v2.4.0 release title mentions free-threaded wheels and an M4 fix, so Apple silicon and free-threaded builds were both active concerns in the latest release.
The release record is recent, and the web interface runs without a network
The latest tagged release is v2.4.0 on 2026-10-23, titled free-threaded wheels, M4 fix, safer API keys, and formal verification. Before it came v2.3.0 on 2026-05-12 with new visualizations, accuracy improvements and bug fixes, and v2.2.1 on 2026-03-22. The last push to the master branch was on 2026-11-01, and the repository is not archived. The license is Apache-2.0. The repository includes a formal directory, matching the formal verification mention, plus Scalene-Agents.md, Scalene-Debugging.md and Scalene-GUI.md for deeper reading.
The web interface runs locally. After profiling, Scalene opens a tab in your browser, all processing is done on your machine, and the README says the GUI works fully offline. You hover over bars to see CPU and memory breakdowns and click underlined column headers to sort. The only part that needs a network is the optional AI provider call.
In VS Code, the extension adds a command called Scalene: AI-powered profiling in the Command Palette. The README attaches a condition: your code has to run for at least a second before a profile appears in the webview, so very short scripts will show nothing useful there.
Editorial conclusion
Scalene fits Python developers who want line-level CPU, GPU and memory numbers in one tool and are happy to read them in a local browser page. It is a weaker choice if you need a quick answer without a native build step on an unusual platform, or if you expect the AI suggestions to be correct without review. Before relying on it, run scalene run --cpu-only on a real script and compare the result with a full profile of the same program.
Frequently asked questions
How to use Scalene to profile a Python program?
Install it with python3 -m pip install -U scalene, run scalene run your_prog.py, then open the result with scalene view. The profile is saved to scalene-profile.json.
How to use Scalene from the command line or VS Code?
On the command line, scalene run profiles a program and scalene view displays it. In VS Code, install the Scalene extension and choose Scalene: AI-powered profiling from the Command Palette.
What is Scalene?
Scalene is a CPU, GPU and memory profiler for Python that can also ask AI providers for proposed optimizations. It is licensed under Apache-2.0.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/plasma-umass-scalene)Star history chart for your README
[](https://hysenlabs.com/projects/plasma-umass-scalene)Was this useful?