N.E.K.O's Docker upgrade silently produces an empty data directory, and the old README mounted a path the service never wrote to
A catgirl who lives with you in real time - reaching out first, sharing your media, and actually getting things done, powered by an embodied emotional engine.🐱❤一只会主动找你玩的 AI 猫娘。
At a glance
- What is it?
- N.E.K.O is an open-source AI companion platform with realtime voice and vision, a five-part memory system, five avatar forms and a plugin marketplace, shipped as a desktop package or a container. The most valuable thing in its Chinese-language README is not a feature list but a migration warning: pulling the new image starts a container that looks healthy while your personality, memory, plugins and models are all gone.
- Who is it for?
- N.E.K.O fits someone who wants a locally-run companion with persistent memory across desktop and mobile, and who will read a migration document before pulling an image. If you deployed with the earlier instructions, treat the upgrade procedure as mandatory rather than optional, because your application data may exist only inside the container you are about to destroy, and export it first.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
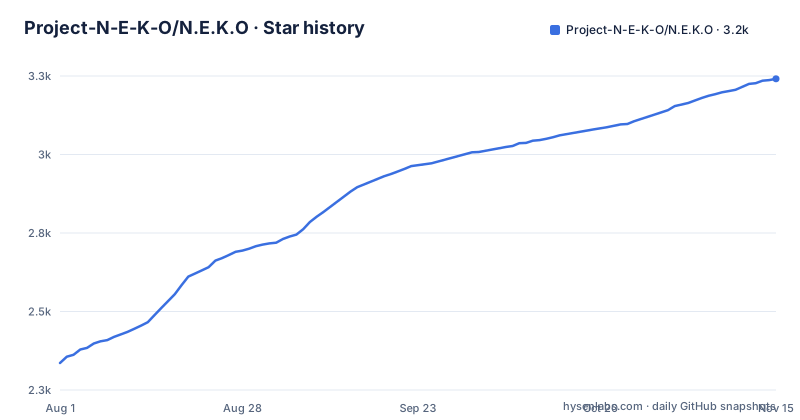
Star history
- Project-N-E-K-O/N.E.K.O3,241 ★ · +905
| Repository | 2026-08-01 | 2026-11-15 |
|---|---|---|
| Project-N-E-K-O/N.E.K.O | 2.3k | 3.2k |
905 Stars in the last 106 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Pulling the new image leaves you with an empty data directory and no error
The container deployment changed its mounts, and the file devotes a section to what that does to existing installations. The old layout mounted two directories, one for data and one for certificates. The new layout merges them into one. Starting the new image without migrating first gives you a fresh, empty data directory, and the failure is silent in the most literal sense: the container starts normally, the application key is regenerated from environment variables, everything appears to work, and the persona, the memory store, the installed plugins and the models are simply not there. The old data is not deleted, it is just no longer mounted into the container, so the recovery path is to move it once. That warning is the most consequential paragraph in the repository and it is filed under deployment rather than under a heading anyone would look for.
The previous instructions pointed at a directory the service never wrote to
The migration section explains why this happened, and the explanation indicts the earlier documentation. If you followed the previous version of the README, your application data may exist only in the container's writable layer, because those instructions mounted the data directory at a path under a root-owned documents folder and the service never wrote there. That means for those users the host directory was never receiving the real data at all. It is also why the export step has to happen before anything else, and why the migration tells you to decide based on what the container actually has mounted rather than on whether the host directory contains files: a host directory may hold files you put there yourself while the genuine data is still only inside the container. The document states plainly that the first of the later steps destroys the container, and that for anyone who followed the old instructions that container holds the only copy.
The merge step is content-wise, and the reason is a nesting trap
Step four folds the old host directory into the new one, and the file is emphatic that this must be a merge by content rather than a move, because moving a directory onto an existing one nests it a level deeper. The container may already have created a directory of the same name and a fresh self-signed certificate, and where a filename exists in both places the old data wins. There is then a second-order warning that only matters to the old-instruction users: if the export step already pulled the real data out of the container, the old host directory is an empty shell that the service never wrote to, and using it to overwrite the freshly exported data would undo the rescue. Two smaller facts close the section. The container's application user is fixed at a numeric id matching the first ordinary user on most distributions, so ownership usually needs no adjustment and backups need no elevation, and the logs mount is unchanged and needs nothing.
The documented image is pulled through a third-party registry proxy
The compose file is short and the notable line is the image reference, which points at a proxy domain in front of the project's own registry namespace rather than at the registry itself:
version: '3.8'
services:
  neko-main:
    image: docker.gh-proxy.org/ghcr.io/project-n-e-k-o/n.e.k.o:latest
    container_name: neko
    restart: unless-stopped
    ports:
      - "48911:80"   # HTTP 访问端口
      - "48912:443"  # HTTPS 访问端口
    volumes:
      - ./neko-home:/home/neko
      - ./logs:/app/logs
The same reference appears in the imperative variant, so both documented install paths route their pulls through that domain. The rest of the configuration is conventional: a container name, a restart policy, two published ports mapping a host port above 48000 onto the standard HTTP and HTTPS container ports, two bind mounts for the home directory and the logs, and a user-defined bridge network that the imperative variant creates first while tolerating a failure. The generated directory layout is documented as a home directory holding configuration, data and certificates, a logs directory, and the compose file itself. The file also notes that macOS users of the desktop package have to clear the system quarantine attribute by hand before the application will open.
Three dependencies carry a written explanation of why they are pinned that way
The manifest is annotated in a way most projects are not, and three comments are worth reading in full. One dependency is pinned to an exact release because the project is read-only against a streaming platform's two APIs and the upstream library version it uses does not expose a device-authorisation flow that needs no client secret, so that flow stays implemented in this repository instead. A YAML library is declared directly rather than being inherited transitively from an unrelated SDK, specifically so that a change upstream cannot silently break strategy parsing in the packaged build. A noise-reduction library is excluded on Intel Macs, and the reason is specific: its wheel is tagged for both architectures but carries only one architecture's shared library, there is no source distribution to compile from, and installing it would bundle the wrong slice into a build that a distribution architecture check would reject, while its only consumer degrades cleanly when the module is absent.
One Python minor and a ceiling on the build backend
The project metadata pins the interpreter to a single minor version with an equality requirement rather than a floor, which is a stricter choice than most applications make and simplifies what the compiled extensions and platform packages have to support. The build requires two things: the declared build backend and a setuptools release below a fixed ceiling, so a new setuptools will not be picked up silently. The dependency list below that mixes styles on purpose, with exact pins on the audio and numeric stack and the platform SDKs, compatible-release constraints on the web framework and several model providers, and plain lower bounds elsewhere. Platform-conditional entries cover macOS and Windows, and one dependency is vendored as a local wheel referenced by relative path rather than pulled from an index.
The requirements file is a generated lock with a backtrace under every line
A committed requirements file carries a header naming the exact command that produced it, and the command is the interesting part: it exports from the lock file, with locked resolution, without hashes and without development extras. Below that, the editable install of the project itself comes first and the vendored local wheel second, and then every transitive dependency is listed at an exact version. Each entry is followed by a comment naming which direct requirement pulled it in, and those backtraces are what make the file useful rather than merely long: you can see at a glance that the HTTP client and its core come from the model providers, that the async HTTP stack arrives through four different routes at once, and that the scheduling library comes in only through the video-platform SDK. At least one entry's backtrace is empty, which is either a direct dependency or a gap in the export.
A store page as the project homepage and a nightly tag beside semantic versions
The repository's homepage field points at a store listing rather than at a documentation site, which tells you where the audience is expected to arrive from. The release history matches: one tag is literally named for a nightly build and carries a date in its title, sitting beside two semantic versions whose titles are written as sentences rather than changelogs. The tree confirms the direction. A Steamworks directory and a store application identifier file sit at the root, alongside three separate subsystems for the agent's reasoning, its memory and its knowledge base, a frontend with both a shell script and a batch file to build it, and a vendored wheel directory. The README advertises translations in English, Japanese and Russian while the default file itself is written in Chinese, and the metadata names that default file with an upper-case extension, which is a distinction that matters on a case-sensitive filesystem. The roadmap describes a separate game repository with a downloadable demo and a planned network where the characters hold their own state and post to a simulated social feed.
Editorial conclusion
N.E.K.O fits someone who wants a locally-run companion with persistent memory across desktop and mobile, and who will read a migration document before pulling an image. If you deployed with the earlier instructions, treat the upgrade procedure as mandatory rather than optional, because your application data may exist only inside the container you are about to destroy, and export it first. Check the architecture-conditional dependency decisions before building on Intel Macs, and expect to be pinned to one Python minor version with a ceiling on the build backend's setuptools.
Frequently asked questions
What is N.E.K.O?
An open-source AI companion platform, named as an acronym for a networked emotional knowing organism, offering realtime voice and vision, a five-part memory system covering working, recent, factual, reflective and personality memory, five avatar forms, plugin execution and a marketplace. The project says it is not a task automation tool and not a roleplay frontend.
What happens when I upgrade the N.E.K.O Docker image?
The mount layout changed from two directories to one, so starting the new image without migrating gives an empty data directory. The container starts, the application key regenerates from environment variables and everything looks normal, but the persona, memory, plugins and models are absent. Old data is not deleted, only unmounted.
Why do some N.E.K.O users have to export their data before upgrading?
Because the earlier instructions mounted the data directory at a path the service never wrote to, so for those installations the application data existed only in the container's writable layer. Destroying the container to upgrade would therefore destroy the only copy, which is why the migration exports first and judges by what the container actually mounts.
Which Python version does N.E.K.O require?
One specific minor version, pinned with an equality requirement rather than a lower bound. The build additionally requires the declared backend plus a setuptools release below a fixed ceiling.
Does N.E.K.O run without cloud services?
The core is described as running locally under Apache 2.0 with data kept on your own machine, and the feature table says free models are available out of the box. It also lists support for fourteen or more model providers, and says the application key is regenerated from environment variables.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/project-n-e-k-o-n-e-k-o)Star history chart for your README
[](https://hysenlabs.com/projects/project-n-e-k-o-n-e-k-o)Was this useful?