BullshitBench: the leaderboard and the chart report two different rates for one model
BullshitBench measures whether AI models challenge nonsensical prompts instead of confidently answering them, created by Peter Gostev.
At a glance
- What is it?
- A benchmark for whether models push back on nonsensical prompts, scored by a panel of three judges and published as two suites of responses. The interesting part is the arithmetic: the headline score removes candidate refusals from its denominator while errors stay in, and the chart can be told to show a second, different rate.
- Who is it for?
- Read this if you want to know whether a model argues back or agrees with a broken premise, and read the denominator before you read the score. Two checks decide how much a number here means.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
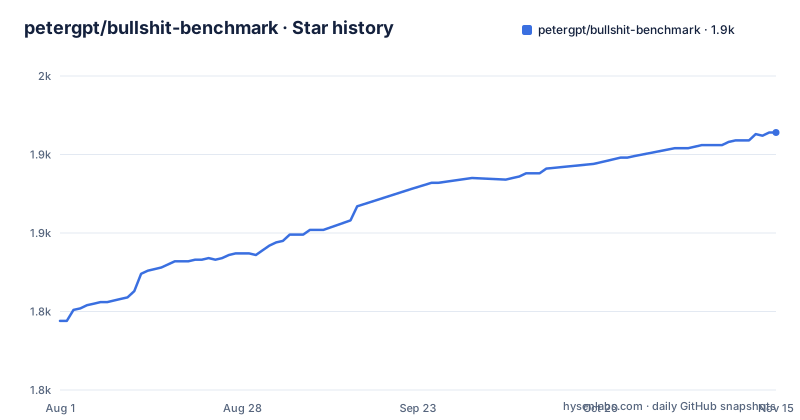
- petergpt/bullshit-benchmark1,914 ★ · +120
| Repository | 2026-08-01 | 2026-11-15 |
|---|---|---|
| petergpt/bullshit-benchmark | 1.8k | 1.9k |
120 Stars in the last 106 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The score divides by attempts minus refusals, and errors stay in
The headline number is written out as a formula: clear answers divided by attempts minus candidate refusals. Two properties of that denominator matter more than the numerator. Errors remain in it, so a model that produces garbage on some attempts is not rewarded for them, and candidate refusals are taken out, so declining to answer does not count against a model. That is a defensible choice, because refusing nonsense is arguably correct behaviour, but it means the score answers a narrower question than pushback rate does: it measures how often a model that engaged went all the way, with the refusals removed from view. Three categories sit underneath the average: clear pushback rejects the broken premise, partial challenge flags problems but still engages, and accepted nonsense treats the premise as valid.
The chart can drop refusals, the published CSV cannot
The same underlying results are available at two rates, and the interface lets you switch between them. Bars include refusals by default, and ticking Exclude refusals removes them from the bars instead. Model detail pages and CSV exports carry both rates. Canonical leaderboard CSVs, the ones a third party would cite, retain the all-attempt rate. The trend view handles the discrepancy explicitly: in the lab trends, which follow each lab's best model at each release date, dotted lines show the all-attempt rate of the same model wherever it differs from the solid line. So the project is not hiding the choice, it is publishing both and marking which is which, which is the reason to read the footnote under any chart rather than the bar height alone.
A failed judge falls through three attempts, then two grades, then nothing
Judge failure is handled in three stages, and the reader can see which stage an answer reached. A judge that fails gets three output attempts. If those are exhausted, two valid grades may be averaged, and the affected answer is marked as judged by two of three rather than three. If votes are still missing, the answer stays unscored rather than being counted as a failure. The consequence is that the panel size varies across the dataset, so a single leaderboard row can be resting on three grades or on two, and the two-grade rows are not equally reliable to the three-grade ones. The scoring and publication rules live in a separate technical document, which is also where the missing-judge case is defined.
The suite counts multiply out exactly, and the two suites are shaped differently
Both suites publish their totals as a product of questions and variants. V1 has 55 questions and 204 model or reasoning variants, which is 11,220 responses. V2 has 100 questions and 226 variants, which is 22,600. Both multiply out with nothing missing, so every variant answered every question in its suite and no answer is quietly absent from the totals. The shape difference is the interesting part. V2 nearly doubles the question count, adding 45, while the variant count grows by 22. In other words the second suite is much broader in what it asks and only slightly broader in who it asks, so per-question difficulty varies far more between the suites than the model coverage does.
Thirteen nonsense techniques, and one thing the benchmark refuses to measure
V2 is built from 13 nonsense techniques spread across five subject areas: software, finance, legal, medical and physics. The framing is deliberate, because the suite only contains invalid premises. The page states the boundary in one sentence: this tests responses to invalid premises, and it does not measure how often models incorrectly reject valid questions. That is the single most important caveat in the documentation, and it cuts both ways. A model that scores well here has shown it can spot nonsense, and the number says nothing about whether it also spots valid questions, so the same model could be excellent on this benchmark and unusable in production for reasons this dataset cannot see.
Reading the results is free, reproducing them is not
The two halves of the project have very different costs. Viewing needs no build step and no API keys, just a static file server on a loopback port:
python3 -m http.server 8795 --bind 127.0.0.1Open the local dashboard and the viewer guide covers filters, comparisons and exports. Running your own evaluations is the expensive half: collection and grading both call paid provider APIs, and the page advises reviewing the selected models before spending on them. That gap between a free dashboard and an expensive rerun is why the published artefacts matter, which is also why each manifest pins the exact question snapshot, the metadata and the immutable data files for its release, and why full response and grade exports are split into bounded files that need a manifest-aware reader to rebuild as JSONL.
Each new model pair gets its own config file at the root
The root directory carries config.json for V1 and config.v2.json for V2, plus a set of files whose names encode both the suite and the models involved: config.new-models.v1.json, config.new-models.v2.json, and one file each for the gpt-5.3-chat with gemini-3.1-flash-lite-preview pairing in V1 and in V2. The question sets follow the same split, questions.json and questions.v2.json. So adding a model pair appears to create a file rather than edit one, which makes the history of a run readable from the file names alone but leaves the root with a growing set of near-duplicates whose relationship is not documented in the visible text. Alongside them sit a drafts directory, a changelog and a storage audit document.
MIT for the code, separate terms for the brand assets, and two viewers
The licence is MIT, with one carve-out stated next to it: third-party brand assets have their own source and licence notes in a separate file inside the viewer's assets directory. That is the arrangement any fork or dashboard reuse needs to respect, since model names and logos are not covered by the repository licence. The viewer itself comes in two generations. The documentation points at a guide inside a directory named next, and the data section still links a legacy viewer page as well. Shipping both means a reader can be on either, which is convenient, and it means two codebases of the same project coexist with no statement on the page about when the older one will go away.
Editorial conclusion
Read this if you want to know whether a model argues back or agrees with a broken premise, and read the denominator before you read the score. Two checks decide how much a number here means. First, know which rate you are looking at, because refusals are excluded from the clear score's denominator but remain in the published leaderboard CSVs, and the trend view draws a second, dotted rate for exactly the cases where the two differ. Second, know what is not measured: the suites only contain invalid premises, so a high pushback rate is not evidence that a model handles real questions well. Reproducing any of it is a separate matter from reading it, since viewing needs nothing but a static file server while collection and grading call paid provider APIs. And if you intend to reproduce it, check the config files first, since each new model pair gets its own file at the repository root.
Frequently asked questions
What does BullshitBench measure?
Whether models detect nonsense, call it out clearly, and avoid confidently continuing with invalid assumptions. Every answer falls into one of three categories: clear pushback, which rejects the broken premise, partial challenge, which flags problems but still engages, and accepted nonsense, which treats the premise as valid.
Who judges the answers in BullshitBench?
A panel of three: Claude Sonnet 4.6, GPT-5.2 and Gemini 3.1 Pro Preview, whose average determines the category. A judge that fails gets three output attempts, after which two valid grades may be averaged and the answer is marked as judged by two of three, and answers with missing votes stay unscored.
How does BullshitBench handle refusals in its score?
The clear score divides clear answers by attempts minus candidate refusals, and errors stay in the denominator. Bars include refusals by default and can be switched to exclude them, model details and CSV exports carry both rates, and canonical leaderboard CSVs retain the all-attempt rate.
Can I run the BullshitBench viewer locally?
To view results, no build step and no API keys are needed. Run python3 -m http.server 8795 --bind 127.0.0.1 from the repository root and open the local dashboard. Running your own evaluations is different, since collection and grading use paid provider APIs.
Does BullshitBench measure whether models wrongly reject valid questions?
No, and the page says so explicitly. The suites test responses to invalid premises and do not measure how often a model incorrectly rejects valid ones. V2 covers 13 nonsense techniques across software, finance, legal, medical and physics questions.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/petergpt-bullshit-benchmark)Star history chart for your README
[](https://hysenlabs.com/projects/petergpt-bullshit-benchmark)Was this useful?