Server Survival: a tower defense game where the enemy is your own infrastructure bill
Tower defense game that teaches cloud architecture. Build infrastructure, survive traffic, learn scaling.
At a glance
- What is it?
- Twenty six billable services, a campaign that removes observability on purpose, and a GPU node whose twelve second model load outlasts the gateway deadline that would have saved its traffic. What the numbers in the design actually encode.
- Who is it for?
- Use it as a teaching aid if you already know what a queue depth is, because the mechanics only pay off once the real concepts are familiar. Do not use it to estimate real infrastructure cost, since the numbers are game values rather than a provider's price list.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 11 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
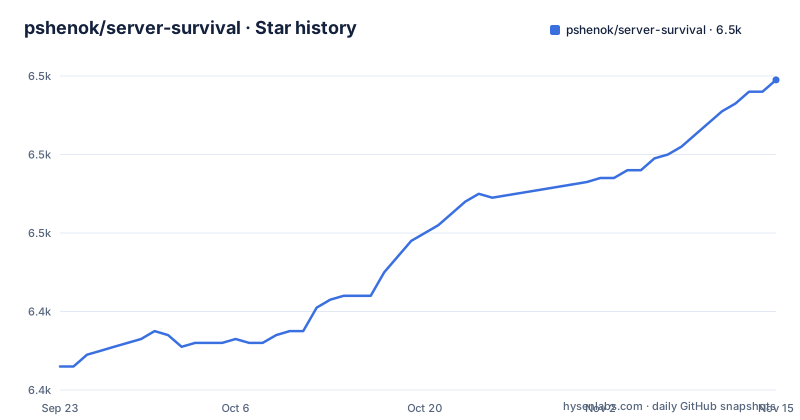
- pshenok/server-survival6,499 ★ · +73
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| pshenok/server-survival | 6.4k | 6.5k |
73 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
There is no build step, because the repository is the game
The package manifest describes itself as dev tooling, and the description field says so outright: the game itself has NO build step, it is served raw from this repo by GitHub Pages, and everything in the manifest is optional and for contributors only, covering lint, tests and CI. The manifest is also marked private, carries no dependencies at all, and holds four scripts that only ever run tooling.
  "scripts": {
    "lint": "eslint .",
    "test": "vitest run",
    "test:watch": "vitest",
    "check": "npm run lint && npm run test"
  },
A contributor is the only person who needs Node at all, and the setup is the ordinary one:
npm install
npm run check
The dev dependencies behind those two scripts are eslint, vitest, happy-dom and globals, which is the standard unit test plus lint pairing for a browser project. Everything else lives beside them: `index.html`, `game.js` and `style.css` at the root, then `assets/`, `docs/`, `src/` and `tests/`, plus a `.nojekyll` marker so GitHub Pages publishes the directory without passing it through Jekyll. A player therefore fetches static files from the project homepage and never touches a package manager, which is the honest reading of a manifest whose version field is 3.0.0.
The GPU warmup outlives the deadline built to absorb it
The inference mechanic contains a timing contradiction worth reading twice. A GPU Cluster loads its model for 12, 20 or 30 seconds depending on tier before it serves anything, and the same load happens again on every tier upgrade. The Inference Gateway exists to buffer requests while a GPU is warming or busy, but it expires anything older than its 6 second deadline, failing the request honestly rather than serving a stale generation.
Put those numbers next to each other and the buffer has no room to work. The shortest warmup in the game is twice the deadline, so a request that arrives early in a cold start expires before the GPU could answer it.
The economics around that gap are equally deliberate. Inference requests earn $0.50 each and the GPU Cluster costs $300, holds capacity 8, and burns $60 per minute whether or not anything is running. Batching caps out at 8, 12 or 16 by tier, and one batch amortizes a fixed per-batch cost, so the design states the outcome plainly: a full batch prints money, a half fed GPU bleeds its upkeep. Model quality moves the other way, from a 10 percent bad answer risk at the smallest tier to 4 percent and then 1 percent, and every bad answer costs half a point of reputation.
Watts set the GPU ceiling before dollars do
The power constraint is stated as its own lesson, and it is the one place in the design where the limit is not a dollar amount. The grid carries 8 kW, every GPU draws 6 kW, and a Substation adds another 6. One GPU fits on the default grid. The second does not, because 12 kW exceeds the 8 kW the line starts with, so the fleet ceiling is bought in power before it is bought in money.
That ordering matters because the GPU is expensive on every meter at once: $300 to place, $60 per minute to keep, 6 kW to draw, and a capacity of 8.
Three compute nodes, three different meters
The compute category prices the same work three ways, which is the clearest lesson in the service table. Compute costs $60, carries capacity 4, and runs at $12 per minute; its role is written as processing requests, auto scaling into a fleet, and it is upgradeable from T1 to T3. A Container Cluster costs $120 for capacity 12 at a flat $16 per minute, described as dense fixed capacity with slow node pool warmup on scale out.
The Serverless Function is the outlier and the most instructive row. It is the cheapest to place at $45 and by far the cheapest to idle at $2 per minute, it holds capacity 30, and then it adds $0.03 for every completed request. The file states the trade in one sentence: cheap when idle, expensive at high RPS. Idle costs fall by $10 per minute against Compute, and the saving is consumed quickly once request volume rises, because the per request fee scales with traffic rather than with the size of the deployment.
Compute fleets scale out at 70 percent utilization and back in at 30 percent. The forty point gap between those two numbers is what stops a fleet from oscillating, and the Container Cluster is called out separately because its warmup is slower than Compute's on the way out.
Level 15 takes the dashboard away on purpose
Observability is a purchasable node rather than a default, and the campaign uses that to teach it. Placing a Monitoring node unlocks a live metrics dashboard with RPS, error rate and latency sparklines, plus alerts. Level 15 in the campaign removes that node first, so the level runs without the metrics, and the dashboard arrives only after the blind stretch is over.
The rest of the diagnostics follow the same rule of making failure legible. Every dropped request raises a badge on the node that dropped it, naming the reason: no route, capacity, read only replica, search only index. A wrong architecture is therefore punished and explained at the same moment, which is the only way a learner tells a routing mistake apart from a shortage.
The three meters the game tracks are budget in dollars, reputation as a percentage, and service health. Health is the one that decays rather than flips: services degrade under load and need repairs, so a stack that is still answering can still be slowly failing. Game over arrives on either of two conditions, reputation at zero percent or the budget at negative $1000, and the campaign builds its 25 levels across five chapters, from Basics through Optimization, Defense and Mastery, Production Readiness, and a final chapter on the AI wave.
Two stores refuse opposite requests
The data layer is built around a deliberate asymmetry. The Data Warehouse takes analytics writes cheaply but refuses realtime reads. The Relational DB makes the opposite trade. Neither is wrong, and the table of traffic types is what makes the choice concrete: WRITE traffic may land on NoSQL, SQL DB or Warehouse, READ traffic goes to a replica, NoSQL or SQL DB, UPLOAD traffic goes to Storage or Warehouse, and SEARCH traffic prefers the Search Engine with an SQL DB fallback.
That refusal vocabulary is what the failure badges borrow their names from. A read only replica and a search only index are not errors a learner invents; they are the two refusals the architecture is built to produce, and the badge names which one fired. A request routed to a store that will not take it gets explained rather than silently discarded.
The front door prices the same lesson again. An API Gateway at $70, capacity 60 and $8 per minute rate limits traffic, and the file is explicit that throttled requests lose less reputation than failed ones, so shedding load early is a scored strategy rather than a penalty. Identity Provider sits at $55, capacity 20 and $6 per minute and is described as adding latency while catching session based attacks that a firewall misses, which is why MALICIOUS traffic lists both as valid destinations.
Sandbox removes game over but not the upkeep clock
Three modes exist and only one of them forgives. Survival is the escalating default, with traffic, DDoS spikes, random events and service degradation. Campaign is 25 hand crafted levels across 5 chapters, each teaching one architecture concept with pre built diagrams, objectives and a debrief. Sandbox is a free play lab with any budget, any traffic mix and no game over, exposing all 26 services at once.
The project also points at a sister title for the layer this one leaves out. Server Survival covers the logical layer, and Datacenter Survival covers the physical one, with power chains, heat, cooling and PUE. That split is a fair description of the scope here: the repository models routing, capacity, batching and pricing, and it stops at the rack.
Editorial conclusion
Use it as a teaching aid if you already know what a queue depth is, because the mechanics only pay off once the real concepts are familiar. Do not use it to estimate real infrastructure cost, since the numbers are game values rather than a provider's price list. Before you point a team at it, check two things: whether anyone on the team reads the full service table of 26 services, and whether the six second inference deadline is the behaviour your own gateway implements. The project is MIT licensed, has no build step, and was pushed on 2026-10-21, so installing it costs nothing but reading the file list.
Frequently asked questions
What kind of project is pshenok/server-survival?
It is an interactive 3D tower defense simulation in which you build a cloud architecture and keep it standing under escalating traffic. You earn money serving legitimate request types, lose reputation when requests fail or when malicious traffic slips past, and lose the run if reputation reaches zero percent or the budget drops to negative $1000.
How many services can you place in Server Survival?
The service roster holds 26 entries grouped into five category tabs, and Sandbox mode makes all 26 available at once. Each service has a cost, a capacity and a per-minute upkeep.
Does Server Survival need npm install to play?
No. The package manifest describes itself as contributor tooling and states that the game has no build step and is served raw from the repository by GitHub Pages. The manifest is private, has no dependencies, and its four scripts only run eslint and vitest for contributors.
What does the GPU Cluster node do in Server Survival?
It batches INFERENCE requests into a single job that amortizes a fixed per batch cost, with batch size capped at 8, 12 or 16 by tier. It costs $300 to place, holds capacity 8, burns $60 per minute, draws 6 kW, and cold starts its model for 12, 20 or 30 seconds on placement and on every tier upgrade.
Is there a Minecraft survival server in this repository?
No, and the name is a coincidence worth flagging. This is a browser tower defense game about cloud architecture with no Minecraft content in its file list.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pshenok-server-survival)Star history chart for your README
[](https://hysenlabs.com/projects/pshenok-server-survival)Was this useful?