Pydantic AI: one typed agent loop, with the model and the harness as arguments
AI Agent Framework, the Pydantic way. Yet despite virtually every Python agent framework and LLM library using Pydantic Validation, when we began to use LLMs in Pydantic Logfire, we couldn't find anything that gave us the same feeling.
At a glance
- What is it?
- Pydantic AI is a Python SDK for agents where the model is a string, the output type is a Pydantic model, and tools are ordinary functions. The typing is the pitch, and the cost is that everything around the loop, from the Gateway to evals, lives in separate packages or products.
- Who is it for?
- Adopt Pydantic AI if you want your agent's inputs, outputs and tools to be ordinary Python types you can lint and test, and if you accept that the model name is a string in your source and the API key is a string somewhere else.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
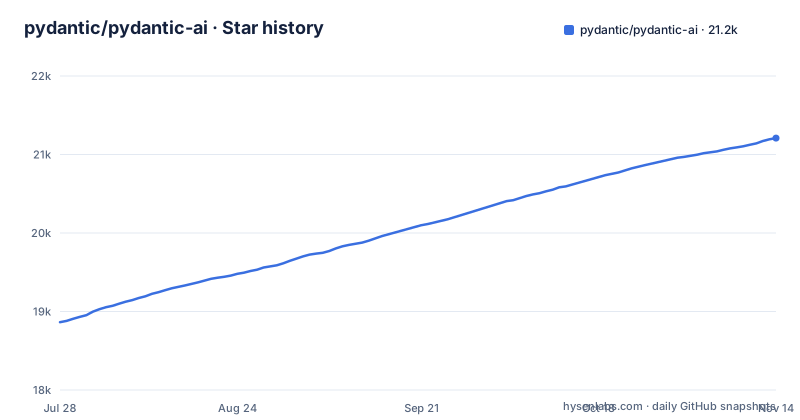
Star history
- pydantic/pydantic-ai21,209 ★ · +2,345
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| pydantic/pydantic-ai | 18.9k | 21.2k |
2,345 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The model is a string, and the provider is its prefix
The pitch in the repository description is a complaint before it is a feature: despite virtually every Python agent framework and LLM library using Pydantic validation, the authors could not find one that gave them the same feeling. So the design goal is that the agent object looks like the rest of a typed Python codebase.
The model is a string with a provider prefix, and that is the whole swap:
from pydantic_ai import Agent
from pydantic_ai.capabilities import WebSearch
from pydantic_ai_harness import Advisor, Coder

agent = Agent(
    'anthropic:claude-fable-5-1',
    capabilities=[
        Coder(),  # files, shell, repo context, sub-agents, context management
        WebSearch(),  # look up docs and error messages on the web
        Advisor('openai:gpt-6.1-sol'),  # a second opinion from another model when stuck
    ],
)
agent.to_cli_sync()
Two providers appear in thirteen lines. Advisor is a second model kept for the case where the first is stuck, so a single agent definition can hold a main model and a second-opinion model from different vendors.
The consequence for a reader is that model choice moves from dependency code into a literal you can grep for. You can swap vendors in one string, and you can also ship the wrong model without any type error to catch it.
output_type is the contract, and a tool is a function with a docstring
The data extraction example is the shortest thing in the README that shows the contract:
from typing import Literal

from pydantic import BaseModel, Field

from pydantic_ai import Agent, RunContext

class Sentiment(BaseModel):
    label: Literal['positive', 'negative', 'neutral']
    score: float = Field(ge=-1, le=1)

agent = Agent('openai:gpt-6.1-sol', output_type=Sentiment)
Field constraints do part of the work. score is bounded between -1 and 1 at the model level, and label is a Literal rather than a free string, so the shape the model has to produce is stated in Python before a request is made.
A tool is an ordinary decorated function, and the first parameter is typed RunContext:
@agent.tool
def recent_reviews(ctx: RunContext, product: str) -> list[str]:
    """Fetch recent review snippets for a product."""
    return ['The new release fixed everything I complained about!']
That function signature is the whole interface the model sees: parameter names, the return annotation, and a docstring written in prose. The README gives the model the rest of the argument and expects a typed value back, so a wrong answer arrives as a validation failure rather than as a string you have to parse later.
Coder decomposes into eight named blocks
The coding agent is sold as one object, then immediately taken apart. Coder is called a regular combined capability rather than a black box, and the README claims the two forms are equivalent:
capabilities = [
    FileSystem('.'), Shell(cwd='.'), RepoContext(), SubAgents(...),
    ClearToolResults(), ToolOutputLimits(), RepairToolArguments(),
]
Three of those seven names describe housekeeping rather than capability. ClearToolResults, ToolOutputLimits and RepairToolArguments deal with tool results and tool arguments, and reading them as a list is more informative than the marketing phrase above them.
The other two that matter for a security review are FileSystem and Shell. The prose calls file access workspace-rooted and shell access allowlisted, and both take a root argument, so the boundary is a constructor argument rather than a policy file somewhere else.
If none of that fits your environment, you can pass the blocks you want and leave the rest out. The cost is that the long-session behaviours are what stop a coding agent from degrading, and dropping those housekeeping blocks because they looked optional is a mistake you will only notice later.
clai runs an exported agent before you write any code
The harness ships an agent you can run without writing a file, through the Pydantic AI CLI:
uvx --with "pydantic-ai-harness[coder]" clai -a pydantic_ai_harness.coder:coder_agent -m anthropic:claude-fable-5-1Read the three pieces. `uvx` fetches the package into a throwaway environment, `--with` names the extra package, `-a` is an import path inside it, and `-m` is a model string in the same format as the Python example. The import path is the exported symbol, so the thing you run in the terminal and the thing you import in code are the same agent.
The base install for the coding agent is one line:
uv add pydantic-ai "pydantic-ai-harness[coder]"The gap worth knowing about is credentials. Both paths name a provider and a model, so a first run needs credentials for that provider. Check your provider's key setup before you spend time on the rest of the configuration.
v1.107.7 and v2.52.0 shipped one second apart
Three recent releases tell you more about the upgrade path than a version policy would. v2.65.0 was published on 2026-11-03 with 2026-11-02 in the tag name, v2.64.0 on 2026-10-30, and a separate clai2-bleeding release on 2026-10-06. Releases arrive days apart.
The consequence is that "the latest release" moves quickly, so pin the version you tested against.
The version number itself is generated. pyproject.toml sets the build backend to hatchling with uv-dynamic-versioning, and the tool is configured with vcs = "git", style = "pep440" and bump = true. So the version comes from git tags, not from a number in the source. If you mirror the repository without tags, or install from a checkout, the version string you get is not the one on PyPI, and that shows up in bug reports before it shows up anywhere else.
The Makefile checks for uv before it does anything else
The first target in the Makefile is a tool check, and it is the first thing a contributor hits:
uv --version || echo 'Please install uv: https://docs.astral.sh/uv/getting-started/installation/'Contributing means uv, and the install line shows the shape of it:
uv sync --frozen --all-extras --no-extra mcp-tasks --all-packages --group lint --reinstall-package griffelibThree things in that line are worth reading twice. `--frozen` means the checked-in uv.lock is authoritative, so a contributor environment is reproducible. `--no-extra mcp-tasks` excludes exactly one extra by name while taking everything else. `--all-packages` covers the several packages in the tree rather than one.
The sweep target then builds an environment per interpreter, and it matches what the project claims. install-all-python covers Python 3.11, 3.12, 3.13, 3.14 and 3.15, the same versions the classifiers in pyproject.toml list. So a local full sweep exercises every interpreter the package advertises, and the pre-commit hooks are bootstrapped through uv if pre-commit is not already on your path.
Budget control belongs to the Gateway, not to the SDK
Here is the boundary that matters for cost. Real-time cost monitoring and budget control are attributes of the Pydantic AI Gateway, which the README calls one key for every model. The SDK is the thing that calls a model; the cap on what that call may spend is a service in between.
If you skip the Gateway and hold provider keys directly, the model string still works and nothing in the agent definition is aware of the missing piece. You lose the budget ceiling the README attributes to the Gateway.
Observability is the opposite case, and the asymmetry is worth understanding before you pick. The instrumentation is plain OpenTelemetry, so any backend you already run works, and that part is not locked in. Pricing is a third moving part: genai-prices is a separate package that keeps model pricing current.
Pydantic Graph and Pydantic Evals are separate packages
Not everything lives in pydantic-ai, and the tree at the top of the repository says so: pydantic_ai_slim, pydantic_graph, pydantic_evals and clai are siblings, alongside src/, examples/, agent_docs/ and tests/. Graph is for typed control flow and Evals grades an agent's final outputs and tool-call trajectories, both named as separate packages rather than as modules of the SDK.
This is the alternative to the framework, in the sense that matters for a decision. If your problem is only typed control flow, a graph package that does not carry the agent loop is the smaller dependency. If your problem is only testing, the evals package is the piece to reach for. Adding the whole SDK to get one of them is the trade the split is there to prevent.
The third option is pydantic_ai_slim, another directory at the top of the tree. Monty is a fourth, named as the sandboxed Python interpreter that runs model-written code, which is a different answer to the same question: not a smaller package but a sandbox for model-written code.
Editorial conclusion
Adopt Pydantic AI if you want your agent's inputs, outputs and tools to be ordinary Python types you can lint and test, and if you accept that the model name is a string in your source and the API key is a string somewhere else. Do not adopt it expecting a cost ceiling or a debug view from the SDK alone, because real-time cost monitoring and budget control belong to the Pydantic AI Gateway, and observability is a separate product even though the instrumentation underneath is plain OpenTelemetry. Verify three things before you commit. Check which release you are on, since v2.64.0 and v2.65.0 were published days apart. Read the docstring on your tools, because the example in the README puts its explanation in the function docstring and the function signature is what the model sees. And install with uv add pydantic-ai as the README shows, and note that the version comes from git tags through uv-dynamic-versioning, so an untagged checkout does not produce the version string you expect.
Frequently asked questions
How do I install Pydantic AI?
With uv, as the README shows: uv add pydantic-ai for the SDK, or uv add pydantic-ai "pydantic-ai-harness[coder]" for the coding agent. The package requires Python 3.11 or newer, and the project builds with hatchling and uv-dynamic-versioning.
What is pydantic-ai?
A Python AI SDK built around a typed, extensible agent loop where the model is a string away. The same agent can run behind a web frontend, in the terminal, on a voice call, on a durable background queue or in GitHub Actions, and image generation and embeddings come in the same box.
What is pydantic_ai_slim?
A directory at the top of the repository tree, beside pydantic_graph, pydantic_evals and clai. Its own packaging metadata is where you would look for what it contains.
What is the Pydantic AI Gateway?
A layer that gives you one key for every model, with real-time cost monitoring and budget control. Separately, Pydantic AI's instrumentation is plain OpenTelemetry, so any backend you already run works.
What is RunContext in Pydantic AI?
It is the type of the first parameter on a tool function, as in def recent_reviews(ctx: RunContext, product: str). The remaining parameters and the return annotation are what the model is shown, and the docstring is where the function explains itself in prose.
Is Pydantic AI better than LangGraph?
The README does not compare the two. It describes Pydantic AI as a typed, extensible agent loop with every model a string away, and points at Pydantic Graph as a separate package for typed control flow, which is the closest thing to a like-for-like comparison available in the documentation.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pydantic-pydantic-ai)Star history chart for your README
[](https://hysenlabs.com/projects/pydantic-pydantic-ai)Was this useful?