ai-berkshire sets four investors loose on one company and makes them disagree
AI 时代的伯克希尔:基于 Claude Code / Codex 的价值投资研究框架。巴菲特·芒格·段永平·李录四大师方法论 + 多Agent并行研究。| AI-era Berkshire: a value investing research framework built for Claude Code / Codex. 4 masters' methodologies + multi-agent adversarial analysis.
At a glance
- What is it?
- ai-berkshire is a collection of skills for Claude Code and Codex that systematises four value-investing methodologies and lets four agents research a company in parallel before a lead synthesises them. The parts worth reading are the disagreement it manufactures on purpose, the anti-bias checks that can veto a stock outright, and the habit of verifying market caps with exact decimal arithmetic.
- Who is it for?
- ai-berkshire fits an individual investor who wants a written process instead of a chat session, and who values being told to wait or to look elsewhere more than being told a company is interesting. The parts to adopt first are the cheapest ones: the mirror test that forces a five-sentence explanation, the rejection checklist that can veto on management integrity regardless of valuation, and the decimal verification of any market cap you are about to act on.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
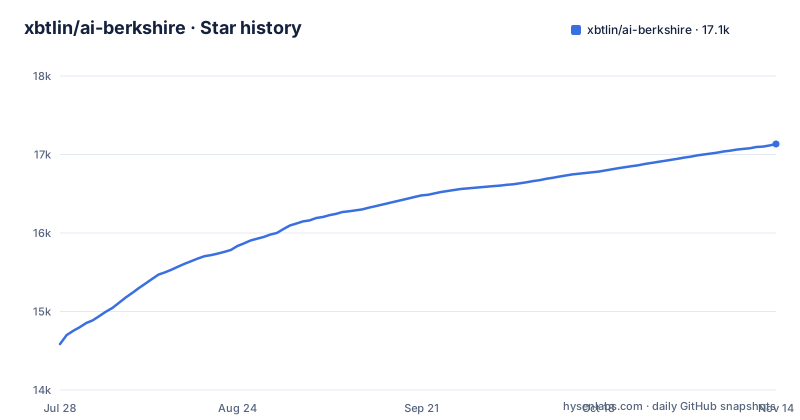
- xbtlin/ai-berkshire17,134 ★ · +2,549
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| xbtlin/ai-berkshire | 14.6k | 17.1k |
2,549 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Twenty named entry points, and the tables add up to twenty-one
The architecture is three layers, and the top one is a catalogue. Skills are grouped into deep research, earnings analysis, industry screening, portfolio management and thinking tools, each entry naming a file and the situation it suits. The grouping tells you how the thing is meant to be used: some entries are about a single company, some about an industry chain, some about what you already own after the buy, including a thesis tracker and a drift detector that separates fact changes from valuation changes from wording changes. The skills heading now counts twenty-two skills. The second layer matters more than the count. A team-type skill such as the investment team or the earnings team dispatches four agents in parallel through a team lead, while a lightweight skill skips that layer and calls tools directly, so you pay for multi-agent work only where it earns its cost.
The four viewpoints are scored so they can contradict each other
The framework is built on the methodologies of four investors, and the worked example shows why more than one is the point. On the same company, four perspectives produce four different scores: the business-model view scores 3.7 out of 5 because the C2M model is hard to copy, the financial-valuation view scores 4.4 because the ex-cash price-earnings ratio is low and the business is described as a cash printer, the inversion view scores 3.5 because the moat is shallower than it looks and a competitor reached enormous gross merchandise value in three years, and the long-term-certainty view scores 2.0 because of management culture doubts and no certainty about a decade out. The stated conclusion is that the conflict is the real state of an investment decision, and one value investor saying it is genuinely cheap while another says do not buy when uncertain is exactly the tension a single prompt cannot manufacture.
Five anti-bias checks, one of which can veto the stock
The argument the readme makes is that the dangerous output is not a wrong answer but a plausible one, so the process contains five named defences. An information richness rating from A to C exists to stop more material from being read as more certainty, with one company rated B because the data is thin and derived figures are marked with their confidence. An inversion check forces the failure question, answered as a list of scenarios with probabilities. A fast rejection checklist holds eight red lines with single-veto power, and the example given is a management integrity stain, which rejects the company no matter how cheap the valuation. An anti-consensus check asks why informed people are shorting. The white-space principle prefers saying it does not know: when data is insufficient the output is marked as a grey zone rather than dressed up with speculation. On top of those sits the mirror test, which says that failing to explain the thesis in five sentences means not buying, with no exceptions.
Market caps are checked with a decimal, not a float
The financial-precision section starts from a fair criticism: a model doing arithmetic in its head can move a decimal point, and confusing units between Hong Kong dollars and renminbi can change a conclusion. The worked case is a real one, where two sources for the same market cap disagreed on the currency unit. The fix is a script rather than a prompt instruction, taking a price, a share count, the reported figure and a currency, and printing the deviation, which the example reports as 0.08 percent:
python3 tools/financial_rigor.py verify-market-cap \
  --price 510 --shares 9.11e9 --reported 4.65e12 --currency HKD
The surrounding rule is that all calculation uses exact decimal arithmetic in Python rather than floating point, and that key figures come from at least two independent sources.
The same input has to produce the same shape of output
Reproducibility is the claim that separates this from a chat session. Asking a model directly gives a different format, depth and coverage every time, so one company gets a moat score and the next forgets it. The framework's promise is that identical input produces identical structure and depth, and the readme lists three things that buys: comparing seven companies against identical criteria, re-analysing one company six months later to diff the change, and aligning research between team members. The seven-company table shows the shape of that output, with columns for circle of competence, good business, moat, management and margin of safety, and an overall score that produces three different verdicts. Two pass, three are conditional, two land in the grey zone, and the two greys are precisely the cases the white-space principle exists for.
Four agents research in parallel, then a lead synthesises
The team skill starts four independent agents on one company at the same time. Each one searches the web, cross-checks its data and reaches its own conclusion, and the emphasis is that this is not one prompt split into four parts but four analysts each doing complete research, with a team lead synthesising afterwards. The stated benefit is arithmetic: one person asking a model has one context window, while four agents mean four times the search volume, four times the sources and four independent views.
The performance table is a claim, and the readme says so
The readme opens with a real track record section, and it is the one part of this repository nobody outside the author can verify. It claims a full-year return of 69.29 percent for 2024 and 66.38 percent for 2025, tabulated against four indices, with excess-return figures stated in percentage points against two of them, and a cumulative figure of more than 1.46 million yuan over two years. The disclaimer directly under the table says historical returns do not indicate future performance and that the screenshots come from a real brokerage account. Set that against the rest of the repository. The research library is indexed by a generated banner, updated by a script under the tools directory and marked as not to be edited by hand, reporting thousands of reports across over a hundred companies and twenty-nine topics, with the newest entry from late October 2026. A single tag, v1.0.0 from April 2026, is the whole release history, while the default branch has moved since.
Editorial conclusion
ai-berkshire fits an individual investor who wants a written process instead of a chat session, and who values being told to wait or to look elsewhere more than being told a company is interesting. The parts to adopt first are the cheapest ones: the mirror test that forces a five-sentence explanation, the rejection checklist that can veto on management integrity regardless of valuation, and the decimal verification of any market cap you are about to act on. What to be careful about is the part the readme cannot prove. The published annual returns are the author's own claim, with a disclaimer attached, and the research library is the author's own work, so treat the track record as marketing and the mechanics as the product. The licence is MIT and the repository has one tag, v1.0.0 from 2026-04-07.
Frequently asked questions
What is AI Berkshire?
It is a collection of investment research skills that works with both Claude Code and Codex, systematising the methodologies of four value investors into structured research. It is organised in three layers: twenty-two named skill entry points, an agent layer where team skills dispatch four perspectives in parallel under a team lead, and a tool layer for exact calculation, live search and report checks.
How does AI Berkshire make four investors disagree?
Each perspective scores the same company on its own axis, business model, valuation, inversion and long-term certainty, and the scores are expected to conflict. The worked example ends with one view calling a stock genuinely cheap and another refusing to buy because a decade of certainty is missing. The readme's argument is that this tension is the real state of an investment decision and that a single prompt cannot manufacture it.
How does AI Berkshire verify financial figures?
It checks market cap by multiplying price by share count with a script and comparing the result against the reported figure, all in exact decimal arithmetic rather than floating point, after a real case where two sources disagreed on the currency unit. Key data must come from at least two independent sources.
Which coding agents can run the AI Berkshire skills?
Both Claude Code and Codex are supported, and the repository ships matching directories for each, with separate prompt and skill trees for Codex.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/xbtlin-ai-berkshire)Star history chart for your README
[](https://hysenlabs.com/projects/xbtlin-ai-berkshire)Was this useful?