PyTorch Frame: TensorFrame, Semantic Column Types and a Modular Pipeline for Deep Tabular Models
Tabular Deep Learning Library for PyTorch
At a glance
- What is it?
- PyTorch Frame turns a pandas DataFrame into a TensorFrame and trains deep models over heterogeneous columns, including text, timestamps and images. It is a research framework in beta, and it does not claim to beat gradient boosted trees.
- Who is it for?
- PyTorch Frame suits researchers and engineers who need to put text, timestamps or image columns into one neural model and want reusable encoder, convolution and decoder parts. It is a weaker fit for a team that just needs the best score on a plain numeric table, since the library itself benchmarks against GBDTs instead of promising to beat them, and its package metadata still marks it as beta.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 12 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
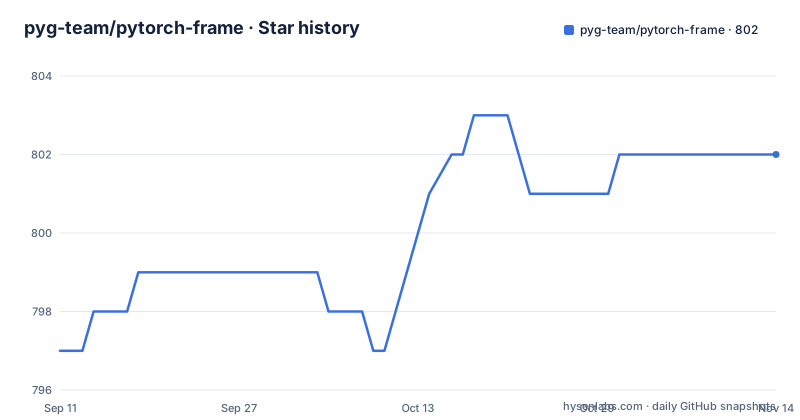
- pyg-team/pytorch-frame802 ★ · +5
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| pyg-team/pytorch-frame | 797 | 802 |
5 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Eight semantic column types decide how each column is encoded
The central idea in PyTorch Frame is that a table column has a meaning, not just a dtype. The library supports learning across `numerical`, `categorical`, `multicategorical`, `text_embedded`, `text_tokenized`, `timestamp`, `image_embedded` and `embedding` columns. These semantic types are what the code calls stypes, imported from `torch_frame` as `stype`.
The practical effect is that you describe your data once, and the encoders pick the right treatment per column. A timestamp column does not get treated as an arbitrary float, and a text column can arrive either as precomputed embeddings or as tokens for a model to read. The README points to a tutorial on handling heterogeneous stypes for the detail.
The cost is up-front annotation. Before you train anything, you have to decide which stype each column is. A wrong choice, such as a high-cardinality ID treated as categorical, is your responsibility, and the library will not infer the right answer for domain-specific columns. The README describes the supported types, but gives no automatic detection guarantee, so check your column mapping before reading any benchmark number.
Models are built from Materialization, FeatureEncoder, TableConv and Decoder
Every model follows a four-part pipeline. `Materialization` converts the raw pandas `DataFrame` into a `TensorFrame` suitable for PyTorch training. `FeatureEncoder` encodes the `TensorFrame` into hidden column embeddings of shape `[batch_size, num_cols, channels]`. `TableConv` models column-wise interactions over those embeddings. `Decoder` generates an embedding or prediction per row.
The quick tour builds a small `ExampleTransformer` from these parts. Its imports show the building blocks:
from torch import Tensor
from torch.nn import Linear, Module, ModuleList

from torch_frame import TensorFrame, stype
from torch_frame.nn.conv import TabTransformerConv
from torch_frame.nn.encoder import (
    EmbeddingEncoder,
    LinearEncoder,
    StypeWiseFeatureEncoder,
)
In that example, `self.encoder` maps a `TensorFrame` to an embedding of size `[batch_size, num_cols, channels]`, `self.convs` repeatedly transforms it into an embedding of the same size, and `self.decoder` pools it into `[batch_size, out_channels]`.
This modularity is the library's selling point and its learning curve. You can swap a convolution without touching the encoder, but you also need to understand tensor shapes across all four stages before writing a custom model.
Gradient boosted trees ship alongside the neural models as the baseline to beat
The README is candid about the competition. Historically, tree-based models such as GBDT excelled at tabular learning, though with limitations: integration difficulties with downstream models, and trouble with complex column types such as text, sequences and embeddings. Deep tabular models are described as promising to resolve those limits, and the library aims to make deep learning research on tabular data easier by modularising the implementation.
So the library implements strong GBDTs too, namely XGBoost, CatBoost and LightGBM, with hyperparameter tuning, and it benchmarks deep tabular models against them in a benchmark folder. There is an `examples/tuned_gbdt.py` script for the tuned baselines.
Those extras live behind the `full` option in pyproject.toml, which lists scikit-learn, xgboost pinned to `>=1.7.0, <2.0.0`, optuna, optuna-integration, `mpmath==1.3.0`, catboost, lightgbm, datasets and torchmetrics. The xgboost upper bound and the exact mpmath pin mean the full install can conflict with other packages in a shared environment. The base dependencies are only numpy, pandas, torch, tqdm, pyarrow and Pillow, so check which extras you actually need.
Text columns can use embeddings from OpenAI, Cohere, Hugging Face or Voyage AI
A stated goal is integration with diverse architectures such as large language models. With any downloaded model or embedding API endpoint, you can encode text data as embeddings and train it with deep learning models alongside other complex semantic types. The README shows four starting points: OpenAI embeddings, Cohere Embed v3, Hugging Face models and Voyage AI. The OpenAI, Cohere and Voyage examples point to `examples/llm_embedding.py`, and the Hugging Face one to `examples/transformers_text.py`.
The split between `text_embedded` and `text_tokenized` columns matters here. Embedded text means a model has already turned each cell into a vector, while tokenized text lets a downstream model process tokens.
Two consequences follow. Using an embedding API means sending your table's text to a third-party service and paying per request, and the README attaches no cost or privacy notes. And embedding a large text column is a preprocessing step you run before training, so its time cost sits outside the training loop. Using a local Hugging Face model avoids the API route, at the price of your own compute.
The examples folder is the real index of implemented models
The README links an Implemented Deep Tabular Models section, but the clearest list of what runs is the examples folder. It contains excelformer.py, revisiting.py, tab_transformer.py, tabnet.py, tabpfn_classification.py, trompt.py and a multi-GPU variant, trompt_multi_gpu.py. There are also mercari.py, tabular_image.py, tutorial.py, llm_embedding.py, transformers_text.py and tuned_gbdt.py.
The file names tell you what the library has exercised: TabTransformer, TabNet, ExcelFormer, Trompt, a TabPFN classification example, an image-plus-tabular example and a Mercari dataset script. Only trompt has a multi-GPU script, so for the other models, assume single-device training until you test otherwise.
A script existing is not a published result. Accuracy numbers for each model live in the benchmark folder and the paper, not in these file names, and the README gives no scores for them. Before choosing a model for your project, run the matching example on your own data and compare it with the tuned GBDT baseline, since dataset shape changes which approach wins.
Pairing with PyG lets deep learning run over relational databases
One integration point is spelled out. PyTorch Frame builds on PyTorch and integrates with other PyTorch libraries, supporting end-to-end training with downstream models. By combining it with PyG, the PyTorch library for graph neural networks, you can perform deep learning over relational databases. The README points to RelBench and its example code from Stanford's snap-stanford group for the details.
In that setup, PyTorch Frame handles the rows of each table, with their mixed column types, and a graph model handles the links between tables. The library therefore acts as the table encoder inside a larger system, not as a full relational learning stack on its own.
If you only have a single flat table, that pairing is unnecessary and you can ignore it. If your data spans linked tables, the README sends you to external projects for the workflow, so expect to learn PyG and RelBench conventions as well. The README does not walk through the relational pipeline itself.
The package is beta on Python 3.10 and later, with its last tagged release in November 2025
The package metadata is explicit about maturity: the development status classifier is 4 - Beta. It requires Python 3.10 or newer, and the classifiers list 3.10 through 3.14. The build uses flit_core, and the version is read dynamically from the module.
The release list shows 0.3.0, titled Broader Compatibility & Usability Enhancements, on 2025-11-02, 0.2.5 titled Python 3.13 and PyTorch 2.6 support on 2025-02-12, and 0.2.4 on 2025-01-17. The last push to the main branch was on 2026-10-05, so there is a year between the newest tag and today, with commits since. If you pin a version, the newest tagged release may not include recent main branch work.
The package is published as pytorch-frame and the repository links a documentation site on Read the Docs. A paper on arXiv describes the design. Because the library is beta and the API is organised around newer PyTorch versions, test the combination of PyTorch Frame, torch and your Python version in a clean environment before committing a project to it.
Editorial conclusion
PyTorch Frame suits researchers and engineers who need to put text, timestamps or image columns into one neural model and want reusable encoder, convolution and decoder parts. It is a weaker fit for a team that just needs the best score on a plain numeric table, since the library itself benchmarks against GBDTs instead of promising to beat them, and its package metadata still marks it as beta.
Frequently asked questions
What is PyTorch Frame used for?
PyTorch Frame is a PyTorch extension for deep learning on heterogeneous tabular data. It handles numerical, categorical, time, text and image columns through a modular encoder, convolution and decoder design.
Does PyTorch Frame replace XGBoost or LightGBM?
No. The library implements XGBoost, CatBoost and LightGBM as tuned baselines and benchmarks deep tabular models against them. It aims to support complex column types that tree models handle poorly.
Can PyTorch Frame use text embeddings from LLM providers?
Yes. The examples cover OpenAI embeddings, Cohere Embed v3, Voyage AI and Hugging Face models, so text columns can be encoded as embeddings and trained with other column types.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pyg-team-pytorch-frame)Star history chart for your README
[](https://hysenlabs.com/projects/pyg-team-pytorch-frame)Was this useful?