Qwen3.8: a three-file repository where the real artefacts are model cards
Qwen3.8 is the large language model series developed by Qwen team, Alibaba Group.
At a glance
- What is it?
- The Qwen3.8 repository holds a licence, a readme and a GitHub directory. Everything that matters is elsewhere: the weights are on Hugging Face and ModelScope, the benchmark numbers are on model cards, and the introduction still describes the repository as the home of the Qwen3.5 series. The model itself is the first Qwen-Max-class release to be open.
- Who is it for?
- Use this repository as the index it is: it tells you which sizes exist, when they were published, where to get the weights and which two environment variables redirect a serving framework to ModelScope. It is not a place to read code or a source of benchmark results, so plan to follow every claim to a model card.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 90 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
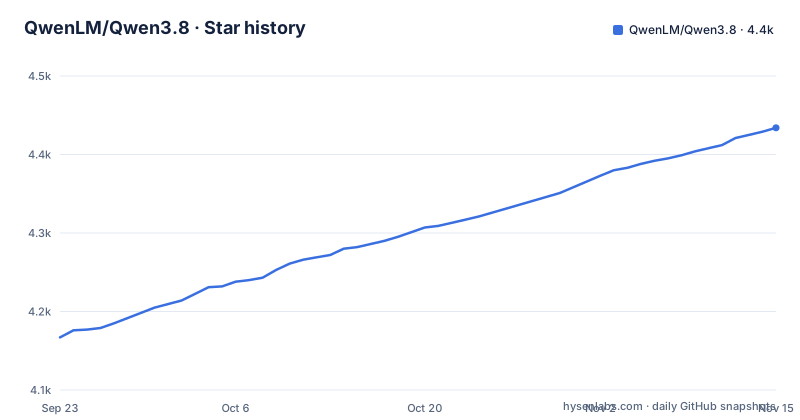
Star history
- QwenLM/Qwen3.84,434 ★ · +267
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| QwenLM/Qwen3.8 | 4.2k | 4.4k |
267 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three files, no weights, no code
The repository contains a GitHub directory, a licence file and a readme. That is the entire tree, and the repository reports no programming language.
There are no releases either. The most recent push is dated August 17, 2026.
So this is an index rather than a codebase. It exists to point at things: the hosted chat interface, the model organisation on Hugging Face, the model organisation on ModelScope, a chat community, a Discord server, and the model cards themselves.
That arrangement has one practical consequence worth stating plainly. The repository is licensed Apache-2.0, and the benchmark results are on the model cards. Anyone doing a compliance or evaluation pass has to follow every link rather than read one file.
For an audience arriving from a search result, this repository is the announcement, and the artefacts are elsewhere.
The introduction still calls it the Qwen3.5 series
The welcome paragraph has not caught up with the name of the repository.
It welcomes you to the GitHub repository of the Qwen3.5 open model series, and then lists three things inside it: Qwen3.5, Qwen3.6 and the latest Qwen3.8.
The rest of the page is organised the other way, with Qwen3.8 first, then Qwen3.6, then Qwen3.5. So the document's structure says the newest model leads, and its opening sentence says the series is named after the oldest one in it.
There is a second stale reference in the same region. The chat community image at the top of the page points at an asset in a different repository, the one named Qwen rather than Qwen3.8. That suggests the header block was copied forward and not revisited.
Neither issue changes what the model is. Both are the kind of detail that matters when a reader is checking whether a page has been updated, and the answer here is that the body has and the header has not.
Two knobs decide how much reasoning happens
The fourth listed enhancement for Qwen3.8 is control over thinking, and it names two settings.
One tunes reasoning depth, so you can ask for more or less deliberation per request. The other retains reasoning context from historical messages, so earlier thinking is carried forward instead of being discarded.
The second one is not new to the series. Qwen3.6's listed upgrade is thinking preservation across conversation history, described as streamlining iterative development and reducing overhead. So the capability arrived with the previous version and is listed again as part of what Qwen3.8 exposes.
That combination is worth thinking about as a pair rather than as two features. Depth is a per-request cost, and preservation is a per-conversation one: the more history you keep, the more context each later request carries. A long iterative session with depth turned up is the most expensive configuration the page describes, and the introduction gives no default for either setting.
The other two entries in that list are broader: stronger autonomous planning and better handling of environment feedback for agent execution, and broader support for popular harnesses and development tools.
The 27B arrived two days after the 2.4 trillion parameter model
The news list is a dated release log, and the two newest entries are worth reading as a pair.
On August 12, 2026 Qwen3.8-2.4T-A95B was published. On August 14, 2026, two days later, the 27 billion model was published.
So the smaller model shipped second, which means a reader who stopped at the first announcement was looking at the model that is hardest to serve.
Earlier in the same list, Qwen3.6 published a 35B-A3B model in April and a 27B model a few days after that. Qwen3.5 shipped its larger sizes in February and its 9B, 4B, 2B and 0.8B models on March 2, with the first release being a 397B-A17B mixture-of-experts model. That 27B name appearing in three different series is a naming overlap to keep in mind when you read a model identifier.
Most entries are announced on both the Hugging Face Hub and ModelScope, and they point at model cards, collections or release blogs rather than at documentation in this repository.
Two hubs, two environment variables, three download commands
Weights are distributed from two places, and the page is explicit about which one to prefer.
The primary route is the Hugging Face Hub, where most language model frameworks download files automatically once you give them a model identifier, with three examples given in the page. You can also fetch the files by hand with the download command from that hub's tooling, or clone the repository.
The alternative is ModelScope, and the recommendation is explicit: for users unable to access Hugging Face Hub, use ModelScope.
SGLANG_USE_MODELSCOPE=true
VLLM_USE_MODELSCOPE=true
Those two environment variables are how a serving framework is redirected, and they apply to supported frameworks.
The manual routes are symmetric. Each hub has its own download command, and both allow a plain clone.
The Models section does not state hardware requirements. It gives no guidance about memory, quantisation or which size fits which machine, so that information has to come from the model card for the size you picked.
The architecture description belongs to Qwen3.5
The technical detail in this repository is attached to the oldest model in the series, not the newest.
Qwen3.8 is described as built on the architectural foundation of Qwen3.5, and the four Qwen3.8 enhancements are capability claims rather than architecture claims. If you want to know how the model is built, the answer is in the Qwen3.5 section: a unified vision-language foundation trained with early fusion on trillions of multimodal tokens, an efficient hybrid architecture combining gated delta networks with sparse mixture-of-experts for high throughput inference at low latency, reinforcement learning scaled across million-agent environments with progressively complex task distributions, expanded support for 201 languages and dialects, and training infrastructure described as near full efficiency on multimodal data relative to text-only training.
Two of those claims have consequences outside the model. The vision-language foundation means the series handles images as well as text.
One older entry in the news list also names an architecture, describing a mixture-of-experts model with hybrid attention as ultra-sparse and designed for extreme efficiency. So the naming convention carries architecture information in the size suffix, which is why a reader comparing 2.4T-A95B with 397B-A17B can infer a great deal without a model card.
No benchmark numbers, only links to cards
The benchmarks section is a set of pointers.
For the Qwen3.8 open models, the reader is sent to the model card for the 2.4T-A95B model and the model card for the 27B model. For Qwen3.6, to a blog post.
The Qwen3.8 benchmark entry gives no figure: no score, no benchmark name with a number attached, no comparison against another model on a named task.
That is a defensible editorial choice, since a table of numbers in a repository readme ages badly and the model cards carry per-size detail anyway. It also means the page cannot be used to compare sizes against each other or against anything outside the series. Choosing between the 27B and the 2.4T-A95B means opening two model cards.
The same applies to the earlier versions. Every announcement in the news list ends with a pointer to a card or a blog post rather than to a summary, which keeps the readme stable as results are updated.
Editorial conclusion
Use this repository as the index it is: it tells you which sizes exist, when they were published, where to get the weights and which two environment variables redirect a serving framework to ModelScope. It is not a place to read code or a source of benchmark results, so plan to follow every claim to a model card. Before you commit to a size, note that the architecture description is inherited from Qwen3.5 rather than restated for Qwen3.8, and that the two thinking controls, one for depth and one for retaining prior reasoning context, change the cost of a request as well as its behaviour. If you cannot reach Hugging Face, the ModelScope path is the documented alternative rather than a workaround.
Frequently asked questions
What is Qwen3.8?
It is the latest release in the Qwen3 open model series, from the Qwen team at Alibaba Group. It is described as the first time a Qwen-Max-class model is being released openly, built on the architectural foundation of Qwen3.5, with the emphasis on coding, professional work, research and long-horizon agentic tasks.
How do I install Qwen3.8?
Download the weights rather than installing a package. Most frameworks fetch the files from Hugging Face Hub when you give them a model identifier such as Qwen/Qwen3.8-27B, or you can use the hub download command or clone the repository. If you cannot reach Hugging Face, use ModelScope instead.
How do I install Qwen3.8-27B?
It is published on Hugging Face Hub and ModelScope as a 27 billion parameter model, released on August 14, 2026. Follow the instructions on the model page, and use the ModelScope download command if you need the alternative hub.
Is Qwen3.8 open source?
The repository is licensed under Apache 2.0, and the official model weights are published openly on Hugging Face Hub and ModelScope. The repository itself contains only a readme, a licence and a GitHub directory, so the weights live on the hub pages they are published from.
Can I run Qwen3.8 locally?
The weights can be downloaded manually or by framework, which is the prerequisite for running the model yourself. The download instructions give no hardware guidance: no memory figures, no quantisation advice and no guidance on which size fits which machine. That information is on the model card for the size you choose.
What is Qwen3.8-27B MoE?
The readme lists Qwen3.8 sizes including 27B and 2.4T-A95B without restating the architecture for them. It names mixture-of-experts explicitly for Qwen3.5, whose first release was a 397B-A17B MoE model, and for an earlier ultra-sparse MoE model with hybrid attention, so the total and active parameter counts in a model name carry that information.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/qwenlm-qwen3-8)Star history chart for your README
[](https://hysenlabs.com/projects/qwenlm-qwen3-8)Was this useful?