Qwen3-Omni: a readme that counts 19 speech input languages and lists 18
Qwen3-omni is a natively end-to-end, omni-modal LLM developed by the Qwen team at Alibaba Cloud, capable of understanding text, audio, images, and video, as well as generating speech in real time.
At a glance
- What is it?
- Qwen3-Omni is an omni-modal model from the Qwen team at Alibaba Cloud that takes text, image, audio and video and streams back text and speech. Its readme claims SOTA on 22 of 36 audio and video benchmarks, open-source SOTA on 32 of 36, and 19 speech input languages, then lists 18. The repository itself holds two Python demo scripts, a docker directory and a folder of cookbooks.
- Who is it for?
- Qwen3-Omni is worth evaluating if you need one model that both hears and speaks, since the streaming speech output and the single shared namespace are what distinguish it from an ASR model feeding a text model. Read the benchmark claim carefully before quoting it, because the two figures in that sentence measure different things and neither comes with a comparison you can reproduce from the repository.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
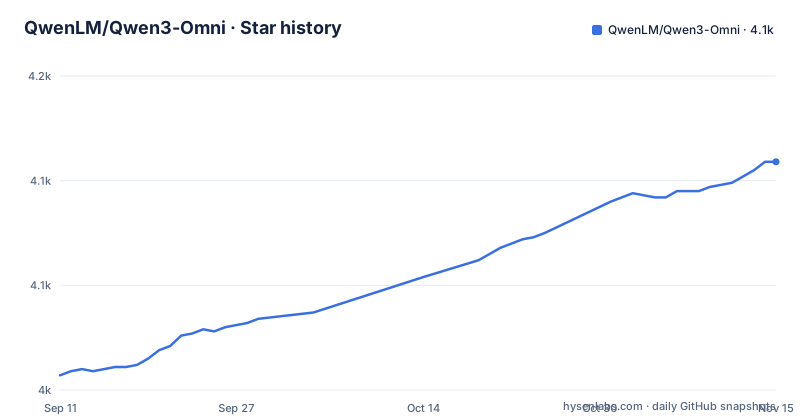
- QwenLM/Qwen3-Omni4,109 ★ · +102
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| QwenLM/Qwen3-Omni | 4k | 4.1k |
102 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The readme says 19 speech input languages and lists 18
The multilingual bullet claims support for 119 text languages, 19 speech input languages, and 10 speech output languages. Two of those three numbers check out against the lists underneath them, and one does not.
The speech output list names ten: English, Chinese, French, German, Russian, Italian, Spanish, Portuguese, Japanese and Korean. That matches the claim exactly.
The speech input list names eighteen: English, Chinese, Korean, Japanese, German, Russian, Italian, French, Spanish, Portuguese, Malay, Dutch, Indonesian, Turkish, Vietnamese, Cantonese, Arabic and Urdu. The claim says nineteen. Nothing in the readme explains the gap, and Cantonese being listed alongside Chinese suggests the count may treat a regional variant differently from the way it is written out.
For a model where language coverage is the deciding factor, that is worth resolving before you commit. The readme does not link a separate language coverage table, so this list is the only enumeration available.
Two benchmark numbers, two different meanings
One bullet carries two claims. The first says it reaches state of the art on 22 of 36 audio and video benchmarks. The second says it reaches open-source state of the art on 32 of 36.
Those are different measurements and they are not nested in an obvious way. If the open-source figure counted a superset of the same 36 benchmarks, then 22 of 36 closed models beat it and 14 remain where no open model is better, which is a coherent reading. If instead the two figures come from different benchmark sets, then neither number can be applied to a benchmark you care about without checking.
The same bullet then adds that ASR, audio understanding and voice conversation performance is comparable to Gemini 2.5 Pro. Comparable is not better, and it is the only named external system in the entire readme.
The repository publishes no evaluation code and no results table. The contents list has an Evaluation section with a performance subsection and a setting for evaluation subsection, and both point outward rather than to files here.
The repository is two demo scripts and a folder of notebooks
The top level contains `.github/`, `LICENSE`, `README.md`, an `assets/` directory, `cookbooks/`, a `docker/`, `web_demo.py` and `web_demo_captioner.py`. That is the whole repository.
There is no library, no package manifest, no inference code and no training code. The primary language is recorded as Jupyter Notebook, which reflects that the cookbooks are notebooks, and the two Python files at the root are demo launchers rather than the model implementation.
That tells you what this repository is for. It is a landing page that points at weights hosted elsewhere, at notebooks that run somewhere else, and at two spaces where you can try the model without installing anything. The readme's own description of the cookbooks says they include actual execution logs and suggests you follow the quickstart first, download the model, install the inference environment, and then experiment locally.
There are no GitHub releases. The release that happened, on 22 September 2025 according to the news section, means weights on Hugging Face and ModelScope, not a tag in this repository.
Two demos at the root because there are two models
The root has `web_demo.py` and `web_demo_captioner.py`, two separate launchers rather than one with a flag. That split maps onto two different models named in the readme.
The main model is the omni-modal one, described as natively end-to-end and multilingual, taking text, images, audio and video and streaming responses in text and speech. The second is Qwen3-Omni-30B-A3B-Captioner, which the readme says is now open source and describes as a general purpose, highly detailed, low hallucination audio captioning model.
So a captioning task and a conversational task go through different launchers. If you only need to describe audio, the captioner path is the one the repository is organised around, and it is the model whose naming carries the parameter count and the active expert count.
Both demo spaces listed at the top are named Qwen3-Omni-Demo, one on Hugging Face and one on ModelScope, and the contents list carries both a Docker section and a local web UI section, so there are three ways to reach the same thing.
The architecture claim is a Thinker-Talker with two mechanisms behind it
The novel architecture bullet names a mixture of experts Thinker and Talker design with AuT pretraining, and separately a multi-codebook design that the readme says drives latency to a minimum.
Those are two different things doing two different jobs. The Thinker-Talker split with a mixture of experts is the representation side, which is where the strong general representations come from. The multi-codebook design is the output side, and it is the mechanism the readme credits for latency. Streaming speech at low latency is a token generation problem, and a codebook representation of audio is what makes it tractable, which is consistent with the model generating speech directly rather than routing through a separate text to speech stage.
The training description in the same section says early text-first pretraining is followed by mixed multimodal training, and that unimodal text and image performance does not regress. No regress is a specific claim and it is the kind that should be checked against your own text and image workload, since those are the two modalities that got the least new capability in this release.
The cookbooks table is the only usage documentation in the repository
Usage is documented as a table of notebooks grouped by category, and the first category is audio with six rows. Four are visible in the readme: speech recognition supporting multiple languages and long audio, speech translation covering speech-to-text and speech-to-speech, music analysis covering style, genre and rhythm, and sound analysis for sound effects and audio signals.
Each row links twice, once to the notebook in the repository and once to a Colab link, so every example can be run without a local GPU. That is a deliberate choice and it matches the shape of the repository, which has no install instructions of its own.
The pattern continues with the other categories named in the table, covering image, video and audio-visual work. Each row carries a one line description of what the notebook does, which means the capabilities of this model are documented as a set of worked examples rather than as a specification.
If you are deciding whether the model handles your task, this table is where the answer is. The readme gives no parameter names, no prompt format and no inference snippet outside these notebooks.
There is no inference command in the readme, only a quickstart section
The contents list has a QuickStart section with four subsections: model description and download, Transformers usage, vLLM usage, and DashScope API usage. The section body is not in the readme text that ships, so what each of those four routes asks of you is documented elsewhere.
What the readme does say about routing is worth noting. Two of the four paths are local and self-hosted, one through Transformers and one through vLLM, and one is a hosted API through DashScope with a help page linked at the top. Two demo spaces are offered as a fifth route, and the local web UI and Docker sections in the contents give two more.
So there are six ways in and the readme selects none of them. That is defensible for a model release where the inference stacks are moving fast and the notebooks are the maintained artefact, and it is also the reason the repository looks the way it does: a readme, two launchers, and notebooks that carry the working code.
The news section has two entries and both are from September 2025
The news list holds two lines. On 22 September 2025 the model was released, with a pointer to the blog. On 26 September 2025 the model reached top one on Hugging Face Trending.
So the announcement is two entries long and both fit inside five days, and the second of them is a popularity milestone rather than a technical one. The last commit to the default branch main is dated 23 April 2026, which is well after both news items.
The readme also carries an earlier statement about positioning: it presents Qwen3-Omni as the natively end-to-end multilingual omni-modal foundation models and points at a paper, a blog post, a Hugging Face collection, a ModelScope collection, cookbooks, an API page and a Discord invite, plus WeChat for Chinese speakers and two videos, one in English and one in Chinese, each behind a details element.
That link set is wide, which is normal for a model launch, and it means the repository itself is the least informative of the entry points.
Editorial conclusion
Qwen3-Omni is worth evaluating if you need one model that both hears and speaks, since the streaming speech output and the single shared namespace are what distinguish it from an ASR model feeding a text model. Read the benchmark claim carefully before quoting it, because the two figures in that sentence measure different things and neither comes with a comparison you can reproduce from the repository. Check the cookbooks for your modality rather than the headline, since the repository ships notebooks with execution logs and no install command. And confirm which checkpoint you are pulling, since a separate captioner model exists alongside the main one.
Frequently asked questions
Can Qwen3-Omni generate images?
The readme does not say so. It describes the model as processing text, images, audio and video as inputs and delivering real-time streaming responses in text and natural speech, so image generation is not among the listed outputs. The one model it names as generating anything is Qwen3-Omni-30B-A3B-Captioner, which produces audio captions.
Is Qwen 3 Omni open source?
The weights are published, under an Apache-2.0 licence in this repository, on Hugging Face and ModelScope, and the readme claims open-source state of the art on 32 of 36 audio and video benchmarks. The repository itself publishes no GitHub releases and contains no library or inference code, only a readme, two demo launchers, a docker directory and cookbook notebooks.
what is qwen3 omni
Qwen3-Omni is a natively end-to-end multilingual omni-modal foundation model from the Qwen team at Alibaba Cloud. It processes text, images, audio and video, streams responses in text and natural speech, supports 119 text languages, and uses a mixture of experts Thinker-Talker design with AuT pretraining plus a multi-codebook design for low latency.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/qwenlm-qwen3-omni)Star history chart for your README
[](https://hysenlabs.com/projects/qwenlm-qwen3-omni)Was this useful?