Ref MCP ships the transport its own page calls legacy, and pins its type check to a hook npm ignores
Helping coding agents never make mistakes working with public or private libraries without wasting the context window.
At a glance
- What is it?
- ref-tools/ref-tools-mcp is a Model Context Protocol server that gives a coding agent documentation search and page reads, filtering repeated results within a session and returning the most relevant 5k tokens of a page. The repository holds the stdio server while the page recommends the hosted streamable HTTP endpoint, the generated Dockerfile exposes a port the page never mentions, and the Inspector ships as a runtime dependency.
- Who is it for?
- Ref MCP makes a narrow and testable claim, which is a point in its favour: within one session it will not return a search result twice, and when it reads a page it decides which 5k tokens matter using what the agent already searched for. That is the mechanism to evaluate first, because it is the whole product.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 10 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
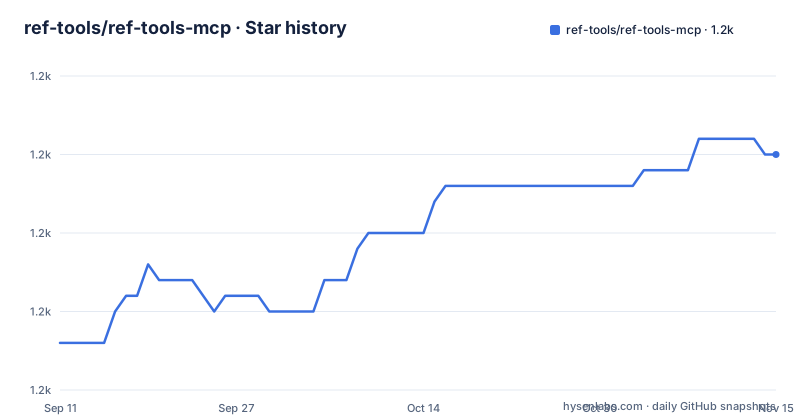
- ref-tools/ref-tools-mcp1,185 ★ · +12
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| ref-tools/ref-tools-mcp | 1.2k | 1.2k |
12 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository contains the transport the page calls legacy
There are two ways to run this server and the page ranks them. The streamable HTTP server is the recommended option; the local stdio server is labelled legacy. Then comes the sentence that decides the rest of the article: this repo contains the legacy stdio server.
So the configuration you get by cloning and building is the one the authors no longer lead with, and the recommended path is a hosted endpoint:
"Ref": {
  "type": "http",
  "url": "https://api.ref.tools/mcp?apiKey=YOUR_API_KEY"
}
The manifest does contain a start:http task that sets TRANSPORT=http on the built file, so the code can speak the newer transport too. Nothing in the page connects that task to a client configuration, which is the gap: a self-hosted http server is possible from this repository, and undocumented.
One configuration puts the key in the URL, the other in an environment variable
The two configuration snippets do not treat the credential the same way. The http form carries it as a query parameter on the endpoint URL, where it travels through whatever sits in front of the service and tends to land in access logs. The stdio form passes it as an environment variable to a local npx launch:
"Ref": {
  "command": "npx",
  "args": ["ref-tools-mcp@latest"],
  "env": {
    "REF_API_KEY": <sign up to get an api key>
  }
}
That second snippet is also not valid JSON as printed: the value is an angle-bracket placeholder where a quoted string belongs. Copying it into a config file produces a parse error rather than a working server. The one-click install links for both transports pass the entire configuration as a base64 blob in the link's query string, so the same choice of key handling is made before you see it.
Filtering is the product: no repeated results and a 5k token cap
Two mechanisms do all the work, and both are session-scoped. The first is result filtering: for repeated similar searches in a session, the server will never return repeated results, which lets an agent page further while also adjusting its prompt, instead of paging blindly through a ranked list.
The second is selective fetching. When reading a documentation page, it uses the agent's session search history to drop out less relevant sections and return the most relevant 5k tokens. The problem it is aimed at is stated plainly: a plain fetch() on a large documentation page can pull 20k or more tokens into context, most of which are irrelevant.
Both claims are scoped to a session, which is what makes them cheap and also what limits them. A fresh session has no history to filter against, so the first read of a large page is where the 5k cap does the most work and the search history does the least.
The n8n example ends mid URL, after a read costing 4,961 tokens
The page shows one short trajectory and one long one. The short one, a question about posting a comment through Figma's REST API, is a single search of 54 tokens followed by a single read of 385 tokens. That is the shape the product is selling.
The long one is an n8n question about when to use the merge node against the code node. It runs to eight calls, and the token counts vary by two orders of magnitude: one read returns 4,961 tokens, the next 138, another 80, and searches run 107, 126, 370 and 372. The last read is where the example stops, at a URL ending in output-other-nod. So the demonstration of context discipline ends with a truncated link, and it contains a read far above the 5k figure the feature section quotes. The page is candid elsewhere that this is early work, describing it as what has been implemented so far.
The cost argument is the page's own arithmetic, dated July 2025
The justification section gives two reasons, and the second is a worked example. Suppose an agent pulls in 10,000 tokens of documentation of which 4,000 are relevant and 6,000 are noise; at API pricing that 6k costs about $0.09 per step, and if one prompt takes 11 steps with Opus, the page says you have spent a dollar for no reason.
The first reason is a claim about models rather than money, and it carries its own date: it is described as well documented that, as of July 2025, models get dumber as more tokens go in, with a pointer to a video from the Chroma team. That is the research the page leans on, and the link is a video rather than a paper, so the underlying claim is one step further away than the page makes it sound.
One presentational detail worth noting: the section headings carry no restraint, running Tokens cost with three dollar signs and the per-step figure in capitals.
The Inspector ships as a runtime dependency of the published package
The manifest is short and worth reading closely. It declares three runtime dependencies: the MCP SDK, axios, and the MCP Inspector. The Inspector is a debugging tool, described on the page as a visual interface for testing and monitoring server interactions that you use during development, yet it sits in dependencies rather than devDependencies, so anyone who installs the published package installs it too.
The build is equally specific. TypeScript source at index.ts is bundled by esbuild into a CommonJS file at dist/index.cjs, from a package whose own type field is module, with a node shebang added as a banner and the output made executable by a small script that calls fs.chmodSync with mode 755 through node itself. The published files array contains only dist, and the bin entry points at the same built file.
So the artifact on npm is a single bundled CommonJS file, and its executable bit is set by a workaround that exists so the step also works on Windows.
The type check hangs off a hook name npm will not run
There is a script named pre-commit whose entire body is npm run check, and check is a TypeScript compile with no emit. If that ran on every commit, the type check would be automatic. It does not, because pre-commit is a git hook name rather than one of the lifecycle names npm runs by itself, and nothing in the repository wires it to a commit: there is no husky or lefthook configuration among the root files, and the manifest has no prepare script.
Two more things follow from the same reading. The repository publishes no GitHub releases and carries no changelog file, while the documented install runs the package at a floating tag, ref-tools-mcp at latest, so a fresh install is not pinned to the version the source tree is at. The manifest itself is at 3.0.3, which is only discoverable by reading the file.
A generated Dockerfile exposes 8080, which the page never mentions
The Dockerfile in this repository was generated by a registry, and its first line says so, pointing at the generator's own documentation. It is a two-stage Alpine build: the builder installs with a frozen lockfile and ignores scripts, then runs the build; the runtime stage installs production dependencies the same way, copies the built dist directory across, makes the entry executable, exposes port 8080 and runs node on the bundle.
Nothing in the page mentions port 8080, an exposed port, or how a client would be pointed at a container you built yourself. That connects back to the transport question: the repository can serve http, the Dockerfile makes that reachable, and the documentation covers neither.
The remaining root files are publishing metadata rather than code. There is a single TypeScript entry point, a manifest, a server definition, a registry configuration, an ignore file for bundle packaging, a Prettier config, and two images that appear to be listing artwork.
Editorial conclusion
Ref MCP makes a narrow and testable claim, which is a point in its favour: within one session it will not return a search result twice, and when it reads a page it decides which 5k tokens matter using what the agent already searched for. That is the mechanism to evaluate first, because it is the whole product. Two things to check before wiring it into an agent. First, the transport you actually install is not the one the page recommends, and the recommended one is a hosted endpoint that takes the API key in the URL query string, while the local server takes it in an environment variable. Second, the private-documentation claim depends entirely on that key, since the tool reaches repositories and PDFs on your behalf. Note also that the search examples on the page include one read of nearly five thousand tokens and a final URL that stops mid-word, so treat the demonstrations as illustrative rather than as measured behaviour.
Frequently asked questions
What is ref-tools-mcp?
A Model Context Protocol server that gives a coding agent or other AI tool access to documentation for APIs, services and libraries. It exposes two tools, ref_search_documentation for searching and ref_read_url for fetching a page and converting it to markdown, and it is MIT licensed and published to npm as ref-tools-mcp.
How does Ref MCP cut down context usage?
Two session-scoped mechanisms. For repeated similar searches it never returns repeated results, so an agent can page and adjust its prompt together. When reading a page it uses the session's search history to drop less relevant sections and returns the most relevant 5k tokens, against the 20k or more a plain fetch can pull from a large documentation page.
Which transport does ref-tools-mcp recommend?
The streamable HTTP server, configured against a hosted endpoint with the API key in the query string. The page calls the local stdio server legacy and states that this repository contains it, where the key is passed as a REF_API_KEY environment variable to an npx launch instead.
Can Ref MCP search private documentation?
Yes. The search tool is described as working against public documentation on the web or on github as well as private resources such as repositories and PDFs. The page also notes that for OpenAI clients the same two tools are exposed under different names, search and fetch.
How do I run ref-tools-mcp in development?
esbuild bundles the TypeScript entry point into a CommonJS bundle at dist/index.cjs. The scripts cover build, watch, inspect, dev, check and a start:http that sets TRANSPORT=http, and dev runs the watcher and the MCP Inspector together so you can watch and debug in one command.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ref-tools-ref-tools-mcp)Star history chart for your README
[](https://hysenlabs.com/projects/ref-tools-ref-tools-mcp)Was this useful?