Rivet Actors: keyed stateful processes with their own SQLite, scheduled by one Rust binary and a bucket
Rivet Actors are the primitive for stateful workloads. Built for AI agents, collaborative apps, and durable execution.
At a glance
- What is it?
- Rivet Actors puts long-lived, keyed processes with durable state inside the Node.js, Bun or Rust process you already run, and schedules them from a control plane that needs only object storage. The design is clear and the claims are bold, but the published numbers come from one setup and the 3.x line is days old.
- Who is it for?
- Rivet Actors fits teams building per-user, per-session or per-agent backends on Node.js, Bun or Rust who want state, realtime connections and scheduling attached to a key, and who can supply an object storage bucket for self-hosting. It is the wrong fit if your units of work need their own container images or a runtime outside those named in the README, or if you need a release line that has been stable for months, since v3.0.0 shipped on 2026-11-01.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
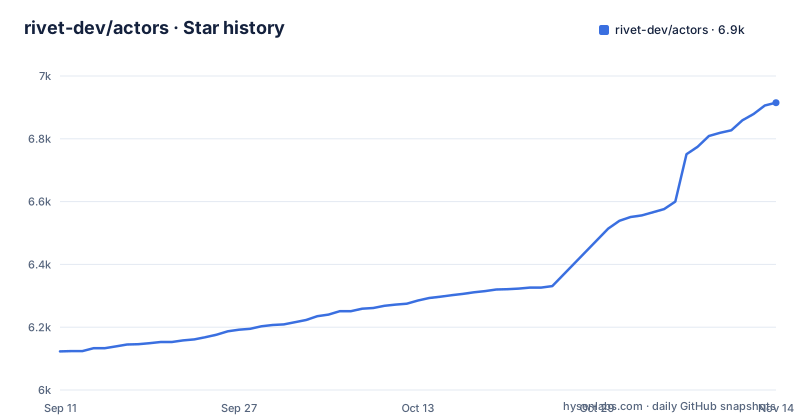
- rivet-dev/actors6,915 ★ · +792
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| rivet-dev/actors | 6.1k | 6.9k |
792 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
An Actor is a keyed process inside your own Node.js, Bun or Rust process
Rivet's unit of work is the Actor: a long-lived process with durable state, its own SQLite database, a queue, realtime connections and scheduling, addressed by a key. You create one per agent, per session, per user or per tenant. The defining choice is where it lives. An Actor runs inside a node process you already operate, on plain Node.js, Bun or Rust, rather than in a container or VM of its own, so there is no image pull and no container boot when one starts.
From the client side, an Actor is reached by key and then called like an object. This client example from the README connects to an Actor keyed agent-123, subscribes to its token events, and calls its chat action:
// Connect to an Actor
const agent = client.agent.getOrCreate("agent-123").connect();

// Listen for realtime events
agent.on("token", delta => process.stdout.write(delta));

// Call an action on the Actor
await agent.chat("how many r's in strawberry?");
getOrCreate means the caller never has to know whether the Actor already existed. Idle Actors write their state and unload, then come back on the next request, so a key can stay addressable for months without holding memory the whole time.
Per-Actor SQLite writes land on several control plane disks before they reach the bucket
Each Actor gets its own SQLite database and key-value storage. On the backend, the rivetkit package exposes actor() and db() from rivetkit/db, and the database block takes an onMigrate hook where you apply your schema, for example a CREATE TABLE IF NOT EXISTS messages statement. Actions then run SQL through c.db.execute.
Durability works in two stages. The control plane replicates each write to the disks of several instances and acknowledges it only after that replication, then moves data to object storage in the background. In the benchmark setup, every write was acknowledged by 2 of 3 control plane instances. The bucket is never on the write path, which is why the project calls the storage bottomless: capacity grows with the bucket, not with a volume attached to a pod.
The consequence for schema design is that each Actor's database is separate. A query across all users means touching many Actors, not running one SQL statement. The examples directory includes cross-actor-actions and per-tenant-database, which are the places to look before committing your data model to this shape.
The 6.9 ms cold start and 72 KB figures come from one Azure setup measured by the project
The headline numbers are specific: 6.92 ms p50 and 8.11 ms p99 for a cold start over 1,500 samples, 4.37 ms p50 and 6.80 ms p99 to wake an Actor asleep for at least 10 seconds over 1,200 samples, and 72.4 KB of memory per instance. A cold start here includes scheduling, storage creation and framework startup, measured from client send to full first reply.
Those figures were measured by the Rivet team on October 25, 2026, on Azure eastus2 across three availability zones, with three control plane instances on Standard_L8as_v5 machines with local NVMe, one per zone, and a node VM running Node.js 24. That is one configuration, and a favorable one: local NVMe on every control plane instance and three zones in a single region.
If your control plane runs on network-attached disks, in one zone, or far from your node processes, the published latency does not transfer automatically. The Kubernetes comparison in the same table (about 6 s cold start and about 200 MB per pod) is also the project's own framing, not an independent measurement. Run the kitchen-sink example's counter-latency script on your hardware before quoting any of these numbers internally.
Where Actors replace Kubernetes pods and where a pod is still the right unit
Rivet positions itself against Kubernetes directly: where Kubernetes schedules pods, Rivet schedules Actors. The difference in approach is the isolation boundary. A pod is a container with its own image, filesystem and resident memory, so it can run any language and any binary. An Actor is a lightweight process inside a node process you run, which is how a server that held hundreds of pods can hold hundreds of thousands of Actors, and how idle Actors drop to zero memory.
That trade cuts both ways. If your per-user unit is application logic written in TypeScript or Rust, the Actor model removes container overhead. If each unit needs a different system package, a different language runtime, or a container image someone else built, an Actor is not the abstraction for it. Rivet's answer for untrusted code is a separate Actor type, Sandboxes (agentOS), which gives code you did not write a filesystem, shell and network of its own. The other Actor types are Agents, Workflows that replay instead of starting over, and Dynamic Apps, which is marked preview.
Two ways in: the Rivet skills for coding agents, or a quickstart per runtime
The first starting point targets AI coding tools. This command adds the Rivet skills so an agent such as Claude Code, Cursor or Windsurf can generate examples or wire Rivet into an existing project:
npx skills add rivet-dev/skillsThe second is the quickstarts on rivet.dev, with separate guides for Node.js and Bun, React, Next.js, Rust and Effect. The repository holds client libraries in rivetkit-typescript, rivetkit-rust, rivetkit-python and rivetkit-swift, alongside AsyncAPI, JSON Schema and OpenAPI definitions, but the quickstart list on the README does not include Python or Swift. If those are your languages, check the docs site for their status before planning around them.
The examples directory is the most direct way to see real patterns: hello-world in plain, Rust and Effect versions, chat-room, collaborative-document and collaborative-document-ot, cursors, multiplayer-game, jwt-counter and jwt-better-auth for authentication, and per-tenant-database. Reading one of these end to end tells you more about the action and event model than the feature list.
Self-hosting the engine: the docker-run recipe points at a self-host path not visible at the repository root
Self-hosting is pitched as one Rust binary and a bucket, with no separate database and no message bus. Control plane instances are identical, run every service, and find each other through the bucket. You still need object storage you control, so a self-hosted deployment is never only a binary.
The justfile carries the container recipes. just docker-build builds the full engine image locally:
docker build -f docker/engine/Dockerfile --target engine-full -t rivetdev/engine:local .The docker-run and docker-stop recipes call docker compose with the file self-host/control-plane/docker-compose/docker-compose.yml. The repository's top-level entries include docker/, engine/ and docs/, but no self-host/ directory. Before you rely on just docker-run, confirm that compose file exists in the checkout you are using, or locate the current self-hosting instructions on rivet.dev. A recipe that points at a missing path fails at the first command, which is a poor moment to discover it during an evaluation.
v3.0.0 landed on 2026-11-01, with two 3.0.1 previews tagged two days later
The release history is very fresh. v3.0.0 was tagged on 2026-11-01, and v3.0.1-preview.1 and v3.0.1-preview.2 both followed on 2026-11-03. The last push was on 2026-11-01. A major version with patch previews within 48 hours tells you the 3.x line is still settling, and that pinning an exact version is safer than a range. The changelog lives at rivet.dev/changelog and in CHANGELOG.md.
The repository is a mixed Rust and TypeScript monorepo. Cargo.toml defines a workspace of engine packages such as guard, epoxy, sqlite-embedded and the depot packages, while package.json runs pnpm 10.13.1 with Turborepo and requires Node.js 20 or newer. Two storage dependencies, SlateDB and object_store, are vendored and regenerated from a pinned release plus a patch series, and just slatedb-check fails if the committed source drifts. Contributors pay for that with an extra step whenever those dependencies move. The code is licensed Apache-2.0, which permits commercial use and modification under its notice and patent terms.
Editorial conclusion
Rivet Actors fits teams building per-user, per-session or per-agent backends on Node.js, Bun or Rust who want state, realtime connections and scheduling attached to a key, and who can supply an object storage bucket for self-hosting. It is the wrong fit if your units of work need their own container images or a runtime outside those named in the README, or if you need a release line that has been stable for months, since v3.0.0 shipped on 2026-11-01. Before adopting, reproduce the cold start and wake figures on your own hardware rather than relying on the Azure eastus2 measurements, and check that the self-host compose path the justfile references exists in the tag you deploy.
Frequently asked questions
Which runtimes can Rivet Actors run on?
Rivet Actors run on plain Node.js, Bun or Rust, inside a node process you already run. The quickstarts cover Node.js and Bun, React, Next.js, Rust and Effect.
Does self-hosting Rivet Actors require a database or message bus?
No. Self-hosting needs one Rust binary and an object storage bucket, and control plane instances find each other through that bucket.
What happens to an idle Rivet Actor?
An idle Actor writes its state and unloads, using no memory while it hibernates. The next request wakes it, which the project measured at 4.37 ms p50 on its Azure benchmark setup.
What license is Rivet Actors released under?
Rivet Actors is open source under the Apache-2.0 license and can be self-hosted.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rivet-dev-actors)Star history chart for your README
[](https://hysenlabs.com/projects/rivet-dev-actors)Was this useful?