LingBot-Vision ships a loader and a PCA script, and its ModelScope table contradicts its own download line
Self-supervised learning for spatial perception
At a glance
- What is it?
- A family of self-supervised vision transformer backbones for dense spatial tasks, released as backbone-only checkpoints with one large teacher and three distilled students. The published package is inference and visualisation utilities rather than training code, the Python entry point downloads weights automatically while the demo script does not, and the model zoo lists four mirrors of which one is described as not yet available.
- Who is it for?
- Adopt the large backbone if you need dense features, since that is the one the project marks recommended for strong features at practical inference cost, and use the giant one only as a teacher. Three things to settle first.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 129 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
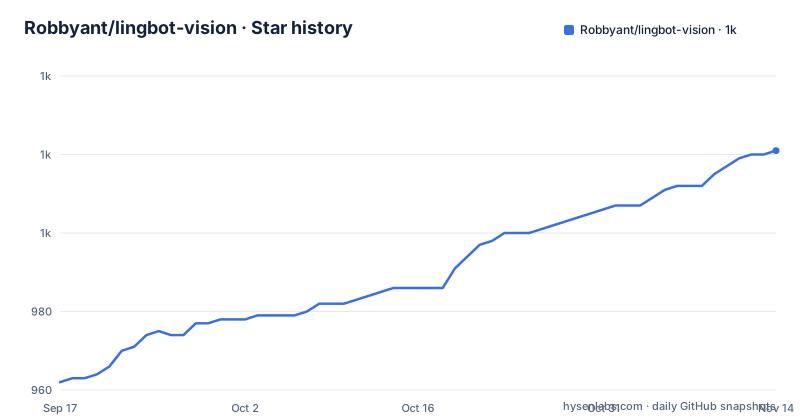
- Robbyant/lingbot-vision1,021 ★ · +59
| Repository | 2026-09-17 | 2026-11-14 |
|---|---|---|
| Robbyant/lingbot-vision | 962 | 1k |
59 Stars in the last 58 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The published package is a loader and a visualisation script
What you install is narrower than what the project is, and the manifest says so.
The distribution is version 0.1.0 and its description reads as inference and PCA visualisation utilities for the backbones. The dependency list is seven packages and no training framework beyond the tensor library itself.
torch
torchvision
numpy
opencv-python-headless
pillow
omegaconf
huggingface_hub
Read the list and the roles are clear. The model hub client is there to fetch checkpoints, the config library reads the packaged YAML files, the headless build of the image library handles input, and the rest is the tensor stack. There is no distributed training library, no dataset pipeline and no optimiser configuration, which is consistent with the description and with the model zoo text saying that full training and evaluation details are covered in the technical report.
So the repository is the inference half of a project whose other half is a paper. That is a normal split for a released backbone, and it is worth knowing before you plan around it, because the training code is not something you can pip install from here.
The same seven dependencies appear in a separate requirements file, unversioned in both places, so the two files have to be kept in step by hand. The package configuration finds one package by name prefix and includes the config directory as package data, which is what lets a model config travel with the installed code rather than needing to be fetched separately.
One entry point downloads the weights and the other expects a path
There are two ways to run the same model, and they disagree about who supplies the checkpoint.
The Python route downloads it. The model is fetched automatically from the model hub on first use, with the loader taking a variant name, a device and a dtype, and returning both the backbone and its embedding dimension. A local directory or an explicit model repository can be passed instead, so an offline path exists for the same function.
The script route does not. The PCA demo takes a checkpoint path as an argument, and the page's instruction is to download a backbone checkpoint first.
./scripts/run_pca_demo.sh \
  --config-file lingbot_vision/configs/lbot_vision_vitl.yaml \
  --ckpt /path/to/model.pt \
  --input examples/example.png \
  --out outputs/pca_demo \
  --size 512 \
  --mode square \
  --dtype bf16
So the two paths are not equivalent in setup. One is a library call that fetches what it needs; the other is a shell script that refuses to guess, which is the right choice for a reproducibility script and the wrong one if you expected the same convenience.
The demo's argument list is otherwise well specified. It takes the model config, the checkpoint, an input image, an output directory, a size, a resize mode and a dtype. Images are read as RGB, resized according to the size and mode arguments, aligned to the model's patch size, and normalized with ImageNet statistics. The top three principal components of the patch tokens are mapped to RGB, and the script writes both a plain PCA image and a side by side panel.
There is a CPU route, named explicitly rather than inferred: a dtype and device pair of fp32 and cpu.
One more detail connects the two routes. The Python loader takes its configuration from a packaged config directory automatically, while the script takes the config as a path, and the path in the example is named for the large variant.
The model zoo lists four mirrors, and the download line says one is not there yet
The model zoo table gives every backbone two weight links, and the instructions below it do not agree with one of them.
Each of the four backbones has a link to a model hub repository and a link to a mirror repository, plus a table of architectures, embedding widths and short descriptions of what each is for.
Then the PCA demo section says to download a checkpoint from the primary host, or from the mirror once available. The phrase once available says the mirror does not have the files yet, while the table above lists four mirror links as if it does.
That is a small contradiction, and it is the kind that costs a download attempt rather than anything worse. But it is also the only place on the page where availability is stated in two incompatible ways, so it is the first thing to check if you were planning to pull from the second host.
The rest of the table is consistent and worth reading as the sizing guide it is. The widest model is the teacher, at roughly 1.1 billion parameters with an embedding width of 1536, described as offering the highest quality dense features and specified with a particular feed-forward variant, rotary position embeddings in single precision, and four register tokens. The one marked as recommended is the next size down, at 1024, described as strong features at practical inference cost, and it is the only row carrying a marker in its name.
Then a balanced one at 768, described as balanced inference cost, and a small one at 384, described as lightweight demos and downstream use.
The distribution is uneven, and worth noting before you plan around a width. The smallest is half the base, the base is three quarters of the recommended one, and the recommended one is two thirds of the teacher.
One teacher and three students, with the architecture detail only on the teacher
The zoo section states the training relationship in a single sentence, and it changes how you read the table.
A large model at the giant scale is trained as the teacher, at roughly 1.1 billion parameters. The three smaller backbones, at the large, base and small scales, are distilled from it for inference and downstream use.
So the giant is not a bigger student. It is the thing the other three were derived from, and its row in the table is a description of a model you cannot use as a drop-in student in the same way.
The architecture detail is also uneven. The teacher row names its feed-forward variant, its rotary embedding precision and its register token count. The other three rows give only a patch size and the statement that they were distilled. So if you are choosing between the recommended and the base model, the page tells you their widths and their intended uses and nothing about how their internals differ.
Every released checkpoint is described as backbone-only, and the file name is the same in every repository. That is an important constraint stated up front: there is no classification head, no detection head and no depth head in what is published. Each of the five listed downstream capabilities is therefore a readout somebody else has to attach, and the page describes them in the language of exactly that.
Dense feature visualisation is presented as principal component maps of the frozen patch tokens. Depth estimation is described as exposing spatial structure to lightweight dense readouts. Semantic segmentation is claimed from features that align region transitions with object contours. Video object segmentation is described as training-free token matching and label propagation on frozen features. And depth completion is the one place where the backbone is used as initialisation for a separate named system.
The quick start snippet stops partway through an argument list
The Python example is short, and it ends before it finishes the line that matters most.
It opens with three imports, then sets a device by checking for CUDA and a dtype by checking the same condition, choosing half precision on a GPU and single precision otherwise. That pair is the right pattern for a project whose recommended requirement is a CUDA-capable GPU but whose demo documents a CPU route.
Then it loads a backbone by variant name, and the comment names the exact repository the file is downloaded from. The example picks the smallest variant, and the text explains why: it is a lightweight smoke run, while the larger one is the default when the argument is omitted and the largest is available as well.
The image loading call takes a path, a size, the backbone's own patch size and a resize mode, and returns three values of which the example uses one.
The line after that is where the snippet stops. The call that extracts the patch tokens is given the backbone and the normalised image, and the argument list is cut off partway through the device argument. So the final call in the quick start is not a complete example of the call that produces the tensors the rest of the text describes.
What the text does state is the output shape: the patch tokens are a three dimensional tensor of batch, patch count and channel, where the patch count is the product of the two grid dimensions. That is the contract a readout has to target, and it is the one piece of interface information a downstream user needs most.
The default behaviour is also stated, and it is worth noticing that the example and the default disagree. The example asks for the small model, the default is the large one, and a fourth option is the largest.
A depth model was rebuilt by swapping the encoder and scaling the data fifty times
The second half of the project is a demonstration rather than a release, and its numbers are two.
The depth system is described as improving substantially over the previous version and over other systems, with the change being two things: the encoder is replaced with the backbone at two of the published scales, and a curated colour plus depth training corpus is scaled from three million samples to one hundred and fifty million.
So the architecture contribution is one substitution and the data contribution is a fifty times increase. There are no accuracy numbers on the page, and the gains are referred to a technical report rather than given here, which is the single largest gap between the claims and the evidence in this project.
The failure case is the interesting part, and it is described concretely. Raw sensor depth goes missing on difficult surfaces, with three named examples: window panes, glass balustrades and reflective floors. The system is shown completing those regions as stable, contiguous surfaces across frames, and the demonstration groups show an input image, the raw sensor depth, the refined depth and refined point clouds.
That is the claim to hold in mind for the whole family. A backbone pretrained with a boundary-centric objective is being asked to make object contours legible, and the downstream system it is plugged into is one where the hard pixels are exactly the ones where a sensor sees glass and a model has to guess. The connection between the two halves is coherent, and the evidence for it is a set of images plus a paper.
Two licence files, the paper in the tree, and one example image
The repository is small and the layout is worth stating because it tells you what to look for.
The top-level entries are a gitignore, two legal files, the readme, an assets directory, an examples directory, the Python package, the paper as a PDF, the manifest, a requirements file and a scripts directory.
Two legal files sit side by side, one of them named with the standard spelling and one with a different one. The manifest declares Apache-2.0 in text form, and the page links the licence from its badge row, so the applicable terms are stated. Having a second file with a different name is unusual enough to be worth reading before you assume it is a duplicate.
The paper is committed at the root rather than linked only from a preprint server, and the header links both. The same row also links the project page, the model collection on the primary hub, and the collection on the mirror.
The examples directory contains exactly one file, a single image. So the quick start's only sample input is one picture, and the visualisation outputs referenced in the demo instructions are not committed.
There are no GitHub releases, so the four backbones are versioned as tags on a hub rather than as releases here. The manifest version is 0.1.0 and the repository is not archived, with the last push to the default branch recorded as 2026-07-08.
The requirements are modest and stated in one line: Python 3.10 or newer, a tensor library at version 2.0 or newer, and a CUDA-capable GPU, described as recommended for large-model inference rather than mandatory.
Editorial conclusion
Adopt the large backbone if you need dense features, since that is the one the project marks recommended for strong features at practical inference cost, and use the giant one only as a teacher. Three things to settle first. The distributed package is a loader and a visualisation script, so if you intend to pretrain your own backbone, everything you need is in the technical report rather than in the repository. The two entry points fetch weights differently, one automatically and one from a path you have to supply, so pick the one matching your setup. And the mirror listed in the model zoo is described elsewhere on the same page as not yet available, so download from the primary host and do not plan around the second.
Frequently asked questions
What is LingBot-Vision and what do I get from the repository?
A family of self-supervised vision transformer backbones for dense spatial perception, published as backbone-only checkpoints, so no task head is included. The published package is version 0.1.0 and describes itself as inference and PCA visualisation utilities, with full training and evaluation details in the technical report rather than in the code.
Which LingBot-Vision backbone should I use?
The page marks the large backbone as recommended, describing it as strong features at practical inference cost, with an embedding width of 1024. The giant at 1536 is the roughly 1.1 billion parameter teacher the others were distilled from, the base at 768 is for balanced cost, and the small at 384 is for lightweight demos and downstream use.
How do I load a LingBot-Vision backbone in Python?
Call the pretrained loader with a variant name of giant, large, base or small, plus a device and a dtype, and it returns the backbone and its embedding width. Weights download automatically from the model hub on first use, and you can pass a local directory or an explicit model repository instead. Omitting the variant defaults to large.
What shape do LingBot-Vision patch tokens have?
The patch tokens are a three dimensional tensor of batch, patch count and channel, where the patch count is the product of the two patch grid dimensions. They come from a call that takes the backbone and a normalised image, and image loading takes a size, the backbone's patch size and a resize mode.
Can LingBot-Vision run without a GPU?
Yes. The requirements call a CUDA-capable GPU recommended rather than mandatory, the Python example selects a single precision dtype when CUDA is unavailable, and the PCA demo documents a CPU-only path using an fp32 dtype and the cpu device argument.
How were the smaller LingBot-Vision backbones produced?
A giant-scale model of roughly 1.1 billion parameters was trained as a teacher, and the large, base and small backbones were distilled from it for inference and downstream use. Full training and evaluation details are in the technical report rather than in the repository.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/robbyant-lingbot-vision)Star history chart for your README
[](https://hysenlabs.com/projects/robbyant-lingbot-vision)Was this useful?