numpy-100 and the generator that owns its markdown
100 numpy exercises (with solutions)
At a glance
- What is it?
- numpy-100 is 100 numpy exercises with hints and solutions, stored as keyed text and rendered into markdown and notebooks by generators.py. The tradeoff is clear: every published file is build output, and solutions sit next to the questions inside the same clone.
- Who is it for?
- numpy-100 works well as a reference list for someone who already knows some numpy and as raw material for someone teaching it, and it works poorly as a standalone curriculum or as a base to fork, because difficulty is unordered, per-exercise provenance is unrecorded, and the two releases on record are from 2016.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 23 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
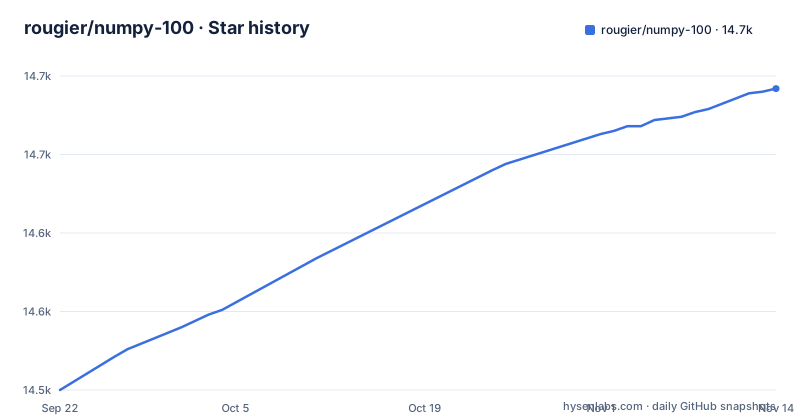
Star history
- rougier/numpy-10014,692 ★ · +192
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| rougier/numpy-100 | 14.5k | 14.7k |
192 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The markdown and the notebook are build output, not source
Nothing in this repository is authored directly in the format most people read. The exercise text lives in source/exercises.ktx, and generators.py is what turns that source into 100_Numpy_exercises.md and 100_Numpy_exercises.ipynb. The instruction for changing content is correspondingly narrow: edit the text in the source, then rerun the generator, rather than opening the markdown in an editor. That ordering has a consequence for anyone who skips it. A fix typed into the markdown is not part of the source data, and the next generator run writes over it. The same mechanism produces the hints and solutions variants, so one content change reaches every published form at once instead of drifting between four files.
ktx keeps prose indexed by keys, and the schema lives in the generator
The source format is named as the keyed text format, ktx, described as a minimal human readable key-values store for text, markdown or other kinds of text, indexed by keys. Minimal and human readable are the operative words: the store holds prose, not structure. There is no separate database and no metadata layer recording difficulty or topic per exercise, and the README does not document the key layout generators.py expects. So the questions a new contributor really has, which key holds the statement, which key holds the solution, how exercises are ordered, get answered by reading the generator and the source file rather than by a specification. Anyone automating against this repository has to match the generator's expectations directly.
Solutions ship beside the questions as four markdown permutations
The repository ships the same problem set in four markdown permutations, and the filenames carry the whole difference: 100_Numpy_exercises.md, 100_Numpy_exercises_with_hints.md, 100_Numpy_exercises_with_hints_with_solutions.md, and 100_Numpy_exercises_with_solutions.md. Each exists because the generator emits it from the same source data, so a reader can choose how much help to reveal. Two consequences follow. The answers sit in the same tree a student clones, one filename away from the bare problems, which means self-discipline rather than tooling keeps them closed. And with four near-identical files next to 100_Numpy_exercises.ipynb and 100_Numpy_random.ipynb, picking the wrong one is easy, because the filename is the only signal about what a reader will actually see.
Regenerating needs mdutils and nbformat, with nothing pinned
Readers who only work through the exercises need nothing installed. Contributors who change them need exactly what requirements.txt names: numpy, mdutils, and nbformat. That trio describes the shape of the pipeline. numpy serves the exercises, mdutils handles the markdown side, nbformat handles the notebook side. None of the three carries a version constraint, so the files you regenerate depend on whichever builds happen to be installed rather than on a recorded environment. If you send a fix here, expect to regenerate locally and diff the result, because the maintainer's exact output cannot be reproduced from the recorded dependencies alone.
The browser path depends on Binder and states no runtime
The first action offered is a Binder link that opens 100_Numpy_exercises.ipynb in a hosted environment, so a reader can run exercises without installing python locally. The cost of that route is that it depends on a remote service rebuilding the notebook, and the URL is pinned to one notebook path inside the repository. The offline route is the markdown file, which needs no service and no interpreter. Neither route states which runtime the problems expect. The repository carries a runtime.txt at the top level, but the README does not name a python version or a numpy version the exercises were written against, and requirements.txt pins none either. If you plan to work through these locally, you are choosing an unpinned environment rather than the one the published files were generated in.
Two releases in 2016, a push in 2026, and an undocumented initialise.py
Version 1.0 was published on 2016-07-16 and 1.1 on 2016-08-27, and those are the only two releases on record. The repository is not archived, and the default branch master took a push on 2026-10-23, so work continued long after the last tag without a release carrying it. Anything regenerated on master, content or output, is therefore unreleased, and a clone at a tag gives you the 2016 state. The top-level entries also include initialise.py, a file the README never mentions. Only generators.py is explained, so initialise.py has no documented role, no documented invocation, and no documented place in the workflow. Treat the script layout as something to verify by reading it rather than assuming the one documented generator covers everything.
Assembled from mailing lists and Stack Overflow, with no attribution map
The exercises are collected rather than invented wholesale. The stated sources are the numpy mailing list, Stack Overflow, and numpy documentation, plus problems the author wrote to reach the count of 100. That mixture suits a quick reference and complicates coursework: there is no documented ordering by difficulty, no notation introduced once and reused across problems, and no per-exercise record of origin. A teacher reusing these as a syllabus inherits whatever level each question happened to be written at. The MIT license covers the assembled collection, and the README documents no per-exercise attribution, so anyone redistributing a subset has to trace where each problem came from on their own.
Deeper material lives in a book and a Julia port, not in this tree
When a hundred problems stop being enough depth, the repository does not expand, it points outward. Readers are sent to From Python to NumPy for extended exercises, and a variant in another language is listed, 100 Julia Exercises by RoyiAvital. Both signals are useful and both cost something. The book is a separate text with its own structure, and the Julia port is a separate repository maintained by someone else, so its numbering and difficulty need not line up with the markdown files here. If you need a curriculum rather than a reference list, most of what you actually require lives outside this repository.
Editorial conclusion
numpy-100 works well as a reference list for someone who already knows some numpy and as raw material for someone teaching it, and it works poorly as a standalone curriculum or as a base to fork, because difficulty is unordered, per-exercise provenance is unrecorded, and the two releases on record are from 2016. Before you build on it, read source/exercises.ktx and generators.py to see what the generator assumes, check whether initialise.py belongs in the workflow nobody documented, and expect to regenerate with unpinned dependencies.
Frequently asked questions
Can you provide me with 100 NumPy exercises?
The repository ships them as 100_Numpy_exercises.md and 100_Numpy_exercises.ipynb, with hints and solutions variants alongside, all generated from source/exercises.ktx by generators.py and runnable through the Binder link.
What is NumPy used for?
This repository does not answer that. It holds 100 numpy exercises with solutions, gathered from the numpy mailing list, Stack Overflow, and numpy documentation, and its stated purpose is a quick reference for old and new users plus material for teaching.
Can I learn NumPy in a day?
No timing claim appears anywhere in the repository. The goal stated is a quick reference for both old and new users and a set of exercises for teachers, with extended exercises pushed into the separate book From Python to NumPy.
Can I learn NumPy in 10 minutes?
The repository makes no promise about duration. It offers 100 problems in four markdown variants and a notebook runnable on Binder, and it documents neither a difficulty progression across the 100 problems nor a time budget for working through them.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rougier-numpy-100)Star history chart for your README
[](https://hysenlabs.com/projects/rougier-numpy-100)Was this useful?