tinygrad: a training loop that is also a compiler, and rules that close pull requests
You like pytorch? You like micrograd? You love tinygrad. Neural networks As it turns out, 90% of what you need for neural networks are a decent autograd/tensor library.
At a glance
- What is it?
- tinygrad is an end-to-end deep learning stack in Python: a tensor library with autograd, an intermediate representation and compiler that fuses and lowers kernels, JIT graph execution, and the nn, optim and datasets pieces needed to train. Its dependencies list is empty, its accelerator contract is about twenty-five low level ops, and its contributing guidelines are unusually explicit about the kinds of pull requests that will be closed without review.
- Who is it for?
- Use tinygrad if you want to read a whole deep learning stack end to end, if you are adding a hardware backend and can live inside a roughly twenty-five operation contract, or if you are deliberately looking for a counterexample to how PyTorch is organised. Evaluate its pre-1.0 stability and test your workload before production use.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
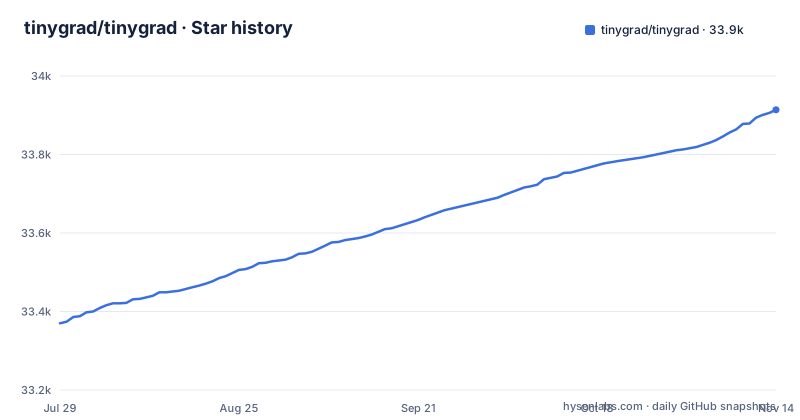
- tinygrad/tinygrad33,914 ★ · +544
| Repository | 2026-07-29 | 2026-11-14 |
|---|---|---|
| tinygrad/tinygrad | 33.4k | 33.9k |
544 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four layers, and the compiler is the one the README sells
The stack is described as four things. A tensor library with autograd. An intermediate representation and compiler that fuse and lower kernels. JIT and graph execution. And nn, optim and datasets for real training.
That ordering is the argument. A framework whose headline is a tensor API is competing on ergonomics, and the comparison section says that is where it matches PyTorch: a similar eager Tensor API, autograd, optim, basic datasets and layers, and familiar training loops. The stated difference is that the entire compiler and intermediate representation are visible and hackable, which is not a claim about speed but about what you can read.
The stated inspirations name the same split. PyTorch for ergonomics, JAX for functional transforms and IR-based automatic differentiation, and TVM for scheduling and code generation, while the goal is to stay intentionally tiny and hackable. So the tensor layer is deliberately familiar and the layers under it are the point of the project.
Laziness is demonstrated with a DEBUG level and a one-line matmul
The way the README demonstrates the fusion claim is a single command. It asks you to try a matmul, and to see that despite the way the code reads, it is fused into one kernel by the power of laziness:
DEBUG=3 python3 -c "from tinygrad import Tensor;
N = 1024; a, b = Tensor.empty(N, N), Tensor.empty(N, N);
(a.reshape(N, 1, N) * b.T.reshape(1, N, N)).sum(axis=2).realize()"
The construct is the point. Three separate operations written as three expressions, with transposes and reshapes in between, and one call to realize at the end. An eager framework would execute them in order. Here nothing runs until realize, and the compiler sees the whole thing and decides it is a single kernel. Raising the environment variable to 4 shows the generated code instead.
This is the most useful thing in the README for judging the project, because it tells you where the complexity lives. The API is a thin eager-looking surface over a compiler that is doing the interesting work, and the debug switch is how you get from one to the other.
Eight accelerators behind roughly twenty-five low level operations
The supported hardware list is eight entries, each with a file path: OpenCL, CPU, Metal, CUDA, AMD, NV, QCOM and WebGPU. The claim that follows is that adding another is easy, because your accelerator of choice only needs to support a total of about twenty-five low level operations.
That number is the whole design constraint. It is a small enough surface that a backend is a mapping from primitive operations onto whatever the hardware provides, which is why the list can span several GPU APIs, a CPU and a browser API (WebGPU). It also means the contract is narrow enough that a new backend is a bounded piece of work rather than an open-ended one.
To find out what tinygrad picked for your machine, the README gives a command to print the default device. The naming is worth noting as well: the backend files live in tinygrad/runtime with an ops_ prefix per device, which is a readable convention for anyone auditing what a backend actually implements.
The dependency list is empty and the install is from source
The manifest declares a dependency list of nothing. There is no NumPy, no PyTorch, nothing pulled in at install time, and the optional extras exist separately for linting, testing and specific backends, with the arm and triton extras commented out.
Installation follows from that. The current recommended way is from source, which is a clone, a change into the directory, and an editable install. There is a second route for people who want the tip of the default branch, installing straight from the git URL, but the recommended path is the first one.
In the testing extras NumPy and a pinned PyTorch appear for the test suite rather than for the library.
The version is 0.14.0 and the guidance calls the library pre-1.0
The manifest version is 0.14.0, matching the most recent release tag, and the project requires Python 3.11 or newer. The author field names one person, and the README points at a company as the maintainer.
The clearest statement of maturity is in the contributing section rather than the header. It says this library is not 1.0 yet, so if you stumble upon a bug, fix it, write a test and submit a pull request, that is valuable work. Bug fixes with a regression test are described as great, cash bounties are offered for certain improvements, and features are listed last..
So the ordering of what the project wants from a contributor is explicit: bug fixes first, then bounties, then features.
The contribution rules name five things that get a pull request closed
The contributing section opens with a list of refusals. No code golf, because while a low line count is a guiding light, anything that looks like golfing will be closed, since the true goal is reducing complexity and increasing readability. Documentation and whitespace changes will be closed unless you are a well-known contributor, on the grounds that the people writing the docs should be those who know the codebase best. Anything claimed as a speedup must be benchmarked, with maintainability and readability as the tradeoff to weigh. Code outside the core tinygrad folder is described as not well tested, so unless it is broken you should not be changing it. And a pull request that looks complex, is a big diff or adds many lines will not be reviewed, with the advice to break it into smaller individually clear wins, often a prerequisite refactor before new functionality.
There is also a paragraph about AI that is unusually blunt. A new contributor submitting something that looks like it was written by an AI will have it closed without feedback and may be banned. Anyone who used AI is asked to disclose what they used it for.
The practical effect is that the README is a filter as much as a description. Reading it tells you what shape of contribution has a chance, which for a project of this size is a large part of what you need to know.
The package list is the architecture, and it includes an autogen tree
The manifest enumerates the shipped subpackages explicitly, and the list reads as a map of the system. There is a codegen tree with several stages in its name, an engine, a schedule, a uop module, a viz package, a renderer with vendor-specific subpackages, a mixin, and a runtime.
The runtime tree is the part worth stopping on. Alongside the per-accelerator operation modules there are autogen subpackages for AMD, with separate directories named rdna3, rdna4 and cdna, plus a support tree with subpackages for the same vendor, for RDMA, and for NV. Generated code shipped in the package, rather than generated at build time, with package data declared for it.
Two more entries are telling. There is an llm subpackage that ships a chat interface as package data, and a viz package that ships an HTML file, assets and JavaScript. So a deep learning library in this repository also contains a chat front end and a visualiser, both as static files inside the distribution.
Editorial conclusion
Use tinygrad if you want to read a whole deep learning stack end to end, if you are adding a hardware backend and can live inside a roughly twenty-five operation contract, or if you are deliberately looking for a counterexample to how PyTorch is organised. Evaluate its pre-1.0 stability and test your workload before production use. Before you clone it: the README documents source installation and installation from master; pin a tested commit when reproducibility matters; expect the compiler to be the part you read, not the tensor API; and read the contributing section before opening a pull request, because documentation changes from unknown contributors and unbenchmarked speed claims are closed outright.
Frequently asked questions
What does tinygrad do?
It is an end-to-end deep learning stack with four parts: a tensor library with autograd, an intermediate representation and compiler that fuse and lower kernels, JIT and graph execution, and nn, optim and datasets for real training. The design bet is that the compiler and IR are readable and modifiable, which the README states as the difference from PyTorch rather than a speed claim.
How does tinygrad compare to PyTorch?
The README compares it to PyTorch, JAX and TVM separately. Against PyTorch it matches the eager Tensor API, autograd, optim and basic datasets, so you can write familiar training loops, and differs in that the compiler and IR are visible. Against JAX it has IR-based autodiff and function-level JIT, but fewer functional transforms, with no full vmap or pmap yet. Against TVM it has multiple lowering passes, scheduling and a search over kernels, and also ships the front-end framework.
how to install tinygrad
The recommended way is from source: clone github.com/tinygrad/tinygrad, change into the tinygrad directory, and run `python3 -m pip install -e .`. There is also a direct route that installs straight from the git URL if you want the tip of the default branch. The project requires Python 3.11 or newer, and the manifest declares no runtime dependencies at all.
Who made tinygrad?
The manifest names a single author, George Hotz, and the README says the project is maintained by a company called tiny corp. The repository records releases as tinygrad versions, the most recent being 0.14.0, and the project publishes cash bounties for certain improvements through a linked spreadsheet.
is tinygrad faster than pytorch
The README makes no speed claim in its comparison with PyTorch. What it claims is familiarity of the API and that the compiler and IR are visible and hackable. The project does publish an example, beautiful_mnist.py, described as reaching 98 percent in about five seconds, and its contributing rules state that any claim of a speedup has to be benchmarked against the tradeoff with maintainability.
What is a tinybox used for?
The accelerators section of the README does not mention a tinybox. It lists eight supported accelerators, OpenCL, CPU, Metal, CUDA, AMD, NV, QCOM and WebGPU, each with a file in the runtime directory, and states that your accelerator of choice only needs to support about twenty-five low level operations. A command is given for printing the default device on your machine.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tinygrad-tinygrad)Star history chart for your README
[](https://hysenlabs.com/projects/tinygrad-tinygrad)Was this useful?