XGen is three 7B checkpoints and one 262 word page
Salesforce open-source LLMs with 8k sequence length.
At a glance
- What is it?
- XGen is the Salesforce AI Research release for a 7B model family built around long sequence modelling, published as HuggingFace checkpoints with a research-only ethics notice. What the repository gives you is weights, a pinned transformers version and one sample; what it does not give you is training code, data or a dependency set that matches the sample.
- Who is it for?
- XGen is a reference release, not a product surface. Take it if you want to study or reproduce long sequence modelling at 7B, or need one specific checkpoint that the current model hubs still host, and read the pinned transformers version as a museum piece rather than a dependency you would install today.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 166 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
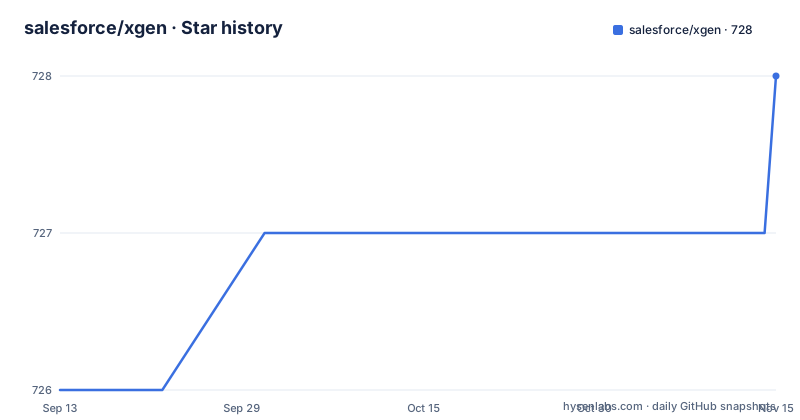
- salesforce/xgen728 ★ · +2
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| salesforce/xgen | 726 | 728 |
2 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three checkpoints at 7B, and the third one is spelled differently
The family is smaller than the word family suggests. Every checkpoint is 7B. What varies is context length and tuning: `XGen-7B-4K-Base` supports 4K sequence length, `XGen-7B-8K-Base` supports 8K, and `XGen-7B-8k-Inst` is the instruction-finetuned one, marked in the README as for research purpose only. Two details are worth noticing before you start typing model ids. The instruction-tuned name uses a lowercase k where both base names use an uppercase K, so the string you paste into `from_pretrained` is not a consistent transformation of the other two. And the repository description advertises 8k sequence length while a 4K checkpoint ships alongside it, so the headline number describes one member of the set rather than the release.
Model cards live on the HuggingFace Hub, not in this repository. The only research write-up named here is the paper the release accompanies, Long Sequence Modeling with XGen: A 7B LLM Trained on 8K Input Sequence Length, from 2023.
The tokenizer is tiktoken, and trust_remote_code is passed for it only
Tokenization is delegated to the OpenAI Tiktoken package rather than to a tokenizer file inside the repository, and the README's only install command is the one line that puts it in place:
pip install tiktokenThe sample then loads the tokenizer with `trust_remote_code=True` while the model load on the next line does not pass that flag. The asymmetry is real: the tokenizer path is allowed to fetch and execute code from the Hub repository, the model path is not, so a deployment that pins one and not the other has two different trust decisions to reason about. Nothing on the page explains why the split exists, and no revision or commit hash is pinned on either load, so both calls resolve to whatever the Hub repository holds at the moment they run.
For a research release that is a defensible shortcut. For anything you intend to keep running, it means the tokenizer implementation is code that arrives from a remote repository rather than from a dependency you pinned.
The sample generates 128 tokens from a model built for 8K sequences
The whole example is four statements: import torch and the two transformers classes, load the tokenizer and the model from `Salesforce/xgen-7b-8k-base`, tokenize the string `The world is`, and call `model.generate(**inputs, max_length=128)` before decoding.
Four things are absent from it, and each one matters more than the code that is there. `max_length=128` samples a fraction of the 8K window the checkpoint was trained for. No sampling parameters are passed, so whatever defaults the library applies are what you get. The model is loaded with `torch_dtype=torch.bfloat16` and never moved, with no `device_map` and no call to a CUDA device, so the snippet leaves placement to the environment. And the prompt is tokenized without padding or truncation arguments, which is harmless for a single string and becomes a problem the moment two prompts are batched.
It reads as a smoke test rather than a recipe: enough to prove the checkpoint loads and produces text, not enough to tell you how to serve it.
requirements.txt pins transformers and nothing else the sample needs
The dependency file has one line, `transformers==4.29.2`, with an exact version pin and nothing else in it. The sample imports torch, and the README installs tiktoken through pip in a separate sentence, so neither of those comes from the file that exists to describe the environment. There is no `accelerate`, no `safetensors` pin, no CUDA or torch version, and no lockfile of any kind behind them.
That is a narrow and honest choice for a research release: pin the one library whose API the sample depends on, and leave the rest to the reader's stack. The gap is that the exact transformers version is a moving constraint rather than a current one, and the sample passes `trust_remote_code=True`, which means the tokenizer implementation is version-coupled to what the Hub repository ships. Anyone reproducing this in a year will be reading a pin that nothing else in the repository supports.
The practical reading: treat requirements.txt as a record of what was used, not as an installation recipe.
Nine entries at the top level, and none of them trains anything
The repository root holds AI_ETHICS.md, CODEOWNERS, CODE_OF_CONDUCT.md, CONTRIBUTING.md, LICENSE, README.md, SECURITY.md, requirements.txt and sample.py. That is the whole release surface on GitHub. There is no training script, no dataset, no configuration file for a run, no evaluation harness and no checkpoint manifest, and the paper's title describes a model trained on 8K input sequence length while the repository contains nothing that shows how that training was done or with what data.
What it is, then, is a pointer: model cards and weights on the HuggingFace Hub, one sample file, one pinned dependency, and a set of contribution and ethics documents. That is a normal shape for an official research release, and it is also why the repository cannot answer questions about memory footprint, throughput or training cost.
Version state is equally thin. The repository has no GitHub releases, and the last push was on 2026-06-02, three and a half months after which nothing here has moved. Anything you depend on should be pinned by Hub revision rather than by a tag, because there are no tags here either.
Five governance documents for nine files, and an ethics notice that asks you to evaluate first
More than half the top level files are process: AI_ETHICS.md, CODE_OF_CONDUCT.md, CONTRIBUTING.md, SECURITY.md and CODEOWNERS, against one sample and one requirements file. For a repository whose tracked content is a page and a snippet, that is a deliberate signal about what kind of artifact this is meant to be.
The ethics section states the same thing in plain words. This release is for research purposes only in support of an academic paper, the models, datasets and code are not specifically designed or evaluated for all downstream purposes, and users should evaluate and address concerns about accuracy, safety and fairness before deploying. It points at two Salesforce policy documents, the acceptable use policy and the AI acceptable use policy, and at common limitations of AI. The instruction-tuned checkpoint carries the same restriction at model-card level.
Two files have no counterpart in the tree contents shown here, CODEOWNERS and SECURITY.md, and the page gives no contact for either. The only correspondence addresses on record are the two research emails for the paper.
Editorial conclusion
XGen is a reference release, not a product surface. Take it if you want to study or reproduce long sequence modelling at 7B, or need one specific checkpoint that the current model hubs still host, and read the pinned transformers version as a museum piece rather than a dependency you would install today. Leave it if you need training code, a reproducible environment or a supported deployment path: the tree has no training script and no dataset, requirements.txt covers one package, and the instruction-tuned checkpoint is marked for research purposes only. Before you build on it, pin the exact Hub revision of the checkpoint you load, record your own torch and CUDA versions outside the repository, and read AI_ETHICS.md and the AUP it links, because the release's own notice asks for an accuracy, safety and fairness evaluation before any deployment.
Frequently asked questions
How do I run the XGen-7B-8K-Base model?
Install tiktoken with pip, then load AutoTokenizer and AutoModelForCausalLM from Salesforce/xgen-7b-8k-base, passing trust_remote_code=True for the tokenizer and torch_dtype=torch.bfloat16 for the model. The README's sample calls model.generate with max_length=128 and decodes the result.
What sequence lengths do the XGen checkpoints support?
Two base checkpoints at 7B: XGen-7B-4K-Base supports 4K sequence length and XGen-7B-8K-Base supports 8K. A third, XGen-7B-8k-Inst, is the instruction-finetuned version and is marked for research purposes only.
Does the salesforce/xgen repository contain the training code?
No. The top level holds nine entries, among them README.md, LICENSE, requirements.txt pinning transformers==4.29.2 and a single sample.py. No training script, dataset or run configuration is there; the model cards and weights are on the HuggingFace Hub.
Which tokenizer does XGen use?
The OpenAI Tiktoken package, installed with pip install tiktoken, rather than a tokenizer file inside the repository. The sample loads it with trust_remote_code=True, which allows the tokenizer code to come from the Hub repository.
Can the XGen instruction-tuned model be used in production?
The README marks XGen-7B-8k-Inst as for research purpose only, and the ethics notice says the release supports an academic paper, that the models are not evaluated for all downstream purposes, and that accuracy, safety and fairness should be assessed before deploying.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/salesforce-xgen)Star history chart for your README
[](https://hysenlabs.com/projects/salesforce-xgen)Was this useful?