go-openai is one flat package for Responses, Chat Completions and the legacy Assistants endpoints
OpenAI, GPT 5.6, GPT-Image-2, Whisper API clients for Go
At a glance
- What is it?
- sashabaranov/go-openai is an unofficial Go client whose root package is the entire OpenAI surface: Responses, Chat Completions, images, audio, batches and the deprecated Assistants calls. Model churn is fast, and retries, streaming recovery and failure semantics are left in your code.
- Who is it for?
- Pick go-openai when you want one dependency with typed structs for Responses, Chat Completions and the older surfaces, and you are willing to write your own retry and stream recovery. Walk away if you need vendor support, a stated compatibility promise, or a client that has already deleted the Assistants endpoints.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 47 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
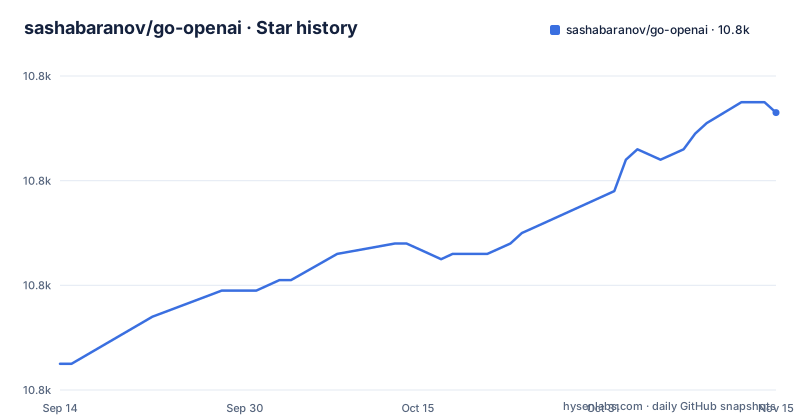
- sashabaranov/go-openai10,813 ★ · +48
| Repository | 2026-09-14 | 2026-11-15 |
|---|---|---|
| sashabaranov/go-openai | 10.8k | 10.8k |
48 Stars in the last 62 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Every API surface sits in the root package, the deprecated ones included
There is no internal client package to learn. chat.go, completion.go, chat_stream.go, audio.go, image.go, embeddings.go, files.go, batch.go, moderation.go, models.go, engines.go, edits.go, assistant.go and messages.go are all at the repository root, next to client.go and config.go. The only subdirectories with exported purpose are jsonschema/ and internal/, so `go get` pulls the whole surface into your build whether or not you touch audio.
The cost is that superseded calls stay compiled in. assistant.go and messages.go implement the Assistants API, which the README calls a legacy surface while still shipping it, and fine_tunes.go sits beside fine_tuning_job.go so both generations of the fine-tuning endpoint resolve from the same import. If you are migrating off Assistants, the client does not remove the dependency for you: the file stays in your module graph and your upgrade diffs keep touching a code path you no longer call.
Test layout follows the same honesty: api_integration_test.go and the *_api_test.go files sit separately from api_internal_test.go, and .golangci.yml at the root governs the lint rules.
GetOutputText is the convenience, response.Output is where the work is
Two generations of text API live side by side. CreateResponse and CreateResponseStream are the Responses entry points; CreateChatCompletion is kept for existing integrations. For anything new the guidance is Responses, and the reason is visible in the types rather than in a policy statement.
Input on a Responses request takes either a string or a slice of typed input items. Reading the answer has the same split: GetOutputText returns the generated text and nothing else, and the README points you at response.Output when the request involves reasoning, tools, multimodal output or any custom processing.
Server-side state makes Instructions a per-call obligation
Multi-turn continuation rests on two fields. Store is a pointer to a bool, so true is an explicit choice about whether OpenAI keeps the response, and PreviousResponseID carries first.ID into the next CreateResponse call. What is not stored is your Instructions value, and the README is explicit about it: resend Instructions on each call when they should continue to apply.
That is a small sentence with a large consequence. Cache the system prompt once at startup and the first turn is shaped by it while every later turn runs without it, with no error and no field you can inspect afterwards to prove why the answer changed.
The examples/responses program in the repository covers multi-turn state.
go get, one environment variable, one CreateResponse call
The client is installed as an ordinary module, and go.mod declares go 1.18, which matches the README's stated floor of Go 1.18 or later:
go get github.com/sashabaranov/go-openaiThe README's example reads the key from the environment and passes it to NewClient:
export OPENAI_API_KEY="<your key>"Then a whole program is NewClient, one CreateResponse call and one print:
package main

import (
	"context"
	"fmt"
	"log"
	"os"

	openai "github.com/sashabaranov/go-openai"
)

func main() {
	client := openai.NewClient(os.Getenv("OPENAI_API_KEY"))

	response, err := client.CreateResponse(context.Background(), openai.CreateResponseRequest{
		Model:        openai.GPT5Dot6Sol,
		Instructions: "You are a concise technical explainer.",
		Input:        "Why is the sky blue?",
	})
	if err != nil {
		log.Fatal(err)
	}

	fmt.Println(response.GetOutputText())
}
Expect the sky-blue answer on stdout. To run the maintained versions instead of this snippet, the examples directory holds one program per surface:
go run ./examples/responsesAlongside examples/responses/ there are examples/completion/, examples/completion-with-tool/, examples/images/, examples/voice-to-text/ and examples/chatbot/, so a feature you only read about in the README has a runnable file one command away.
Reasoning effort is per-model, and a raw model ID is always an escape
Model choice comes as a small table of constants: GPT6Dot1Sol for gpt-6.1-sol, GPT6Astra for gpt-6-astra, GPT6Sol for gpt-6-sol, GPT6Luna for gpt-6-luna, with GPT-5.6 and earlier constants still exported. GPT-6.1 Sol and Astra take reasoning effort low, medium (the default), high, xhigh and max, and do not accept none or minimal. GPT-6 Sol and Luna also accept none. Tool calling with GPT-6.1 Sol or Astra is a Responses job, and so is combining GPT-6 reasoning with tools.
Two details decide whether a configuration-driven app works on day one. First, the effort vocabulary is not uniform across the table, so a single effort string mapped across models will send none to a model that has no none, and the README does not say which error comes back for it. Second, model IDs are accepted as strings, so you can call a released model before this package adds a constant for it. That is the escape hatch, and it is also the trap: the constant buys you compile-time checking, and the string only buys you a runtime error.
A file named reasoning_validator.go sits at the repository root, but the README does not describe what it checks.
BaseURL and DefaultAzureConfig are the whole escape hatch
Everything the client does not know about your endpoint is reachable through DefaultConfig, which exposes the HTTP client, the base URL, the organization and headers before the client is built:
config := openai.DefaultConfig(os.Getenv("OPENAI_API_KEY"))
config.BaseURL = "https://your-compatible-endpoint.example/v1"
client := openai.NewClientWithConfig(config)
That is the route for an OpenAI-compatible gateway, a proxy or a vendored endpoint, and it needs no fork. For Azure OpenAI there is DefaultAzureConfig, where the deployment mapping and the API version come from your Azure resource rather than from a model constant.
What you give up by pointing at a third-party endpoint is local validation. The client cannot check that a request field exists on the service behind your BaseURL, so an unsupported field or a wrong Azure deployment name surfaces as an error from that endpoint instead of from your build, and the only thing the client contributes is the request shape it was written against.
A stream ends on io.EOF, and the README leaves the broken case open
Streaming is a Receive loop over typed events rather than a channel of strings:
stream, err := client.CreateResponseStream(ctx, openai.CreateResponseRequest{
	Model: openai.GPT5Dot6Sol,
	Input: "Write a short story about a curious gopher.",
})
if err != nil {
	return err
}
defer stream.Close()

for {
	event, err := stream.Recv()
	if errors.Is(err, io.EOF) {
		break
	}
	if err != nil {
		return err
	}
	if event.Type == openai.ResponseStreamEventOutputTextDelta {
		fmt.Print(event.Delta)
	}
}
Two mechanics matter. The loop ends on errors.Is(err, io.EOF), so an ordinary read error and the end of the stream arrive through the same return value and have to be told apart, and you only get text when the event type is ResponseStreamEventOutputTextDelta, meaning anything else in the stream is silently dropped by this loop.
That is also the failure gap. Nothing in this example covers a connection that dies halfway: there is no documented way to resume, no partial-response identifier to restart from, and nothing about what a tool call looks like as stream events. A dropped stream leaves your program with the prefix it already printed and no route back, so the buffering that survives it is yours to build.
APIError carries three fields, and the retry policy is yours
Failures are surfaced as a typed error you unwrap with errors.As:
var apiError *openai.APIError
if errors.As(err, &apiError) {
	fmt.Printf("OpenAI error: status=%d code=%v message=%s\n",
		apiError.HTTPStatusCode, apiError.Code, apiError.Message)
}
HTTPStatusCode, Code and Message are the three values the README shows. What it does not show is any retry policy, backoff schedule, or rate-limit handling, even though ratelimit.go is a file at the repository root, so the README gives no guidance on handling a 429 or a 5xx. Your retry loop therefore has the status code to work with and no documented rate limit headers to pace against.
Release cadence sets the other constraint. v1.42.0 shipped on 2026-08-02, v1.42.1 on 2026-09-11 and v1.43.0 on 2026-09-29, with the last push to master on the same day as v1.43.0. The repository is Apache-2.0 and calls itself an unofficial client, and the README documents no deprecation policy or compatibility promise, so plan on reading the diff when you bump, and on getting your support answers from the community rather than from a vendor.
Editorial conclusion
Pick go-openai when you want one dependency with typed structs for Responses, Chat Completions and the older surfaces, and you are willing to write your own retry and stream recovery. Walk away if you need vendor support, a stated compatibility promise, or a client that has already deleted the Assistants endpoints. Before you commit, check whether the version you import exports a named constant for your model or whether you must pass the model ID as a string.
Frequently asked questions
How do I install go-openai and make a first Responses API call?
Run go get github.com/sashabaranov/go-openai, which needs Go 1.18 or later, then export OPENAI_API_KEY and build a client with NewClient. The first call is CreateResponse with a Model, Instructions and Input, and the text comes back from GetOutputText.
Does go-openai still support Chat Completions?
Yes. CreateChatCompletion stays supported for existing integrations, and the project asks new text-generation, reasoning, tool-calling and multi-turn work to start with the Responses API instead. Both surfaces live in the root package.
Can go-openai talk to Azure OpenAI or another compatible endpoint?
DefaultConfig exposes the HTTP client, BaseURL, organization and headers, and NewClientWithConfig builds the client from it. For Azure there is DefaultAzureConfig, where you set the deployment mapping and API version your resource requires.
How does go-openai report API errors?
API failures are inspected with errors.As against a *openai.APIError, which carries HTTPStatusCode, Code and Message. The README does not document automatic retries or rate limit handling, so that loop is yours to write.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sashabaranov-go-openai)Star history chart for your README
[](https://hysenlabs.com/projects/sashabaranov-go-openai)Was this useful?