LLamaSharp's backend list has four entries but only three badges, and its model files are coupled to library versions
A C#/.NET library to run LLM (🦙LLaMA/LLaVA) on your local device efficiently.
At a glance
- What is it?
- An MIT-licensed C# and .NET binding that runs language models locally through a C++ project checked in as a submodule, distributed as one main package plus four native backend packages. Two CUDA major versions are maintained side by side, the readme warns that old model files only work with older library versions, the primary example stops mid-identifier, and the tree contains a mobile project the documentation never mentions.
- Who is it for?
- LLamaSharp is worth a look if you want local inference from a .NET application without embedding a native toolchain in your build, because the backend packages exist for every platform the project claims to support and you never compile anything, which is the whole reason the binding exists. Two things to know.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 7 days ago.
- What is it written in?
- Mainly C#, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
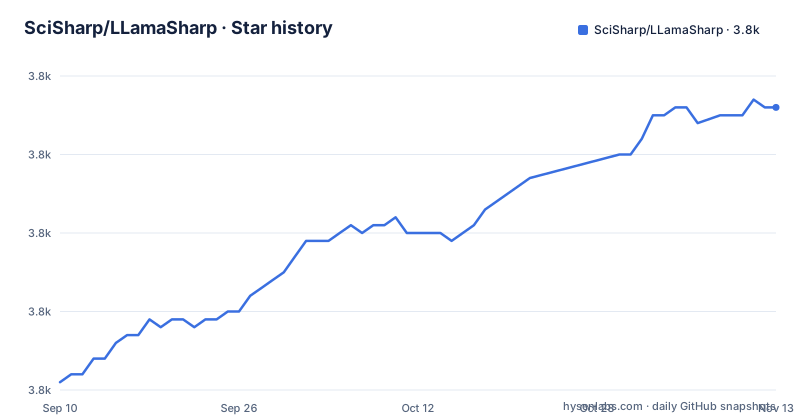
- SciSharp/LLamaSharp3,826 ★ · +35
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| SciSharp/LLamaSharp | 3.8k | 3.8k |
35 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four backends, three badges and two CUDA versions
Performance comes from native libraries compiled from the C++ project, and the readme calls those libraries backends, which is the term the whole installation story uses. Four backend packages are listed in the install section: one pure central processing unit build for the three desktop systems, which also carries the Metal graphics support on macOS, then two separate CUDA packages for two different CUDA major versions, then a Vulkan package. The badge row at the top of the readme links only three of them. The eleventh CUDA version is the one with no badge, which suggests it is the older of the two kept for people who cannot move. For anyone deploying, the practical consequence is that the install list is the authoritative one and the badges are a summary that has drifted.
Model files and library versions are coupled
The model preparation section is the one place the readme tells you something will break. It names the two formats models usually arrive in, says the binding uses a third format that can be converted from either, and then gives two routes: find an already-converted file on a model hub, or convert one yourself with the upstream project's own conversion scripts. Then the warning, which is the sentence worth quoting to anyone on a team: take note of the publishing time, because some older files may only work with older versions of the binding. So a model file is not a static asset; it is version-coupled, and a file someone downloaded two years ago can stop working when the package moves. The rest of the section is advice about formats, recommending quantised models over half-precision ones because it reduces required memory while only slightly affecting output quality.
The upstream C++ project is checked in as a submodule
The repository root contains a directory named after the C++ project the binding is built on, alongside a file that says submodules are in use. That is the single most important structural fact about this codebase: the binding does not wrap a published native package, it carries the native project with it, which is why the readme can send you to that project's own conversion instructions as if they were local documentation. It also explains the layout, with a main managed directory, a mobile one, a web and a web API project, an examples directory, a benchmark project and a unit-test project under a single solution file, all in one repository. The cost is the usual one: the native project's release cycle and the binding's are the same cycle, and a binding release is therefore also a native release.
The primary example stops in the middle of a line
The quick start gives one chat example, and it is the code a first-time user copies. It sets up the namespace imports, builds a parameters object with two named settings, and both settings have explanatory comments that are genuinely instructive: one explains the context size as the longest chat the model can remember, the other explains the graphics offload count and tells you to adjust it according to your graphics memory. It loads the weights, creates a context, builds an executor, and then starts building a chat history before the snippet ends mid-identifier. Everything up to that point is the part you need and none of it is wrong. The truncation means the last step, turning a history into a prompt, is the one thing you have to work out from another example.
Backend choice is a version-matching decision
The readme's first troubleshooting entry is about a graphics processor not being used after a CUDA backend was installed, and the first answer is that you must have installed the backend package matching the CUDA version on the machine. That is the shape of the whole support model. The binding abstracts over a native library that changes shape between versions, so the failure is not that the device is unsupported but that two version numbers disagree, and the documentation answers it by telling you to check which one you installed. Two CUDA majors being published side by side exists for exactly that reason. It also means the four packages are not interchangeable performance options: three of them are version pins in disguise, and choosing the wrong one produces a silent fall back to the processor. Installing is one command, and the second step is choosing which backend to add:
PM> Install-Package LLamaSharpA mobile project exists in the tree and not in the documentation
The repository root holds about ten project directories, and one of them is a mobile binding. The readme's own sections cover documentation, a console demo, integrations, getting started, a question section, contributing, community, and a contributor list, and not one of them mentions mobile. The rest of the tree is similarly under-documented: a benchmark project and a unit-test project exist beside the examples, and a documentation directory and a site configuration drive the documentation you are reading. The integrations are the opposite: three named frameworks for building applications on top of it, each developed in somebody else's repository, and eight worked examples including two web ones inside this repository. So the public surface is wide and well demonstrated while the packaging surface is narrow and silent.
Two community channels, one of them a group invitation URL
The community links are two, and they are shaped differently. One is an invitation to a chat server. The other is a very long address for a Chinese instant-messaging group, which carries a group identifier, an authorisation key, a verification flag and a group code as query parameters. That kind of link is fragile by construction: the group fills, the authorisation expires, and the URL stops working, and the readme carries no fallback for it. It is also a small signal about where the project's users are, alongside a documentation link that points at a third-party site that generates wiki documentation from a repository automatically, which is a fast way to get readable documentation but documentation nobody has reviewed.
Editorial conclusion
LLamaSharp is worth a look if you want local inference from a .NET application without embedding a native toolchain in your build, because the backend packages exist for every platform the project claims to support and you never compile anything, which is the whole reason the binding exists. Two things to know. The model file you choose is coupled to the library version, because the readme warns that older converted models only work with older versions of the binding, so a model file and a package version have to move together. And backend selection is a version-matching decision rather than a performance one, which is why the readme's first troubleshooting entry is about a graphics processor not being used after a backend was installed.
Frequently asked questions
What is LLamaSharp?
A cross-platform C# and .NET library for running language models locally, built on a C++ inference project that the repository carries as a submodule. It exposes higher-level APIs plus retrieval-augmented generation support and runs efficiently on both processor and graphics hardware.
Do I need to compile C++ to use LLamaSharp?
No. The native libraries are published as separate backend packages for the three desktop systems with central processing unit support, plus Metal on macOS, two CUDA major versions for two systems, and Vulkan. You install a backend package alongside the main one. A guide is linked for compiling a backend yourself if none of the published ones matches your device.
Why is my GPU not used after installing a CUDA backend?
The readme's first troubleshooting entry covers this: you need the backend package that matches the CUDA version installed on the machine. Two CUDA major versions are published side by side, so choosing the wrong one is a version mismatch rather than an unsupported device.
Why is my old GGUF model file not working?
The readme warns that older converted model files may only work with older versions of the library, so a model file and a package version move together. It recommends quantised models over half-precision ones to reduce the memory they need.
What model file format does LLamaSharp use?
A third format, GGUF, which can be converted from the two formats models usually arrive in. You either find an already-converted file on a model hub or convert one yourself using the upstream project's conversion scripts.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/scisharp-llamasharp)Star history chart for your README
[](https://hysenlabs.com/projects/scisharp-llamasharp)Was this useful?