Seldon Core 2 pipelines ride Kafka, and overcommit moves memory risk to load time
An MLOps framework to package, deploy, monitor and manage thousands of production machine learning models
At a glance
- What is it?
- Seldon Core 2 is a Go framework that puts model servers, pipelines, experiments and autoscaling into Kubernetes. It leans on Kafka between components and Business Source License terms, so both the data contract and the licensing deserve a look before adoption.
- Who is it for?
- Seldon Core 2 fits teams already running Kubernetes who want pipelines, shared inference servers, shadow deployments and autoscaling in one serving layer. It does not fit a team that needs a permissive license, a documented data contract on the project page, or a decision about which release line to pin.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
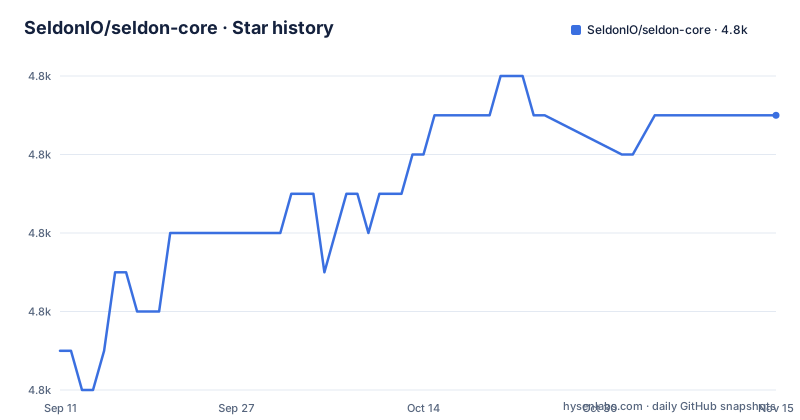
- SeldonIO/seldon-core4,785 ★ · +6
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| SeldonIO/seldon-core | 4.8k | 4.8k |
6 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Kafka sits between pipeline components
Pipelines come first in the feature list, described as composable AI applications that use Kafka for realtime data streaming between components. The repository carries a kafka/ directory next to prometheus/, tracing/, and service-meshes/, so the streaming layer is part of the deployment footprint rather than something bolted on later. For anyone writing a custom component, the consequence is concrete: your code meets a broker topic contract instead of an HTTP endpoint on its neighbour. What the overview does not give you is the record format or the topic naming convention, so the payload contract has to come from the Pipelines page in the documentation rather than from the repository itself.
Overcommit and shared servers push failure to load time
Multi-Model Serving consolidates several models on shared inference servers to cut infrastructure cost, and Overcommit goes one step further by letting you deploy more models than available memory allows, on the argument that unused ones cost nothing. Both move the risk downstream. The control plane accepts a set of models that does not fit in RAM at that moment, so a reader planning capacity has to treat each model's memory number as a budget it may exceed. Expect to learn which model actually fits when traffic arrives rather than when it is deployed. Nothing in the overview says how the framework decides that race, or what a reader is supposed to watch.
Autoscaling runs on native rules or on logic you write
Autoscaling is offered for models and for application components, based on native logic or custom logic. Two ways to scale means two things to settle before rollout: which rule counts as native, since the overview never names it, and what a custom rule is allowed to inspect. Write the rule yourself and you own its inputs, its thresholds, its cooldown, and its behaviour when the signal goes flat or stale. The documentation set carries a Performance Tuning page, which is where a built-in policy would be described, and that gap matters for anyone who assumed a shipped default with a documented metric.
Experiments keep both candidate models resident
Experiments route data between candidate models or pipelines, with support for A/B tests and shadow deployments. Shadow deployments raise a second question, what happens to the shadow's output, and the overview does not say whether it is compared with the live answer, logged, or discarded. Design the experiment with that unknown in mind. The samples directory holds experiment_versions.md alongside the matching experiment_versions.ipynb, and experiments/ sits beside it, which is where a working shape would be.
Two deploy paths: the scheduler or raw kubectl
Two different lifecycles live in one repository. The local path delegates to the scheduler module, while the raw path applies YAML with kubectl. Both begin by creating a namespace whose name defaults to seldon-mesh, and the create command is written to tolerate one that already exists rather than fail:
SELDON_NAMESPACE?=seldon-mesh
make -C scheduler pull-all start-all
make -C scheduler stop-all
kubectl create ns ${SELDON_NAMESPACE} || echo "namespace already existing"
kubectl create -f k8s/yaml/crds.yaml
sleep 1
kubectl wait --for condition=established --timeout=60s crd/servers.mlops.seldon.io
kubectl wait --for condition=established --timeout=60s crd/serverconfigs.mlops.seldon.io
kubectl create -f k8s/yaml/components.yaml -n ${SELDON_NAMESPACE}
kubectl create -f k8s/yaml/servers.yaml -n ${SELDON_NAMESPACE}
That ordering is the contract worth memorising: CRDs first, then a wait on both established conditions with a 60 second timeout, then components and servers in the namespace. The undeploy target reverses it, deleting servers, then components, then the CRDs, each with --ignore-not-found=true, and only the servers delete uses --wait=true. The undeploy target never deletes the namespace, and an undeploy cut short can also leave the CRDs behind, so the next deploy prints namespace already existing and still has to clear the same two waits.
The CRD names give away the cluster-facing API
The two custom resources the deploy path blocks on are crd/servers.mlops.seldon.io and crd/serverconfigs.mlops.seldon.io, which tells you the cluster API is organised around servers and their configuration. The tree backs that up with apis/, operator/, components/, scheduler/, hodometer/, and the k8s/ directory that holds the YAML being applied, plus ansible/ for infrastructure work and service-meshes/ for mesh integrations. The Go code is split into several modules, which the top-level Makefile wires together for you:
go work init || echo "go modules already initialized"
go work use operator
go work use scheduler
go work use apis/go
go work use components/tls
go work use hodometer
go work use tests/integration
None of that reveals the field set of either resource. For the actual shapes, the Models, Servers, and Pipelines pages are the place to look, and samples/cli-tests.md next to samples/cli-tests.ipynb shows how walkthroughs are kept, as notebooks exported to Markdown.
Docs fail the build on a warning or a typo
Documentation is built with warnings promoted to errors, and the spell target rewrites files instead of only reporting them:
cd docs && pip install -r requirements-docs.txt
misspell -w docs/source/contents
The html target runs the Sphinx build inside docs/ with SPHINXOPTS=-W, so a stale cross reference ends the build instead of printing a note. The -w flag on misspell means running the target can edit docs/source/contents in place, which matters if you run it on a dirty tree. Local preview is plain static serving: after a clean and a rebuild, docs_serve_html runs python -m http.server 8000 from docs/build/html. The result is a docs workflow that is strict by default, so plan for a failed build the first time a reference moves.
Business Source License, two release lines, a push dated 2026-03-23
Licensing is stated without hedging: Seldon is distributed under the terms of the Business Source License, a complete version sits in the LICENSE file in this repository, contributions are accepted under those same terms, and commercial use enquiries are pointed at seldon.io rather than answered in the tree. The repository's license metadata is left unasserted, so read the LICENSE file instead of trusting a badge. Versions are more tangled. The default branch is v2, while recent tags include v1.19.0 from 2026-01-23, the v1.19.0-rc.1 candidate from 2026-01-08, and v2.10.2 from 2025-12-19, and the most recent recorded push is dated 2026-03-23. Pin a line deliberately and confirm which one the documentation you are reading describes.
Editorial conclusion
Seldon Core 2 fits teams already running Kubernetes who want pipelines, shared inference servers, shadow deployments and autoscaling in one serving layer. It does not fit a team that needs a permissive license, a documented data contract on the project page, or a decision about which release line to pin. Check three things first: which version line your documentation describes, because the default branch is v2 while recent tags include both v1.19.0 and v2.10.2; what the Business Source License actually permits for your use, since the LICENSE file governs and contributions land under the same terms; and what native autoscaling looks at, because custom rules move that responsibility onto you.
Frequently asked questions
What is Seldon.io and what does it do?
Seldon Core 2 is an MLOps and LLMOps framework for deploying, managing and scaling AI systems in Kubernetes, from single models through to modular, data-centric applications, on premises or in any cloud.
what is seldon core
It is Seldon's Kubernetes serving layer: pipelines that stream data between components over Kafka, autoscaling for models and components using native or custom logic, multi-model serving on shared inference servers, overcommit, experiments with A/B tests and shadow deployments, and custom components for drift or outlier detection.
is seldon core open source
The project is distributed under the terms of the Business Source License. A complete version of that license sits in the LICENSE file in the repository, contributions are licensed the same way, and commercial use enquiries are directed to seldon.io.
How do you deploy a model?
The repository Makefile covers deploying Seldon itself. make deploy-local delegates to the scheduler with make -C scheduler pull-all start-all, while make deploy-k8s creates the namespace, applies k8s/yaml/crds.yaml, waits up to 60 seconds for crd/servers.mlops.seldon.io and crd/serverconfigs.mlops.seldon.io, then creates components.yaml and servers.yaml.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/seldonio-seldon-core)Star history chart for your README
[](https://hysenlabs.com/projects/seldonio-seldon-core)Was this useful?