TiDB ships a development Dockerfile and two maintained release lines
TiDB is built for agentic workloads that grow unpredictably, with ACID guarantees and native support for transactions, analytics, and vector search. No data silos. No noisy neighbors. No infrastructure ceiling.
At a glance
- What is it?
- TiDB is a distributed SQL database in Go that speaks the MySQL 8.0 protocol, stores rows in TiKV and columns in TiFlash, and commits distributed transactions with two-phase commit over Raft replicas. The repository is the source of the server, not of the image you should run in production, and it carries both a 7.5 and an 8.5 line.
- Who is it for?
- Adopt TiDB when one MySQL-compatible endpoint has to serve transactional writes and analytical reads at a scale where adding nodes beats enlarging one machine, and when you can accept an operational surface made of TiKV, TiFlash and a TiDB Server. Do not adopt it for a single-writer workload on one host, where the coordination layer costs more than it saves, and do not build a release process on the repository's own Dockerfile, which its header says is for development only.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
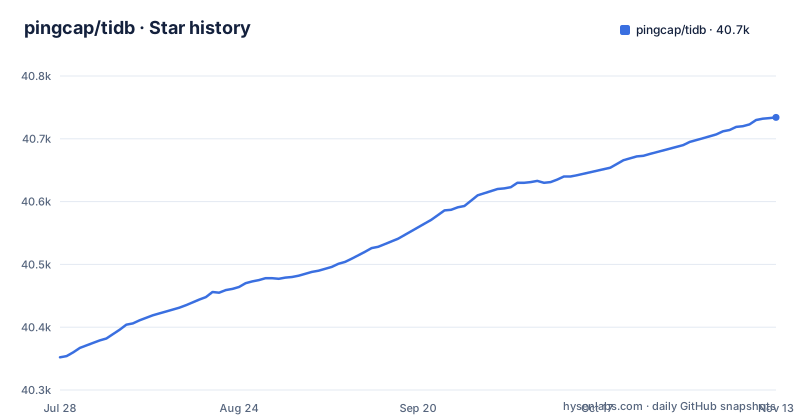
- pingcap/tidb40,734 ★ · +382
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| pingcap/tidb | 40.4k | 40.7k |
382 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Dockerfile in the repository says not to use it in production
The header comment is unambiguous: the current dockerfile is only used for development purposes, and anyone deploying it in production is pointed at a Dockerfile in a different repository, PingCAP-QE/artifacts. A second file, Dockerfile.enterprise, sits beside it.
What this one does is worth reading anyway, because it shows what a TiDB server binary is. A builder stage on `golang:1.27.3` pinned by digest copies the tree and runs one make target:
make serverThe runtime stage is `quay.io/rockylinux/rockylinux:9-minimal`, also digest-pinned, and it copies a single file out of the builder, `/tidb/bin/tidb-server`, sets `EXPOSE 4000` and makes it the entrypoint. Both stages are pinned by digest as well as by tag, which is the right discipline for a build you intend to repeat.
So a single binary, one exposed port, and a rockylinux 9 base. If you containerise this yourself, the missing piece is the storage layer, because tidb-server is the SQL front end and TiKV is a separate system to run.
TiFlash follows TiKV through the Multi-Raft Learner protocol
The hybrid part is two storage engines rather than one. TiKV is row-based, TiFlash is columnar, and TiFlash replicates from TiKV in real time using the Multi-Raft Learner protocol. A TiDB Server sits above both and coordinates query execution across them.
That arrangement is what makes a single endpoint serve transactional and analytical work, and it is also where the interesting failure lives. Two copies of your data exist, one of them derived.
The feature description does not state a lag bound, a staleness indicator, or a way to ask the engine how far behind TiFlash is. If your reports have to reconcile against the row data, that gap is the thing to measure on your own workload before you trust the engine choice.
Two-phase commit and majority writes are two separate guarantees
Two claims sit next to each other in the feature list and they are not the same claim. Distributed transactions use a two-phase commit protocol for ACID compliance, and transactions span multiple nodes with correctness preserved across network partitions and node failures. High availability comes from built-in Raft consensus, with data in multiple replicas and a transaction committed only after writing to the majority of replicas.
So consistency of a transaction is enforced by coordinating participants, and durability of each write is enforced by replication quorum. Both are real. Both also cost something on every commit, and the feature list quantifies none of it. There is no latency figure, no throughput figure, and no statement about what a transaction costs when it touches one region versus a dozen.
The design decision you are making is that you would rather pay coordination per transaction than pay for a single machine large enough to avoid it. That trade is worth it at some scale and clearly not at others, and the documentation does not tell you where the line sits.
Two build systems and three data movement tools share the root
The root carries both a Bazel setup and a Make setup: `.bazelrc`, `.bazelversion`, `BUILD.bazel`, `MODULE.bazel`, `WORKSPACE`, `DEPS.bzl` and a `WORKSPACE.patchgo` on one side, `Makefile` and `Makefile.common` on the other. A contributor touching a given path has to know which one governs it, and the repository does not draw that line at the root.
Three data movement tools also live here rather than in their own repositories. `br/` is backup and restore, `lightning/` is the bulk loader, and `dumpling/` is the export side. If you are sizing a restore window, those three directories are where the answer lives.
The root also contains an `errors.toml` file next to `go.mod`.
make server builds, and make dev is the whole pipeline
The Makefile's own help target is generated by scanning for `##` comments, which makes the target list discoverable. The default goal is `server` plus a success echo, `all` adds the dev tools and benchkv, and there is a separate `server-admin-check` variant built with admin checks.
The workflow target is the one to read before you start:
make devIts recipe is a chain, and the chain is `checklist check integrationtest gogenerate br_unit_test test_part_parser_dev ut check-file-perm`. That is unit tests, integration tests, a parser test suite, generated-code checks, a backup and restore unit suite, a file permission check, and a checklist item. The target's own comment calls it the full development workflow including all tests and checks.
So there is no cheap gate here. A change to a SQL parser path still has to satisfy the integration tests and the backup and restore suite before it is green, which is the right default for a database and a slow one to iterate against.
v7.5.8 was tagged three weeks after v8.5.8
Three releases appear on the feed and they are not one line. v8.5.7 on 2026-07-09, v8.5.8 on 2026-08-27, and v7.5.8 on 2026-09-17, which is the most recent of the three despite being the older major.
So the 7.5 line is still receiving patches, and the newest tag is not the newest line. Anyone who upgrades by taking the most recent release gets a different major than someone who upgrades by taking the newest 8.5, and the two will diverge. Name the line in your runbook rather than the word latest.
Licensing is the easy part. Everything is on GitHub under Apache 2.0 including the enterprise-grade features, with a `ThirdPartyNotices.txt` and a `LICENSES/` directory at the root.
The repository leads with agentic workloads, the README leads with HTAP
Two different products are described in two different places. The repository description opens with agentic workloads that grow unpredictably, ACID guarantees, and native support for transactions, analytics and vector search. The README's feature list is a different pitch: distributed transactions, scalability, high availability, HTAP, cloud-native deployment, MySQL compatibility and open source.
Vector search illustrates the gap. It appears in the README as a link to a TiDB Cloud documentation page, alongside changefeed and data migration. The quick start has three routes, a local playground, Kubernetes with TiDB Operator, and TiDB Cloud with a free plan that needs no credit card, and only the last is a managed service.
Read that as a question to ask before planning, not a criticism. When a capability is introduced through a cloud documentation link, the open source server and the managed offering are not the same surface, and the feature list will not always tell you which side you are reading about.
When a single MySQL server is the better answer
The compatibility claim is the most useful thing in the README and also the most load-bearing: TiDB is compatible with MySQL 8.0, so you can migrate an application without changing code, or with minimal modifications, and a suite of data migration tools is provided. The phrase to notice is minimal modifications, because that is where the honest difference lives.
A single MySQL 8.0 server is one process that stores rows itself. TiDB separates computing from storage, so you can add nodes horizontally or increase resources on existing nodes without downtime, and the SQL layer coordinates transactions across whatever is underneath. That is the right shape when reads and writes compete for the same machine or when one box has become the ceiling.
It is the wrong shape for a workload with a single writer on hardware you control. There, the two-phase commit layer, the Raft replicas and the TiKV and TiFlash pair are overhead with no upside, and MySQL 8.0 gives you the same protocol and the same driver with none of it.
Editorial conclusion
Adopt TiDB when one MySQL-compatible endpoint has to serve transactional writes and analytical reads at a scale where adding nodes beats enlarging one machine, and when you can accept an operational surface made of TiKV, TiFlash and a TiDB Server. Do not adopt it for a single-writer workload on one host, where the coordination layer costs more than it saves, and do not build a release process on the repository's own Dockerfile, which its header says is for development only. Verify three things: which release line you are on, since v7.5.8 was tagged on 2026-09-17 after v8.5.8 on 2026-08-27, whether the TiKV to TiFlash replication is keeping up for the reports you intend to run, and whether the feature you read about lives in the open source server or only in TiDB Cloud.
Frequently asked questions
What does TiDB stand for?
In the README, Ti stands for Titanium, and the name is pronounced taɪdiːbiː. The project describes itself as an open-source, cloud-native, distributed SQL database built for high availability, horizontal and vertical scalability, strong consistency and high performance.
Is TiDB free?
All of the source code is on GitHub under the Apache 2.0 license, including the enterprise-grade features, so the database itself carries no license fee. TiDB Cloud is a separate fully managed offering with a free plan that requires no credit card.
How do I run TiDB locally without Kubernetes?
The README gives three routes and no commands: a local test cluster through the TiDB quick start guide, a self-managed Kubernetes cluster or a public cloud Kubernetes service through TiDB Operator, or a free TiDB Cloud cluster, which is the recommended option. The repository's own Dockerfile is marked for development purposes only.
Does TiDB work with existing MySQL clients and ORMs?
TiDB is compatible with MySQL 8.0, so familiar protocols, frameworks and tools work against it, and you can migrate an application with no code change or with minimal modifications. A suite of data migration tools is provided for moving application data in.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pingcap-tidb)Star history chart for your README
[](https://hysenlabs.com/projects/pingcap-tidb)Was this useful?