MCP Knowledge Graph stores a context called work in two different files
MCP server enabling persistent memory for Claude through a local knowledge graph - fork focused on local development
At a glance
- What is it?
- A local JSONL knowledge graph exposed over MCP with ten aim-prefixed tools, a master database, and a project directory name that has to be spelled exactly one way while the global path can be anything. The manifest sits a minor version ahead of its newest tag, and the MCP SDK is pinned to an exact version.
- Who is it for?
- The design is small, local and easy to reason about, and the safety conventions around the memory files are the strongest part of it. Three things to check before you adopt it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 170 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
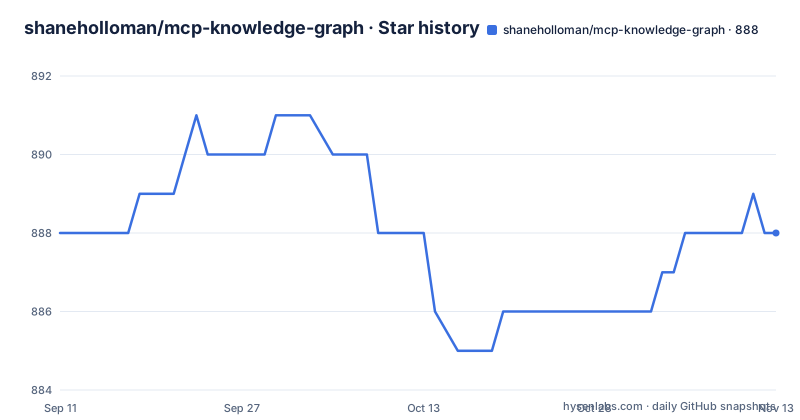
- shaneholloman/mcp-knowledge-graph888 ★ · +0
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| shaneholloman/mcp-knowledge-graph | 888 | 888 |
0 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It calls itself a fork in the description and never names the original
The repository description ends with a clause that the readme never picks up: a fork focused on local development.
That is the whole of the provenance. Nothing in the readme names what it was forked from, and the acknowledgements section does not exist. For a package that installs by name through npx, that leaves a reader unable to tell which upstream to compare against, and it sits next to a naming scheme that is clearly not upstream: the directory called `.aim`, the tools prefixed `aim_`, and the in-file marker type `_aim`, with AIM standing for AI Memory.
So the fork's contribution, as far as the repository describes itself, is the naming scheme and the storage layout. The tool list, the parameters and the storage logic are all documented at the same level of detail, so it is not marked which parts are local additions, which is the distinction a reader comparing two implementations would want most.
The publication side has the same shape. Three releases exist, all tagged on 22 December 2025, at 21:18, 21:36 and 21:49 UTC, and none of them carries release notes beyond the version number.
The manifest is at 1.4.0 and the newest tag is v1.3.2
The version in the package manifest is `1.4.0`. The newest published release is `v1.3.2`.
There is no v1.4.0 tag, so a minor version exists in the source tree that has never been published, and the number in the manifest is not something a consumer can install. That is a normal state for an active repository and a bad one to read in isolation, because nothing in the repository says which of the two is the version you get from `npx -y mcp-knowledge-graph`.
The last push to the default branch is dated 29 May 2026, four months after the last release. So the picture is a repository whose tags stopped in December, whose manifest moved past its tags, and which has had commits since.
The description strings are inconsistent in the same way, though harmlessly. The GitHub description ends with the fork clause, while the manifest description is the plain sentence about a persistent memory MCP server with no fork mention at all. Two different places describe the package, and only one of them admits where it came from.
A context named work is two files depending on where you are
The storage model is three rules, and they are simple. A project containing a `.aim` directory uses `.aim/memory.jsonl`. Without a project or without that directory, the configured global location is used. A context adds a suffix, so a context called work becomes `memory-work.jsonl`.
The discovery example is where the design shows a seam.
{
  "project_databases": [
    "default",
    "project-work"
  ],
  "global_databases": [
    "default",
    "work",
    "personal",
    "health"
  ],
  "current_location": "project (.aim directory detected)"
}
The same context, work, is listed as `project-work` in the project location and as `work` in the global location. So a fact stored with context set to work while the tools run inside a project lands in `memory-project-work.jsonl`, and the same call made outside any project lands in `memory-work.jsonl`. The listing makes both visible, which is the right mitigation, and the file organisation diagram elsewhere in the file only ever shows `memory-work.jsonl`, so the two-name case is demonstrated in one place and not the other.
The block is also JSON with comments in it. The `//` lines after the array entries are not valid JSON, so a reader copying the discovery output shape into a parser has to strip them first.
The MCP SDK is held at an exact version
The dependency list has two entries, and they are pinned in two different styles.
`minimist` is at `^1.2.8`, a normal caret range, and it is there to read the `--memory-path` argument out of the command line. `@modelcontextprotocol/sdk` is at `1.0.1` with no operator at all, which in a manifest means exactly that version and no other.
For a CLI argument parser that is normal. For the library that implements the protocol the server speaks, an exact pin is a stronger statement, and a defensible one: the SDK version determines which protocol features and which transport shapes are available, and a floating range means two installs of the same package can register different tool schemas. Pinning trades that surprise for a different one, since the server cannot absorb a protocol fix without a manifest change and a release.
The rest of the toolchain is small and current. TypeScript at `^5.6.2`, node types at `^22.9.3`, and `shx` at `^0.3.4`, which exists for one reason: the build is `tsc && shx chmod +x dist/*.js`, because the TypeScript compiler does not set the executable bit on its output and the package declares a binary at `dist/index.js`. A build dependency on a 0.3.x line of a shell wrapper is the oldest thing in the manifest.
Project-local has to be spelled exactly .aim, global can be anything
The readme has an all-caps section on this, and it is not padding.
For project-local storage:

- Directory MUST be named `.aim` in your project root
- Example: `my-project/.aim/memory.jsonl`
- The system specifically looks for this exact name

For global storage (--memory-path):

- Can be ANY directory you want
- Examples: `~/yourusername/.aim/`, `~/memories/`, `~/Dropbox/ai-memory/`, `~/Documents/ai-data/`
Two names differing by one character, a leading dot and a leading underscore, and the section exists to keep them apart: `.aim` is a directory the system detects, `_aim` is a marker written inside the memory files. The asymmetry is real. Globally you can point at a Dropbox folder and it works, and the file notes that this is how the author keeps his own memories. Locally the name is fixed, and the only documented step is `mkdir .aim` in the project root.
The marker is the second half of the safety story. Every memory file has to begin with an object naming its type as `_aim` and its source as `mcp-knowledge-graph`, and the system refuses to write to a file without it. That prevents clobbering unrelated JSONL, and the consequence is that a JSONL file you already had in that folder cannot be adopted as a memory file. A sample of the expected shape is checked into the repository root as `example.jsonl`.
Two lockfiles, and a prepare script that compiles on install
The root listing contains both `package-lock.json` and `pnpm-lock.yaml`, for two different package managers, in a package whose scripts all use npm.
That is the kind of leftover that costs time rather than correctness, since npm ignores the pnpm lockfile and pnpm ignores the npm one, but it leaves no single answer to which resolution is the intended one. A contributor using pnpm and a contributor using npm can end up with different trees from the same commit.
The install path is worth reading once more, because it is where the shipped package is assembled. The manifest publishes only the `dist` directory and points a binary at `dist/index.js`, and the `prepare` script runs `npm run build`, which is `tsc && shx chmod +x dist/*.js`. So the registry tarball arrives already compiled, while an install from a clone compiles it, and that compile needs the dev dependencies including the TypeScript compiler and the shell wrapper.
The recommended registration path is a single `npx` invocation, which pulls the published package rather than the source, so the build step is not on the path a user actually takes. That is a sensible division, and it is also why the version in the manifest can drift ahead of what `npx` resolves to without anything failing.
Ten tool names, all starting with aim_
The tool surface is ten functions and every one of them carries the prefix.
Storing is `aim_memory_store`, adding to an existing entity is `aim_memory_add_facts`, and there are `aim_memory_link` and `aim_memory_unlink` for the relation edges, `aim_memory_search` by keyword and `aim_memory_get` by exact name, `aim_memory_read_all` and `aim_memory_list_stores` for bulk reads, and `aim_memory_forget` plus `aim_memory_remove_facts` for deletion at two different levels.
The prefix is explained as grouping related memory functions together in multi-tool setups, which is a reasonable name-hygiene rule and also a real constraint: names like `memory_search` and `memory_get` are generic enough to collide with another server in the same client, and the registration snippet shows a `mcpServers` map where a clashing name would be a client's problem to resolve.
Only two parameters are documented across all ten tools. `context` selects a named database and defaults to the master database, and `location` forces project or global storage and defaults to auto-detection. Everything else about the entity shape comes from the examples, which use `name`, `entityType` and `observations` and which end partway through a fourth example at a `location` key with no value.
Editorial conclusion
The design is small, local and easy to reason about, and the safety conventions around the memory files are the strongest part of it. Three things to check before you adopt it. A context name is not the same key in both storage locations, so a memory written under work inside a project will not be found by the same lookup done globally, and the discovery tool is where you find that out. The MCP SDK is held at an exact version, which is a deliberate choice for protocol stability and a real constraint when the protocol moves. And the manifest is already at 1.4.0 while the newest published tag is v1.3.2, so a version number in the manifest is not a thing you can install. Registration is also the only setup step, and there is no container and no server process, which is the strongest argument for the thing.
Frequently asked questions
What does MCP Knowledge Graph store?
Entities, relations and observations across conversations, held in local JSONL files. A master database stored as memory.jsonl is used by default, and named databases such as work, personal and health are optional and created automatically. Ten tools are exposed, all carrying the aim_ prefix, with context and location as the only two documented parameters.
How do I point MCP Knowledge Graph at a memory folder?
Pass --memory-path with any directory you like when registering the server, and the file gives examples including a .aim folder and a Dropbox folder. Project-local storage is the exception: the directory must be named exactly .aim in the project root for detection to work, and mkdir .aim is the whole of the documented setup step.
Why does MCP Knowledge Graph refuse to write to some JSONL files?
Every memory file has to start with a marker object naming the type as _aim and the source as mcp-knowledge-graph, and the server refuses to write to a file that does not carry it. The stated purpose is to prevent accidental overwrites of unrelated JSONL files, and a sample of the expected shape is checked in at the repository root as example.jsonl.
Which Node version does MCP Knowledge Graph need?
Node 22 or newer, declared in the engines field. The published package contains only the dist directory, and the prepare script runs the build, so an install from a clone compiles the TypeScript first using typescript and shx. The manifest is at 1.4.0 while the newest published tag is v1.3.2.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/shaneholloman-mcp-knowledge-graph)Star history chart for your README
[](https://hysenlabs.com/projects/shaneholloman-mcp-knowledge-graph)Was this useful?