shot-scraper's pip install gives you a CLI that cannot take a screenshot yet
A CLI utility for taking screenshots of websites, recording video demos and scraping sites using JavaScript
At a glance
- What is it?
- Simon Willison's command line tool for screenshotting pages, recording video demos and scraping sites with JavaScript, built on Playwright. Installing it is two commands, because the browser is a separate step. The README demonstrates one of the three capabilities it advertises.
- Who is it for?
- This suits scheduled documentation screenshots and bot-driven captures, which is what nearly every cited use actually is. It does not suit an interactive session, and the single example in the README will not get you started on video recording or on JavaScript scraping without a second trip to the documentation.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 32 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
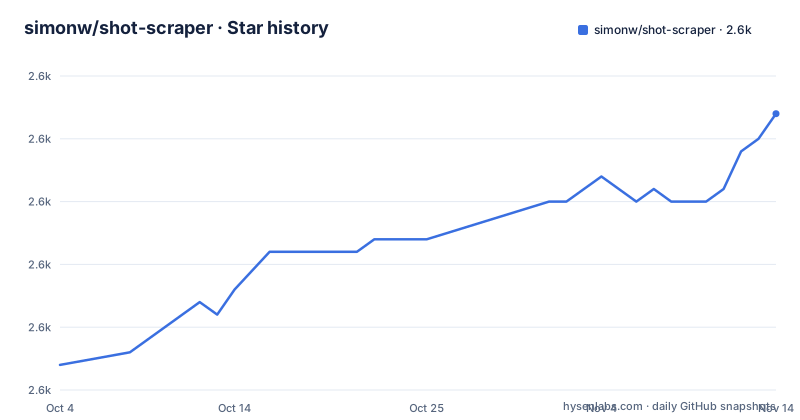
Star history
- simonw/shot-scraper2,607 ★ · +20
| Repository | 2026-10-04 | 2026-11-14 |
|---|---|---|
| simonw/shot-scraper | 2.6k | 2.6k |
20 Stars in the last 41 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The browser is a second install step, not part of the package install
The quick installation is two commands, and the second one is not optional:
pip install shot-scraper
# Now install the browser it needs:
shot-scraper install
The package itself depends on Playwright, with a minimum version of 1.62.0, but depending on the driver is not the same as having a browser. Until the second command has run there is no browser binary to drive, so the CLI installs successfully and then fails at the point of use. That ordering matters for CI images and for containers, where the step is easy to omit because the package install reports success. It also means the tool's real footprint is a Python package plus a browser download, which the two-line form does not convey.
Four dependencies float and the browser driver has a floor
The runtime dependency list has five entries. Four carry no version constraint at all: the command line framework, the YAML parser, the validation library and the default-group plugin. Only Playwright has a bound, and it is a minimum rather than an exact pin. So the browser driver is the one component whose version is deliberately tracked while the rest of the stack floats to whatever the resolver picks. Python is the other floor, at 3.10 or newer. The default-group plugin in that list is the reason the shortest documented invocation works: the console script maps to a single command group, and with a default group installed a bare URL argument is accepted without naming a subcommand, which is why one line is enough to produce a file.
The wheel is built by uv's own backend, constrained to one minor line
The build system is not setuptools. It requires a build backend published by the same tool that manages environments, at 0.9.18 or newer and below 0.10.0, so the accepted range is a single minor series of that backend. That constraint is the tightest version bound anywhere in the project, tighter than Playwright's floor and tighter than any runtime dependency. The backend configuration then sets the module root to an empty string, which tells it the package sits directly under the repository root rather than under a source directory, matching the single package directory in the tree. Building a distribution therefore needs a specific recent tool in the environment, and the build requirement travels with the source metadata rather than with a developer's local setup.
The manifest version and the release tag come from the same commit
The version in the project metadata is 1.12, and the newest release is 1.12, published at the same moment as the last commit to the branch. The two preceding releases are 1.11 in July 2026 and 1.10 at the end of June, so the cadence is roughly monthly with a tighter pair in the summer. Keeping the number in the manifest by hand rather than deriving it from a tag means the manifest and the release list can only agree if someone updates both, and here they do. The consequence for anyone pinning is that the pin has to be the manifest number, since that is what the package index serves. There is no changelog file in the repository root; the changelog link in the metadata points at the GitHub releases page instead, so the release notes are the only history.
The license badge points at master while the default branch is main
One of the badge links at the top of the README resolves to a file path containing the branch name master. The repository's default branch is main. So the badge that is supposed to show the licence is pointing at a branch name that is not the default, and on a repository that has renamed its default branch that link either resolves to a stale branch or to nothing. It is a small thing, and it sits among five badge links including the package index, the releases page, a test workflow query and a chat invite. It is worth noting because the licence is the one badge a reader might actually need, and because the same README's other links are all branch-independent, using full URLs to pages rather than to files on a named branch.
One command is shown for three advertised capabilities
The description names three things: taking screenshots of websites, recording video demos, and scraping sites using JavaScript. The README then demonstrates exactly one of them, passing a URL and producing a PNG. The output naming rule is visible from that one example: a URL becomes a filename by taking the host and turning the dot before the top level domain into a hyphen, so a datasette.io URL produces datasette-io.png. Video recording gets no command anywhere in the file. JavaScript scraping appears once, named as a subcommand in a line about a Hacker News scraper, with the mechanics deferred to a blog post. Everything else, including the annotation feature, is described in the examples section by linking out to a separate article.
Nearly every cited use is a scheduled run rather than a person at a terminal
Read the examples as a list of deployment shapes and one pattern dominates. A repository captures owls near a named place on a schedule. The Datasette documentation screenshots are produced by a separate repository dedicated to that job. A Twitter bot screenshots news homepages using this tool together with GitHub Actions. A news organisation generates regularly updating dashboards for email newsletters. Only one example is a one-off local action, and even that one is described as a complex annotated illustration. The documentation reflects the same bias, leading with a template repository for creating a GitHub repository that takes screenshots, presented explicitly as a way to get started without installing any software.
Editorial conclusion
This suits scheduled documentation screenshots and bot-driven captures, which is what nearly every cited use actually is. It does not suit an interactive session, and the single example in the README will not get you started on video recording or on JavaScript scraping without a second trip to the documentation. Two practical notes. Budget for the extra install step, since the package alone cannot render anything, and note that the Playwright dependency carries a minimum while the other four float, so a fresh environment resolves to whatever is newest. If you need this in CI, the template repository is the documented path and skips local installation entirely.
Frequently asked questions
How do I install shot-scraper?
Two commands. Install the package with pip, then run the install command that fetches the browser it needs. The package depends on Playwright but does not include a browser, so the CLI cannot render anything until that second step has run.
What filename does shot-scraper give a screenshot?
It is derived from the URL. The documented example passes a datasette.io URL and the result is a file called datasette-io.png, so the host is taken and the dot before the top level domain becomes a hyphen.
Which Python versions does shot-scraper support?
Python 3.10 and newer. Playwright is the only runtime dependency with a version bound, at 1.62.0 or newer, while the command line framework, YAML parser, validation library and default-group plugin carry no constraint.
Can shot-scraper record video?
Recording video demos is one of the three capabilities named in the description, and the hosted documentation covers it. The README itself demonstrates only the screenshot command and gives no video invocation.
How do I use shot-scraper without installing anything locally?
Use the template repository the README points at, which creates a GitHub repository that takes screenshots of a page. That path is offered as the way to get started with no local software, and it is how most of the cited examples run.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/simonw-shot-scraper)Star history chart for your README
[](https://hysenlabs.com/projects/simonw-shot-scraper)Was this useful?