PyTorch Forecasting Excludes Three Specific Versions and Splits Its Extras
Time series forecasting with PyTorch
At a glance
- What is it?
- The package wraps PyTorch Lightning with a dataset abstraction, multi-horizon metrics and optuna tuning. Its manifest tells you more about the constraints you will hit than its feature list does, because three versions are excluded by hand and every optional dependency lives behind an extra.
- Who is it for?
- PyTorch Forecasting is a good fit if your forecasting problem has several related series, covariates and a quantile or multi-horizon loss, and if you are already working in the Lightning ecosystem, since the dataset class and the Trainer carry most of the ergonomics.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
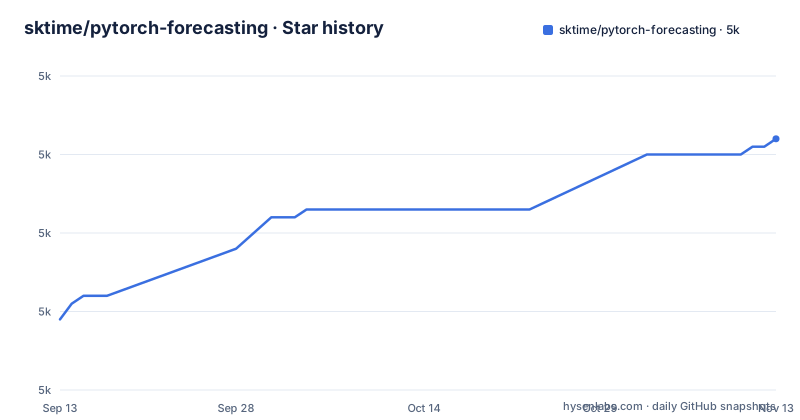
- sktime/pytorch-forecasting5,012 ★ · +23
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| sktime/pytorch-forecasting | 5k | 5k |
23 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The manifest excludes three versions without saying why
The dependency block carries hand-written exclusions that no comment explains:
  "torch >=2.0.0,!=2.0.1,<3.0.0",
  "lightning >=2.0.0, !=2.6.2, != 2.6.3, <2.7.0",
  "scikit-base <1.3.0",
Two specific Lightning patch releases are refused, 2.6.2 and 2.6.3, while the range stops below 2.7.0, so a project already on a later Lightning cannot use this package without resolving the conflict. torch 2.0.1 is excluded on its own, which is the shape of a known bad build rather than a policy decision. scikit-base is held under 1.3.0, and numpy is capped at 3.0.0, pandas under 3.1.0, scipy under 2.0 and scikit-learn under 2.0. For a reader installing today this matters in one specific way: when pip refuses a combination you have to guess at the cause, because the manifest records the exclusion but not the failure it prevents. If your environment already carries one of the excluded versions, check whether the reason is a runtime bug before deciding to upgrade.
Windows installs PyTorch first, from the stable wheel index
The install path branches by platform, and the branch is not cosmetic:
pip install torch -f https://download.pytorch.org/whl/torch_stable.html
pip install pytorch-forecasting
conda install pytorch-forecasting pytorch -c pytorch>=1.7 -c conda-forge
pip install pytorch-forecasting[mqf2]
On Windows the instruction is to install PyTorch first, using the stable wheel index rather than the default one, and only then the forecasting package. Elsewhere the single command pip install pytorch-forecasting is enough. The conda route exists as an alternative, and the text notes a change in where each piece comes from: the package itself now installs from the conda-forge channel while PyTorch installs from the pytorch channel, which is why the command names both. The last line is the extra for the MQF2 multivariate quantile loss, and it is the first hint that this project separates its optional pieces deliberately rather than shipping one dependency set.
Tuning, graph and mqf2 all live outside the base install
The optional dependency section names its own sets in comments, and the list is worth reading as a map of what the base install does not give you. There is all_extras for everything soft, then granular sets: tuning for hyperparameter tuning through optuna, mqf2 for the multivariate quantile loss, and graph for graph based forecasting. Two more sets exist for contributors rather than users, one called dev and one for continuous integration that the comments explicitly mark as not for users. The consequence is direct and easy to hit. The headline feature of hyperparameter tuning is advertised in the package description, but optuna is not in the core dependencies, so a fresh install cannot run a tuning tutorial until you add the extra. Graph based forecasting is the same story. The pattern is defensible, since optuna and graph libraries pull their own trees, but it means the advertised surface and the installed surface differ, and the fix is always the same one: read which extra the feature needs before planning around it.
The dependency is lightning and the imports are lightning.pytorch
The prose refers to PyTorch Lightning and pytorch-lightning, and the usage example imports the newer namespace:
import lightning.pytorch as pl
from lightning.pytorch.loggers import TensorBoardLogger
from lightning.pytorch.callbacks import EarlyStopping, LearningRateMonitor
from pytorch_forecasting import TimeSeriesDataSet, TemporalFusionTransformer, QuantileLoss
from lightning.pytorch.tuner import Tuner
Three separate paths appear for the same framework: the human-readable name, the old pytorch_lightning import style that most tutorials and forum answers still use, and the lightning.pytorch package that the code here actually imports for the module, the TensorBoard logger, the callbacks and the tuner. That gap is where confusion comes from. Following an older tutorial that imports pytorch_lightning while this package requires lightning gives you either an import error or two Lightning installations in one environment, and the second case is worse because it fails later, deep inside a training run. Treat the import path in this example as the contract, and check what your environment already has before adding anything.
TimeSeriesDataSet is where your column decisions are made
Everything else in the package sits on top of one abstraction. The timeseries dataset class handles variable transformations, missing values, randomized subsampling and multiple history lengths, and the usage path is explicit about the order of operations: you bring a pandas DataFrame, it is first converted to a TimeSeriesDataSet, and networks are then trained with the Lightning Trainer on that dataset. The base model class adds basic training with TensorBoard logging and generic visualizations such as actual versus predictions and dependency plots. This ordering has a practical consequence. Column naming, which column is the target, which column identifies the series, and how far into the future the model is allowed to see are all decided during that conversion, so a mistake there shows up as a confusing failure at training time rather than as a configuration error. If you are porting an existing pipeline, spend the time on the dataset construction rather than on the architecture, and use the dependency plots the base class already produces to see whether the history windows look the way you intended.
Two of the shipped models exist to lose to something
The model list mixes research architectures with deliberately simple references. Temporal Fusion Transformers, N-BEATS, N-HiTS, DeepAR and PatchTST are the named deep architectures, alongside LSTM and GRU networks and an MLP on the decoder for baselining. Then there is a model that always predicts the latest known value, which is persistence. The README attaches benchmark claims to the research models, citing Temporal Fusion Transformers as outperforming DeepAR by 36 to 69 percent, N-BEATS as having outperformed other methods including ensembles of traditional statistical methods in the M4 competition when used as an ensemble, and N-HiTS as consistently beating N-BEATS with support for covariates and a bias toward long-horizon work. Those numbers come from the cited papers rather than from this repository, so treat them as motivation. The practical use of the persistence model is sharper than any of them: if a trained network does not beat the last known value on your own series, the extra architecture is buying you nothing.
Python 3.10 to 3.14, and the examples carry the real usage detail
The supported window is explicit: requires-python is >=3.10,<3.15, and the classifiers name 3.10, 3.11, 3.12, 3.13 and 3.14 individually, so the upper bound is a decision rather than an accident of packaging. The version in the manifest is 1.8.0, matching the published v1.8.0, and a comment notes that the version field is replaced automatically at release time, which is why you should read it from the release rather than from a checkout. The repository layout follows the sktime project conventions, with GOVERNANCE.md, CODEOWNERS, CODE_OF_CONDUCT.md and CONTRIBUTING.md at the root alongside CHANGELOG.md, codecov.yml, .readthedocs.yml and a pre-commit config. Under examples/ sit ar.py, nbeats.py, nbeats_with_kan.py, stallion.py and a data directory, plus extension_templates/, build_tools/, docs/ and tests/. Those example scripts are where the usable detail lives, including a variant named nbeats_with_kan.py that the README never explains.
Editorial conclusion
PyTorch Forecasting is a good fit if your forecasting problem has several related series, covariates and a quantile or multi-horizon loss, and if you are already working in the Lightning ecosystem, since the dataset class and the Trainer carry most of the ergonomics. It is a poor fit for a single short univariate series, where the last-value baseline it ships may already be hard to beat, and for anyone who wants a dependency-light install, since torch and lightning arrive regardless. Before you pin it, check three things against your own environment: that your Python sits inside the supported window of 3.10 up to but not including 3.15, that your torch and lightning releases are not on the excluded list, and that you install the extra matching your task, since tuning, mqf2 and graph all live outside the base install.
Frequently asked questions
what is pytorch forecasting
A PyTorch-based package for time series forecasting that provides a high-level API and is built on PyTorch Lightning so training works on CPU or single and multiple GPUs with automatic logging. It supplies a TimeSeriesDataSet, a base model class with TensorBoard logging and plots, multi-horizon metrics, optuna tuning, and architectures including TemporalFusionTransformer, N-BEATS, N-HiTS, DeepAR and PatchTST.
how to install pytorch forecasting
On Windows, install PyTorch first with pip install torch -f https://download.pytorch.org/whl/torch_stable.html, then run pip install pytorch-forecasting. Elsewhere the single pip command is enough. Conda users can run conda install pytorch-forecasting pytorch -c pytorch>=1.7 -c conda-forge, with the package coming from conda-forge and PyTorch from the pytorch channel. The MQF2 loss needs pip install pytorch-forecasting[mqf2].
pytorch forecasting vs darts
The README does not compare PyTorch Forecasting with darts. What the project states about itself is the design goal: a high-level API with maximum flexibility for professionals and reasonable defaults for beginners, built on pytorch-lightning for CPU, single and multiple GPUs out of the box.
pytorch forecasting vs nixtla
The README does not compare PyTorch Forecasting with nixtla or other libraries. The verifiable constraints are the version window, requires-python >=3.10,<3.15 with classifiers for 3.10 through 3.14, and the pinned dependencies including torch >=2.0.0,!=2.0.1,<3.0.0 and lightning >=2.0.0, !=2.6.2, != 2.6.3, <2.7.0.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sktime-pytorch-forecasting)Star history chart for your README
[](https://hysenlabs.com/projects/sktime-pytorch-forecasting)Was this useful?