the Skywork-R1V readme documents V3 while the tree already holds V4
Skywork-R1V is an advanced multimodal AI model series developed by Skywork AI, specializing in vision-language reasoning.
At a glance
- What is it?
- Weights and inference code for a multimodal reasoning model series, with sixteen benchmark rows, two inference paths, two conda environments, and an explicit note that the base model is another lab's. The repository name carries no version, the title carries one, the tree carries a different one, and the homepage points at the paper for the first.
- Who is it for?
- Use this if you need an openly licensed multimodal reasoning model with reproducible evaluation code and you have the hardware for it, since the readme is unusually complete on the two things that usually get glossed over, which is where the numbers came from and what the code licence does and does not cover. Two things to check before you start.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 110 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
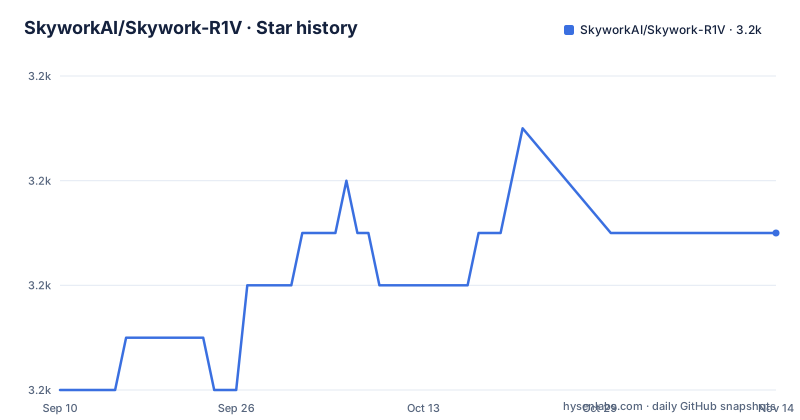
- SkyworkAI/Skywork-R1V3,173 ★ · +3
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| SkyworkAI/Skywork-R1V | 3.2k | 3.2k |
3 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The readme documents V3 and the tree holds V4
Three version identities live in this repository and they do not match. The repository is named for the series with no version in it. The readme's heading and its two header links are for version 3, including a report PDF for that version. The top level of the tree contains a report PDF for version 3, a report PDF for version 4, and a directory named for version 4 alongside the inference and evaluation directories. So the newest model is present in the checkout and entirely absent from the documentation. The news section, which is dated and reverse chronological, stops in July 2025 at the version 3 announcement, while the default branch received a push on 29 July 2026. Nothing in the file describes what version 4 is, whether weights are published for it, or what changed. If you are here to evaluate the model in the tree rather than the one in the readme, you are working from the announcements for the previous release.
The homepage points at the first version's paper
The repository's canonical link is a preprint abstract for the original release, the first version from March 2025. That is three or four versions before the one the readme describes and several before the one in the tree. It is a small thing in isolation, since a preprint link is a reasonable thing to want as the canonical reference, and it is the right reference if you want the original method. It is the wrong reference if you clicked through expecting to find out what the model in this checkout actually is, and the file does not help you there: the citation section lists a separate technical report for version 3 with its own preprint identifier and a long author list, and the earlier releases each have their own paper too. So there are at least three preprint identifiers associated with this repository and no line in the file that says which one describes the code you have.
Four versions in four months, two with a single-card variant
Read the news section as a release cadence and it is unusually fast. The first version landed in March 2025, described as the first industry open-sourced multimodal reasoning model with visual chain-of-thought, and a quantised variant of it followed eight days later with the note that it supports single card inference above thirty gigabytes of memory. A preprint followed in April, the second version in late April, a quantised variant of that two days later, and version 3 in July. So four versions in about four months, and for two of them the project also published a quantised build explicitly so that people without a multi card machine could run the thing. That detail is the most practically useful line in the news section, because a 38B model on one card is a different proposition from the same model distributed across four, and the readme's own inference examples show both, with a visible device list and a tensor parallel size argument.
The table prints its losses and marks its own numbers
The evaluation section is sixteen rows across general, mathematics, logic and physics, against four openly available models and two proprietary ones, and it is worth reading closely because of what it chooses to print. The model takes the top spot on ten of the sixteen rows. On the other six it is beaten, and those six rows are printed with exactly the same prominence as the wins, with the competitor's score in bold. A trophy is defined as top performer for this model on that benchmark, so it is a claim about the column rather than about the field. Then there is a legend: an asterisk marks a result that came from the authors' own evaluation framework. Almost every cell carrying an asterisk is a cell where the authors measured a competitor themselves, and the rows the model loses are largely the rows where no asterisk appears. That is a table with its own weaknesses marked, which is rarer than a table of wins.
The base model belongs to another lab and the file says so
The licence section ends by naming the foundation. This project uses a thirty eight billion parameter openly available vision-language model from a different organisation as its base model, and states that the base model is under the MIT licence. That single sentence does two useful things. It tells you that the capability you are evaluating is substantially inherited rather than trained from nothing, which changes how you read a benchmark comparison, because you are comparing a post-training recipe rather than a whole model. And it tells you the licence of the thing underneath, which is not required by the file and is the first thing a redistribution question turns on. It is also the reason the project can offer a permissive grant on its own code without that grant being in tension with anyone else's terms.
The licence sentence names the code repository, not the weights
The licence block is written as four statements with tick marks: commercial use permitted, modification allowed, distribution allowed, no liability. It is a plain and generous summary, and then there is a word doing careful work. The sentence says this code repository is licensed under the MIT licence, and the link points into the repository. The model weights do not live in the repository; they live on a separate hosting site, and every announcement in the news section is a link to that site rather than a file here. So the grant is scoped to the code, and the thing most people downloading this project actually want, the weights, is licensed on a page the readme links without quoting. That is a normal and defensible arrangement, and it is also the sentence to read carefully if you are planning to redistribute the weights rather than only the inference code. The repository itself contains no weights, only the inference and evaluation code and the two report PDFs.
Two conda environments and two setup scripts for one model
The local run section is four steps and splits cleanly in two from the second step onward, because the project supports two inference stacks and treats them as separate environments. One environment, on Python 3.10, is for the Transformers path and is set up by a shell script in the inference directory. A second environment, also on 3.10, is for the accelerated serving and evaluation path and is set up by a script inside the evaluation directory. The two entry points take the same three arguments, a model path, a list of image paths and a question, and the difference is a tensor parallel size on the second. So the inference code is duplicated across two runners rather than abstracted behind one, which means a model path that works in one environment is the only thing guaranteed to work in the other if the third party stack is the one you already have. Nothing in the file says which to prefer, and nothing in it mentions hardware beyond the two examples and the news section's note about a single card. The first two steps are the whole of the setup, and neither is optional:
git clone https://github.com/SkyworkAI/Skywork-R1V.git
cd skywork-r1v/inference
conda create -n r1-v python=3.10 && conda activate r1-v
bash setup.sh
Editorial conclusion
Use this if you need an openly licensed multimodal reasoning model with reproducible evaluation code and you have the hardware for it, since the readme is unusually complete on the two things that usually get glossed over, which is where the numbers came from and what the code licence does and does not cover. Two things to check before you start. Version identity, because the repository name, the page title, the tree contents and the homepage link each point at a different version, and the newest model in the tree has no announcement, no weights link and no report link in the file, so the readme is one release behind what you have cloned. And the evaluation script, which the file does provide, since sixteen benchmark rows with the authors' own numbers starred separately from published ones means the results are reproducible rather than asserted, and reproducing them is the only way to compare against a model measured on a different harness.
Frequently asked questions
What does the Skywork-R1V repository contain?
The inference code and evaluation harness for a multimodal reasoning model series, plus two report PDFs. The model weights are not in the repository; they are published on a separate hosting site, and every announcement in the file links there rather than to a file in the tree.
How do I run Skywork-R1V locally?
Clone the repository, change into the inference directory, create a conda environment on Python 3.10 and run the setup script. Then run the inference script with a model path, one or more image paths and a question. A second conda environment and a setup script inside the evaluation directory cover the accelerated serving path, whose entry point takes the same arguments plus a tensor parallel size.
Which Skywork model version does the repository document?
Version 3, in the readme's heading, its header links and its news section, which stops in July 2025. The repository tree also contains a report PDF and a directory for version 4, which the readme does not mention, and the default branch received a push on 29 July 2026.
What model is Skywork-R1V built on and under what licence?
A thirty eight billion parameter vision-language model from another organisation is used as the base model, and the file states that base model is MIT licensed. The repository's own code is MIT licensed, described in four terms: commercial use permitted, modification allowed, distribution allowed, no liability.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/skyworkai-skywork-r1v)Star history chart for your README
[](https://hysenlabs.com/projects/skyworkai-skywork-r1v)Was this useful?