SpeechBrain's recipes, YAML configs, and the gaps between them
A PyTorch-based Speech Toolkit
At a glance
- What is it?
- SpeechBrain is an Apache-2.0 PyTorch toolkit whose selling point is a YAML file plus a Python script per task, with 200+ recipes and 100+ pretrained models on HuggingFace. That design is convenient for research code and uneven in support: the base install omits pytest and transformers, the clone path tracks develop rather than a release, and the two documented ways to start a run do not match.
- Who is it for?
- SpeechBrain suits a group that wants to start from a maintained recipe and a YAML config instead of writing its own training loop, and it fits poorly with a team that needs a base install that already carries pytest and transformers.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 32 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
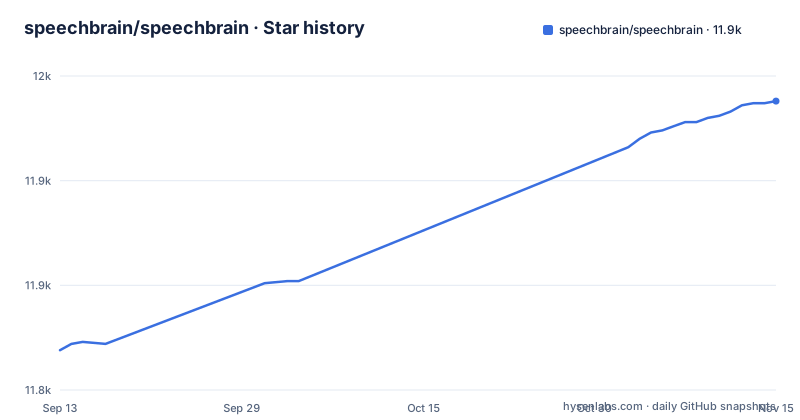
- speechbrain/speechbrain11,938 ★ · +119
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| speechbrain/speechbrain | 11.8k | 11.9k |
119 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One YAML file decides the run and where results land
Training here is a YAML file plus a Python script, and the project gives one invocation for any task:
python train.py hparams/train.yamlHyperparameters live in the YAML, the training process is orchestrated through the Python script, and the project states it kept a consistent code structure across tasks. So an ASR run and a speaker verification run share their surrounding code and differ in the config. The part with consequences for you is the output location. The walkthrough says results are saved in the `output_folder` specified in the YAML file, which means the destination is a key in a file you did not write, not a flag on the command line. Relocating checkpoints, or pointing them at scratch storage that gets cleaned, means editing the config. Note also that, for replicability, the project hosts its training logs and checkpoints on Dropbox; your own run's results go to `output_folder`.
Two documented entry points with two script names
The training section and the quick start do not agree on the command. The training section prints the single line shown above for any task. The quick start tells you to enter a recipe directory first and then run a differently named script against a differently named config:
cd recipes/<dataset>/<task>/
python experiment.py params.yaml
The consequences are practical. The script names differ (`train.py` against `experiment.py`) and so do the config paths (`hparams/train.yaml` against `params.yaml`); the repository root contains neither script, so you have to be in the right directory first. Settle which route you are on before you start debugging a missing file.
The verification commands need pytest, which the base install omits
The installation check is two commands:
pytest tests
pytest --doctest-modules speechbrain
`pip install speechbrain` satisfies neither on its own. pytest is absent from the dependency list in `pyproject.toml`; it appears only in the optional dev group, pinned to `pytest==7.4.0`, and it is not named in the rest of `requirements.txt` either. For a PyPI user there is a second obstacle: `[tool.setuptools.packages.find]` sets `include = ["speechbrain", "speechbrain.*"]`, so the tests directory is not packaged at all. That means the documented check needs a pytest install and a source checkout, and a reader who follows the PyPI path and then the test instructions hits a missing executable before reaching any assertion of the library's own.
The editable install drags in lint tooling
The two install paths do not build the same environment. PyPI is one line, `pip install speechbrain`. The GitHub path is four:
git clone https://github.com/speechbrain/speechbrain.git
cd speechbrain
pip install -r requirements.txt
pip install --editable .
`requirements.txt` opens with `-r lint-requirements.txt` and then adds `pandas`, `pre-commit`, and `transformers` on top of the shared runtime list. The root holds `.yamllint.yaml`, `.pre-commit-config.yaml`, `.pre-push-config.yaml`, and a dictionary file, so the development path is built around a style gate. For a team, that means the colleague who cloned carries lint and formatting packages and the colleague who used PyPI does not, and a difference in a traceback can be a difference in dependencies rather than in SpeechBrain. The `--editable` flag does at least make changes inside the `speechbrain` package take effect without a reinstall.
Cloning gives you develop, not the v1.1.1 wheel
The default branch is `develop`, and the GitHub instructions do not mention tags. The release list shows v1.1.2 on 2026-10-14, v1.1.1 on 2026-08-27, and v1.1.0 on 2026-03-30, and the last push to the default branch was on 2026-10-14, the same day as v1.1.2. An editable install from a fresh clone is therefore branch head code, which is not the same artifact a colleague gets from `pip install speechbrain`. A second detail in `pyproject.toml` compounds it: the version is dynamic, read from `speechbrain/version.txt` at build time instead of being written in the project table, and `version.txt` is listed under package data. A source tree assembled by hand without that file has no version to declare, and a bug report should state which of the two paths the reporter used.
Over 100 pretrained models with no documented offline route
The pretrained catalogue lives on HuggingFace, more than 100 models, and the smallest inference example is three lines:
from speechbrain.inference import EncoderDecoderASR

asr_model = EncoderDecoderASR.from_hparams(source="speechbrain/asr-conformer-transformerlm-librispeech", savedir="pretrained_models/asr-transformer-transformerlm-librispeech")
asr_model.transcribe_file("speechbrain/asr-conformer-transformerlm-librispeech/example.wav")
`source` is a hub identifier, `savedir` is a local directory, and `huggingface_hub>=0.8.0` is a hard runtime dependency. The first call needs a route to huggingface.co, so the example as printed depends on that route. `savedir` is also a real directory, so the example writes a whole model tree into your working directory and anyone comparing environments has to account for that folder. The weights are hosted by their own maintainers, not by this repository.
Fine-tuning borrowed models needs a package the base install leaves out
The fine-tuning list is specific: Whisper, Wav2Vec2, WavLM, Hubert, GPT2, and Llama2, all pulled from HuggingFace and trained inside the toolkit, with the claim that models on HuggingFace can be easily plugged in and fine-tuned. The dependency picture is thinner than that claim. `pyproject.toml` lists `huggingface_hub` at runtime but no `transformers`; `transformers>=4.30.0` sits in `requirements.txt` and in the dev group instead. A reader who installs from PyPI and then follows a fine-tuning recipe is one package short, and may need to install `transformers` separately. Because the base weights live under other people's model ids, a checkpoint that changes upstream changes what your run trains from, with nothing here to pin it.
A wide recipe catalogue with no per-recipe support status
The scope claim is breadth: over 200 competitive training recipes, more than 40 datasets, 20 speech and text tasks, more than 100 pretrained models, and over 30 tutorials where every class or function is meant to have explanations and runnable examples. The stated span covers speech recognition, speaker recognition, speech enhancement, speech separation, language modeling, and dialogue, with EEG added later through the MOABB benchmarks. Breadth is not a support promise. A count of 200 tells you where to look and not what comes back. For evaluation work that matters: a baseline is only as good as the recipe you copied, and a recipe you cannot audit is a number you cannot defend.
Editorial conclusion
SpeechBrain suits a group that wants to start from a maintained recipe and a YAML config instead of writing its own training loop, and it fits poorly with a team that needs a base install that already carries pytest and transformers. Check three things before committing: whether your clone sits on develop or on the latest release (v1.1.2), which recipe and checkpoint your numbers will be compared against, and whether your machines can reach the HuggingFace hub and, if you want the project's published logs and checkpoints, the Dropbox host they are stored on.
Frequently asked questions
what is speechbrain
SpeechBrain is an open-source PyTorch toolkit for speech and text processing, described as built for Conversational AI. Its listed areas are speech recognition, speaker recognition, speech enhancement, speech separation, language modeling, dialogue, and an EEG modality.
how to install speechbrain
From PyPI with `pip install speechbrain`, or clone the repository and run `pip install -r requirements.txt` followed by `pip install --editable .`. The GitHub path is the one recommended for experiments and for customizing the toolkit.
how to use speechbrain
Import it as `import speechbrain as sb`, then enter a recipe directory and run `python experiment.py params.yaml`. Results are written to the `output_folder` named inside that YAML file.
is speechbrain free
It is an open-source project carrying the Apache-2.0 license in pyproject.toml, and the code is hosted on GitHub. The pretrained models and checkpoints are separate downloads hosted on HuggingFace and Dropbox.
speechbrain vs whisper
Whisper appears in the project as a pretrained model you plug in and fine-tune inside SpeechBrain, not as a competing system being weighed against it. No accuracy or speed comparison between the two is given.
Can deep learning be used for speech recognition?
The stated vision says speech processing and NLP are close now because of deep learning, and that a well-designed neural network plus large datasets is what you need. Speech recognition is one of the covered tasks.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/speechbrain-speechbrain)Star history chart for your README
[](https://hysenlabs.com/projects/speechbrain-speechbrain)Was this useful?