PixelRAG Replaces Text Parsing With Screenshot Tiles, One Stage at a Time
https://arxiv.org/abs/2606.28344. The end of web parsing. The beginning of scalable pixel-native search. link: https://pixelrag.ai/
At a glance
- What is it?
- PixelRAG is the official codebase for the PIXELRAG paper: it renders web pages, PDFs, and images into screenshot tiles and retrieves over those images with a LoRA fine-tuned Qwen3-VL-Embedding model, split into a torch-free core install and opt-in extras for embedding and search.
- Who is it for?
- Use PixelRAG when the answer lives in a chart, table, or layout that HTML parsing discards, and when you can either call the hosted Wikipedia index or afford disk for a local FAISS index. Check first which extra your step needs, since the core install carries no torch, and keep pixelshot on PATH if you plan to use the Claude or opencode plugin.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
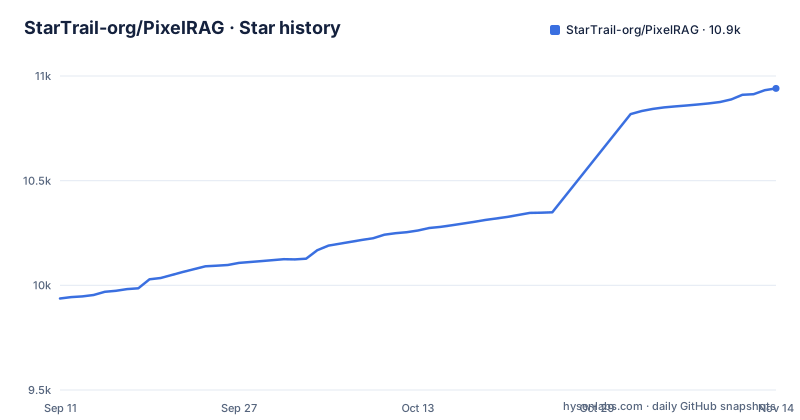
Star history
- StarTrail-org/PixelRAG10,941 ★ · +1,004
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| StarTrail-org/PixelRAG | 9.9k | 10.9k |
1,004 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The retrieval unit is a rendered tile, not a parsed text chunk
Text-based RAG turns a page into text chunks and loses the table, so a reader model cannot find a number that was only ever drawn. PixelRAG renders the document to screenshot tiles, retrieves the tile, and lets the reader take the value off the image. Capture is one command against any page or document:
pixelshot https://en.wikipedia.org/wiki/Python --output ./tilesThe tiles land in the output directory you name, and everything downstream treats those images as the corpus. Two pieces make that work: rendering documents to images instead of parsing them to text, and a Qwen3-VL-Embedding model, LoRA fine-tuned on screenshot data, that maps page images into a space where visual content is retrievable. The paper's title claims that web screenshots beat text for retrieval-augmented generation.
The core install ships no torch, and every ML stage is an extra
The packaging is split on purpose. A comment in pyproject.toml says the core stays light, rendering and screenshots only with no torch, so the pixelshot command and the pixelrag umbrella run on that alone. The core dependency list is pillow, websockets, pymupdf, pyturbojpeg, cef-capi-py, anthropic, numpy, pyyaml, and tqdm, with requires-python set to >=3.12. Everything heavier sits in optional groups: embed pulls torch, torchvision, transformers, and faiss-cpu; serve adds fastapi, uvicorn, qwen-vl-utils, and pydantic on top; index is defined as embed plus markdown; and qdrant names qdrant-client. The consequence for a first run is that
pip install pixelraggives you capture only, and a search attempt fails until you pick the extra that carries the stage you need.
The Claude plugin is a local command with no server behind it
The renderer also ships as a Claude Code plugin called the pixelbrowse skill, and installing it is two commands plus the CLI itself:
uv tool install pixelrag                            # pixelshot on PATH (or: pipx install pixelrag)
claude plugin marketplace add StarTrail-org/PixelRAG
claude plugin install pixelbrowse@pixelrag-plugins
The README is explicit about the failure mode here: a plain pip install into a project venv may leave pixelshot off PATH, which is why uv tool or pipx is suggested to keep it isolated yet available. With it on PATH you ask for a screenshot in words, for example:
claude -p "screenshot https://news.ycombinator.com and summarize the top stories"
claude -p "screenshot https://arxiv.org/abs/2404.12387 and explain the key findings"
There is an interactive slash command too, /screenshot followed by a URL. No MCP server and no backend are involved, the skill just calls pixelshot, which drives Playwright over CDP on your own machine. So the plugin inherits every gap in your local rendering setup rather than being isolated from it.
opencode users get the same skill through an npm plugin
The screenshot capability is not locked to one agent. The repository ships an opencode plugin published as the npm package @startrail/pixelbrowse, and the configuration is a two key file:
{
  "$schema": "https://opencode.ai/config.json",
  "plugin": ["@startrail/pixelbrowse"]
}
The npm side of this repository is otherwise thin, since the root package.json carries a single dependency on remark-gfm, which is documentation tooling rather than runtime code. The requirement stated for the opencode path is the same one as for Claude: pixelshot has to be on PATH. A reader comparing the two integrations should notice that neither ships rendering as a service, so both inherit your Playwright, browser, and PDF stack, and a machine without those does not get a degraded version of the skill but no skill at all.
One hosted POST covers 8.28M Wikipedia pages and nothing else
The quickest way to see the idea work needs no index of your own. The hosted endpoint serves a pre-built index of 8.28M Wikipedia pages with no setup and no API key, and a search is a single request:
curl -X POST https://api.pixelrag.ai/search \
  -H "Content-Type: application/json" \
  -d '{"queries": [{"text": "What is the capital of France?"}], "n_docs": 5}'
It even accepts an image as the query rather than text, which the docs call visual search, and there is a status page at api.pixelrag.ai/status plus a browser version at pixelrag.ai. A Colab notebook in demos/ renders a page and searches the hosted index with the images inline. The limit is scope rather than capability: what that endpoint indexes is Wikipedia, so any corpus of your own needs the local pipeline below, and if you need the same behavior in production you are back to serving an index yourself.
A local index means downloading roughly 217G from Hugging Face
Running your own index starts with the serve extra and a download. The dataset repository StarTrail-org/pixelrag-faiss-indexes holds four FAISS indexes, described as base and LoRA Wikipedia pixel, Wikipedia text, and news pixel, and the base one is the one the README points at at about 217G:
huggingface-cli download StarTrail-org/pixelrag-faiss-indexes \
--repo-type dataset --include "search_index_normed_v2/*" --local-dir ./indexpixelrag serve --index-dir ./index/search_index_normed_v2 --port 30001Queries then go to the same search path on your own port, which means the served index directory, the model that embeds the query image, and the extra you installed all have to agree. Two costs follow from the listing. Disk is not a footnote when the base index alone is hundreds of gigabytes, and the four index variants mean choosing between a pixel index and a text index, or between a base and a LoRA variant, is a decision to make up front; the README example downloads only the base one.
Fine-tuning lives in a separate uv project with pinned CUDA versions
The training stage is not part of the installable package. It is a separate uv project with its own pinned environment, torch==2.9.1+cu129, transformers==4.57.1, and cuDNN 9.20, and the instruction is to install it from inside train/ rather than from the repository root. The dependency graph is drawn as index linked to both render and embed, serve sitting independently, and train reaching serve over HTTP. So if your goal is to adapt the embedder to your own screenshots, you are maintaining a second environment with exact CUDA pins while the pip package stays on its >=3.12 core, and the two can drift apart without either one telling you.
Rendering depends on a patched headless Chrome in the tree
Capture is the one stage that owns a browser. The repository carries a chromium directory and a chromium-screenshot-patches.diff, and one release in the history is a patched headless Chrome 150.0.7844.0 published on 2026-06-01, alongside v0.4.0 on 2026-07-16 and v0.3.0 on 2026-06-23, with the last push dated 2026-10-30. The rendering stack around it is visible in the core dependencies, with pymupdf for documents, cef-capi-py, pyturbojpeg for image work, and pillow, driven through Playwright over CDP. The consequence is a rendering pipeline tied to a specific browser build and a patch file: when the pinned Chrome moves, the patch has to follow it, and a page that renders differently in your local browser is a rendering bug in the retrieval chain rather than a display glitch.
Editorial conclusion
Use PixelRAG when the answer lives in a chart, table, or layout that HTML parsing discards, and when you can either call the hosted Wikipedia index or afford disk for a local FAISS index. Check first which extra your step needs, since the core install carries no torch, and keep pixelshot on PATH if you plan to use the Claude or opencode plugin. Skip it if you need a text-first retrieval pipeline over your own documents, or if you want to fine-tune the embedder without maintaining a second pinned environment.
Frequently asked questions
what is pixelrag
PixelRAG is the official codebase for the PIXELRAG paper, Web Screenshots Beat Text for Retrieval-Augmented Generation. It renders web pages, PDFs, and images into screenshot tiles and retrieves over those images, and the core package installs with pip install pixelrag.
What is pixel in AI?
In PixelRAG the image is the retrieval unit rather than the character. Documents are rendered to screenshot tiles, and a Qwen3-VL-Embedding model, LoRA fine-tuned on screenshot data, embeds those page images so tables, charts, and layout remain queryable.
What does pixel mean in coding?
Nothing in the pipeline addresses an individual pixel. The unit that gets captured, embedded, and retrieved is a rendered tile produced by the pixelshot command, which turns a page or document into image files with an output directory.
What is a pixel in simple terms?
A pixel is one point in an image, and PixelRAG treats a whole screenshot of a page as the thing a reader model looks at. Its claim is that the reader can answer questions about tables, charts, and infographics that text parsing discards.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/startrail-org-pixelrag)Star history chart for your README
[](https://hysenlabs.com/projects/startrail-org-pixelrag)Was this useful?