RepoBrain: four times faster on queries, two hours on the cold build
🧠 RepoBrain (formerly Antigravity) - Give your repo a brain. ChatGPT for your codebase: works in Claude Code, Cursor, Codex, Windsurf & more.
At a glance
- What is it?
- A cross-IDE repository knowledge engine that generates per-module documentation with an agent cluster and routes questions to the module that owns the answer. Its published benchmark wins decisively on query time and loses decisively on build time, and the README says the two workloads are not equivalent.
- Who is it for?
- RepoBrain fits someone who asks the same questions about a large repository from several editors and is willing to pay a build cost once per checkout to get answers with file paths attached. It does not fit a workflow that needs a fresh index instantly, and it does not fit someone who wants an auditable answer without trusting a generated knowledge layer.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
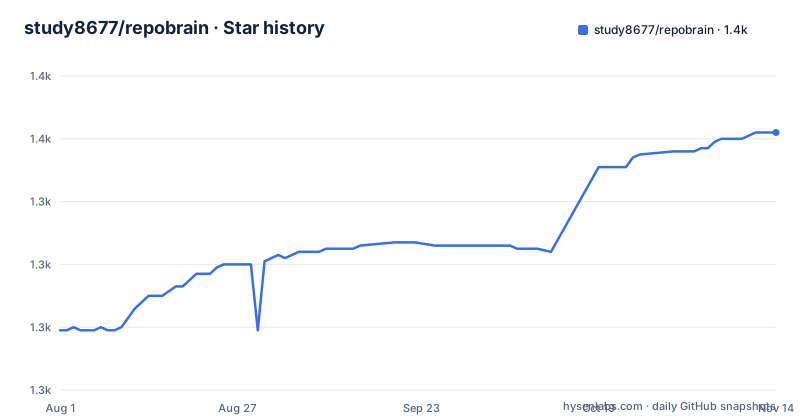
Star history
- study8677/repobrain1,362 ★ · +63
| Repository | 2026-08-01 | 2026-11-14 |
|---|---|---|
| study8677/repobrain | 1.3k | 1.4k |
63 Stars in the last 105 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The speed claim comes from the query phase only
The comparison table is dated and specific: four projects, Flask, ripgrep, Vite and Prometheus, twenty questions repeated three times each, with the same source access and the same model route for both products.
On the metrics that matter while you work, RepoBrain wins. Weighted semantic accuracy of 95.83 percent against 84.17 percent, sixty successful queries out of sixty against fifty-three, and query time of 5,106 seconds against 20,621 seconds. That last pair is where the headline four-fold figure comes from.
The cold build row is where it goes the other way. RepoBrain's is 7,420 seconds, which is a little over two hours, against 9.58 seconds for the static code-graph alternative. That is three orders of magnitude, and no amount of query speed compensates inside a single session.
The total row makes the trade explicit: cold build plus all scored queries is 12,527 seconds against 20,630 seconds, so on combined time the lead is about one and a half times rather than four.
The README is honest about why. Cold builds compare full AI knowledge generation against static code-graph indexing, and it says those are not equivalent workloads. It also states that failures count as incorrect and that the results apply to that locked experiment only. That is the right set of caveats, and they are also the reason to run the comparison yourself.
The project has three names and three READMEs
RepoBrain was previously called the Antigravity Workspace Template, and the rename is stated in the header of the README as the same project under a new name.
The rename happened between release 0.2.1 and release 0.3.0, and both names are still visible in the release history: the 0.2.1 entry is titled with the old name and the 0.3.0 and 0.3.1 entries with the new one.
The repository's own metadata has not caught up. The homepage field points at a documentation site under the old repository name, while the deep wiki badge inside the README points at the new one. So a visitor arriving from the repository page lands on documentation for the previous name, and the two pages are presumably the same project at different URLs.
Documentation exists in three languages: the English README plus Chinese and Spanish versions, all at the repository root.
None of this is a functional problem, and for a tool whose whole value is being the source of truth for a codebase, stale names are worth cleaning up. The search terms people use for this project are also the ones the rename creates confusion around, since the older name describes a template rather than an engine.
The install document is written to be read by an assistant
The fastest install path is a single line the user pastes into an AI assistant:
/plugin marketplace add study8677/repobrain
/plugin install repobrain@repobrain
/repobrain:rb-setup
/repobrain:rb-refresh
/repobrain:rb-ask "How does auth work?"
The alternative to all of that is a line of text telling the assistant to fetch an install document from the repository and follow it, with the premise that anyone already sitting in a logged-in editor does not need to touch pip or an API key.
Both paths converge on the same idea, which is worth stating plainly because it is unusual: the setup step can use a local command line tool you have already signed into, so no API key is needed for the backend. The setup command is interactive, asking whether to use a logged-in local tool or to paste a key, and it writes the result to an environment file.
For the manual path, the environment file takes an OpenAI-compatible base URL, an API key, a model name and a timeout in seconds for the ask command.
The pattern to be aware of is that an agent is asked to fetch instructions from a URL and execute them during installation. That is convenient and it is also the shape of a supply chain risk, so it is the kind of thing worth deciding about deliberately rather than by reflex.
Codex needs manual steps because its hooks are not supported
Installation differs by host, and the difference is documented rather than glossed over.
For Claude Code the plugin marketplace path is recommended, and the command line tool and engine install themselves automatically during the first session. For Codex the engine has to be installed by hand, because that host's hooks are not yet supported. The manual steps install the engine subdirectory of the repository with pipx and then inject it into the app, which is a two-line sequence that exists because the plugin's command directory is discovered automatically rather than through hooks.
The commands themselves converge after that. The same four commands work in Codex without the namespace prefix, and if the Codex build supports the protocol, the MCP server is registered separately. The raw command line forms still work too, taking a workspace argument.
Two more paths exist. A manual install pulls the command line tool and the engine from two subdirectories of the same repository and then writes an environment file before building the knowledge base. A third path installs only the command line tool and does context files only, with no language model involved at all, which bootstraps editor entry files and leaves the dynamic knowledge in the project folder.
The structure that makes this possible is that the repository is not one Python package but a small monorepo with separate directories for the command line tool, the engine, the commands, the hooks and the skills. That is also why installation has to name a subdirectory.
A cluster writes the knowledge, a router reads it back
The mechanism has two halves, and both are agent-shaped.
The refresh command deploys a cluster in which each module of your codebase gets its own agent, and each of those agents produces a knowledge document. The ask command then routes a question to the agent responsible for the relevant module, and the answer comes back grounded in real code with file paths and line numbers.
The claim underneath both halves is that an agent's ceiling is the quality of context it can read, and the alternative it is arguing with is handing a coding assistant a repository-wide search and letting it hunt. The README's own comparison puts a five-thousand-line instruction file on one side, with the agent reading all of it and forgetting most, and on the other side a question routed to the module that owns the answer.
Four failure modes are named. Style corrections repeated because the agent forgets conventions, which the generated layer is supposed to fix by holding them in a conventions file. Onboarding a new codebase, where the refresh command lets the module agents learn each module. Switching editors, where one folder is read by all of them. And the how-does-this-work question, which is the case the router exists for.
The framing sentence is that this is files plus a live question answering engine rather than plugins, portable across any editor and any model. The knowledge folder is plain files, which is the part that ages well.
A key reseller recommendation sits above the install instructions
The first block of content in the README, above every installation instruction, is a recommendation for a third-party API key reseller, written in Chinese.
It is presented as a tested personal recommendation rather than an advertisement, states that the author uses it heavily in coding tools, claims one key reaches multiple models including a current frontier model, says model pricing is easy to adjust, and asserts the pricing is not watered down. The link carries a referral parameter, and a separate link points at a third party's guide for wiring the key up.
Everything in that block is the author's own claim, and the framing is at least explicit about what it is. But it is worth naming the structural point: a referral link sits above the install instructions of a tool whose entire purpose is producing answers about your codebase, and the same repository tells you to hand an assistant a URL and let it execute the install.
None of that makes the project worse. It does mean the README is doing two jobs at once, promoting the tool and promoting a reseller, and a reader who skims the top of the page gets the second one first.
The image copies the whole repository to run one binary
The container file is worth reading next to the install paths, because it shows what the project considers the runtime surface.
It builds in two stages on a slim Python image. The build stage copies the engine directory and installs it into the builder user's local tree. The runtime stage creates an unprivileged user with a fixed numeric identifier, copies that installed tree into the user's home directory, puts it on the path, copies the entire repository into the working directory, changes ownership, switches to that user, and runs the knowledge hub MCP server against the workspace.
Two observations. The runtime stage copies everything rather than only what the entry point needs, so the image carries the command line tool, the documentation, the benchmarks, the memory directory and the rest of the tree for a process whose job is to serve the protocol. And the entry point is the MCP server, not the refresh command, which means a container deployment expects the knowledge folder to be built beforehand.
The compose file matches that model. It mounts the memory directory, the artifacts directory and the generated knowledge folder, marks the environment file as optional, and passes through not only the OpenAI-compatible base URL, key and model but also a Google API key and a Gemini model name, which is the configuration counterpart of the logged-in-local-tool path in the setup command.
The repository root is similarly layered: three plugin manifest directories for different hosts, plus command, hook, skill, memory and specification directories, an agent memory file, a mission file, a server configuration file, two Dockerfiles including a sandbox variant, and three READMEs.
Editorial conclusion
RepoBrain fits someone who asks the same questions about a large repository from several editors and is willing to pay a build cost once per checkout to get answers with file paths attached. It does not fit a workflow that needs a fresh index instantly, and it does not fit someone who wants an auditable answer without trusting a generated knowledge layer. Verify four things before you rely on it. Read the benchmark the way it is written, because the four-fold speed claim comes from the query phase alone while the cold build takes over two hours against ten seconds for the alternative, and the README itself says the two builds are not equivalent workloads. Measure that build time on your own repository, since a per-module agent cluster scales with module count. Decide whether the sponsor block at the top of the README is acceptable in a project you depend on, since it recommends a third-party key reseller through a link carrying a referral parameter and the author states it is not an advertisement. And check which host you are installing for, because the Claude Code path auto-installs while the Codex path needs manual steps because that host's hooks are not yet supported. The project was formerly named Antigravity Workspace Template, both READMEs and release titles still carry both names, the newest release is v0.3.1 from 2026-07-10, and the last commit is dated 2026-09-09.
Frequently asked questions
What is RepoBrain?
A MIT licensed cross-IDE repository knowledge engine. A refresh command deploys a cluster of per-module agents that each read a module of your codebase and write a knowledge document into a .repobrain/ folder, and an ask command routes a question to the agent that owns the relevant module, answering with real code, file paths and line numbers.
How does RepoBrain compare to CodeGraph in its published benchmark?
In a dated comparison over four projects with twenty questions repeated three times, RepoBrain scored 95.83 percent weighted semantic accuracy against 84.17 percent, answered 60 of 60 queries against 53, and spent 5,106 seconds on queries against 20,621. Its cold build took 7,420 seconds against 9.58 seconds, and the README states the two build workloads are not equivalent.
How do I install RepoBrain for Codex CLI?
Manually, because Codex hooks are not yet supported. The engine subdirectory is installed with pipx from the repository and injected into the app. The plugin's commands directory is discovered automatically, so the same four commands work without the namespace prefix, and MCP server registration is a separate step if the Codex build supports it.
Does RepoBrain need an API key?
Not on every path. The setup command can use a local command line tool you have already signed into, which needs no key. The manual pip path expects an OpenAI-compatible base URL, API key, model name and an ask timeout in an environment file. A third path installs the command line tool alone for context files only and needs no language model at all.
What was RepoBrain called before?
The Antigravity Workspace Template, and the rename is stated in the README header as the same project under a new name. The releases show both: version 0.2.1 carries the old name and versions 0.3.0 and 0.3.1 the new one, while the repository's homepage metadata still points at documentation under the old name.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/study8677-repobrain)Star history chart for your README
[](https://hysenlabs.com/projects/study8677-repobrain)Was this useful?